icon.svg
Coin

1

free

Reddit Scraper

Extract 30+ data points from any Reddit subreddit, post, user or search — posts, comments, authors & subreddit metadata all in one run.

Download sample
users17 users
runs2656 runs

Trusted worldwide by the best

Export results from Reddit — right now

Extract

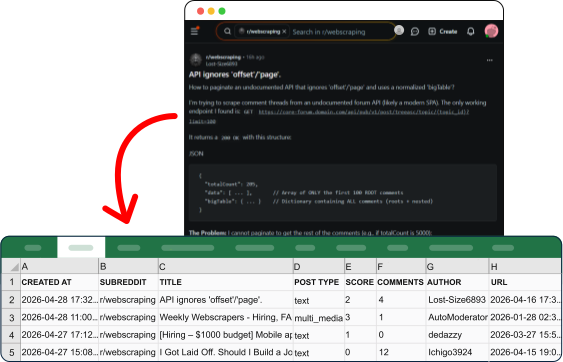
Paste any mix of Reddit subreddit, post, user profile or search URLs and extract 40+ data points per result — covering posts, comments, authors and subreddit metadata.

feature1.svg

Schedule

Automate Instagram data collection on daily, weekly, or monthly schedules.

image

Export

Export all Reel data to Google Sheets, email, or S3 — fully automated.

image

Built for Agents

Run it from your stack.
Or hand it to your agent.

Reddit Scraper ships with a Python SDK, a one-line CLI and a native MCP server your agents can plug into directly — no rate limits to dodge, no bot mitigation to bypass, no parsing errors to chase down.

# install once (Python 3.10+)
pip install lobstrio

# check your token
lobstr whoami

# find the scraper
lobstr crawlers search "Reddit"

# one call — launch, wait, download
lobstr go reddit-scraper \
  "<any Reddit URL>" \
  --param max_results=200 \
  -o results.csv

64 data attributes per result

Every scrape returns structured data you can export as CSV, JSON, or via API.

url

Canonical URL of the Reddit post

Export Reddit Results
Post Id

Reddit post ID (base36 identifier)

1stfrij
Export Reddit Results
title

Title of the Reddit post

Pourquoi y a-t-il si peu de femmes en informatique ?
Export Reddit Results
body

Text body of the post (for text posts)

Je bosse dans une ESN, ~1000 personnes. On est facilement à 90% d'hommes dans les équipes tech.
Export Reddit Results
Post Type

Type of post: text, image, link, video, etc.

text
Export Reddit Results
score

Upvote score of the post

19
Export Reddit Results
Comment Count

Number of comments on the post

126
Export Reddit Results
Award Count

Number of awards received by the post

0
Export Reddit Results
author

Username of the post author

Independent_Lynx715
Export Reddit Results
Author Id

Reddit ID of the post author

t2_19xe8ly1c0
Export Reddit Results
image

Fast

280 results per minute
Lightning-fast performance

image

Solid

99.95% task success rate
Dependable, reliable data every time

image

Cost-competitive

$0.5 per 1000 results
Top affordability worldwide

Live

Built to run.

Most scrapers break in silence. This one doesn't — and we show it, openly.

99.32%

incident-free runs · last 90 days

14
incidents · 90 days
100%
resolved
274 min
median time to fix
90 days agoToday
Operational
Degraded
Down
Resolved incident
Open incident
How we measure →

Tracked from every run. Incidents stay on the record even after they're fixed.

Simulator plan

Trusted by the best

Used obsessively by the data-hungry around the world

★★★★★
★★★★★
★★★★★
★★★★★
★★★★★
★★★★★

Frequently Asked Questions

Is it legal to scrape Reddit?

Yes — scraping public Reddit data is legal. Posts, comments, subreddit pages and user profiles you can see without logging in are public information. For the full breakdown, read our legal guide.

Do I need a Reddit account to use the scraper?

No login required. The Reddit Scraper works on public data only — no account sync, no cookies, no Chrome extension. Just paste URLs and run.

What data does the Reddit Scraper extract?

40+ data points per result. You get post titles, body text, scores, comment counts, authors, comment threads with depth and parent IDs, user karma and trophies, subreddit descriptions, rules, weekly active users and more — covering posts, comments, users and subreddits in a single run.

How fast is the Reddit Scraper?

Up to 280 results per minute. Run multiple subreddits, posts and searches in parallel to scale up further.

What inputs does the scraper accept?

Any mix of Reddit URLs. Drop in subreddit URLs, post URLs, user profile URLs or Reddit search URLs — the scraper auto-detects the type and extracts accordingly. No need to split runs by input type.

Does it scrape comments and replies?

Yes — full comment threads, replies included. Each comment comes with its body, author, score, depth, parent ID and post ID, so you can rebuild the complete conversation tree.

I scraped a subreddit but got no comments — why?

Feed post URLs, not subreddit URLs. A subreddit or search URL returns the post list only — comments come from post URLs (.../comments/...), which are already in your export's URL column. Relaunch from those to get the full comment tree.

Where do the comments appear in my export?

Separate rows, one per comment — not a JSON column. Everything shares one flat file tagged by the TYPE column: filter TYPE=comment and read the BODY column, with AUTHOR, SCORE, DEPTH and PARENT ID to rebuild the thread.

Can I scrape Reddit user profiles?

Yes. Paste a user URL (e.g. reddit.com/user/username) and you'll get post karma, comment karma, trophies, active subreddits, moderated subreddits and account creation date.

How many posts or comments can I scrape per run?

No hard limit. Scrape thousands of posts and comments in a single run — pagination is handled automatically. Scale by running multiple URLs in parallel or scheduling recurring runs.

Can I schedule recurring Reddit scrapes?

Yes — schedule runs hourly, daily or weekly. Perfect for monitoring subreddits, tracking new posts on keywords or building a continuously updated dataset.

What export formats are supported?

CSV, JSON and direct push to Google Sheets — plus the lobstr.io API for piping data into your own stack. Connect Google Sheets once and every run lands in your spreadsheet automatically.

Ready to get started?

Export your first results for free.

Contact sales