Best Reddit Scrapers 2026 [No-Code + API Edition]
I tested 7 Reddit scrapers on 4 jobs. lobstr.io wins: cheapest full threads at scale ($0.50/1K results), fastest runs, and deep threads. SociaVault 2nd.
By Nathan Eshetu
Writer @ lobstr.io
Updated 27 Sept 2026
29 min read
Contents
lobstr.io is the best Reddit scraper I tested. It's the cheapest at scale ($0.50 per 1,000 results), collected 784 comments 5 levels deep, and led every post-collection test on speed. SociaVault ranks 2nd: cheapest for bulk posts and the only other tool that keeps deleted comments, but it's API-only and slower.
⚡ 30-Second Summary
- I tested seven Reddit scrapers across four jobs, including Reddit-wide search, subreddit search, subreddit collection, and full threads.
- lobstr.io ranks 1st (8.98/10). It had the lowest scale price for full threads, fastest runs, and deep threads, but search misses post body and ads bill as rows.
- SociaVault ranks 2nd (7.60/10). It's cheapest for bulk posts and keeps deleted comments, but it's API-only and threads cost more.
- Bright Data ranks 3rd (6.51/10). It adds useful post context like subreddit size and related posts, but threads stop at two levels and recency is weak.
- Apify ranks 4th (6.00/10). It found the most posts across the most subreddits, but search is slow, threads stop at two levels, and pricing is the highest of the four.
- Outscraper, ScraperAPI, and SerpApi stay unranked because they only handled narrower parts of the benchmark.
Getting Reddit data used to be pretty simple.
You had the official API. Or, for something quick, you could add .json to a Reddit URL and get structured data back.
Yeah... not anymore.
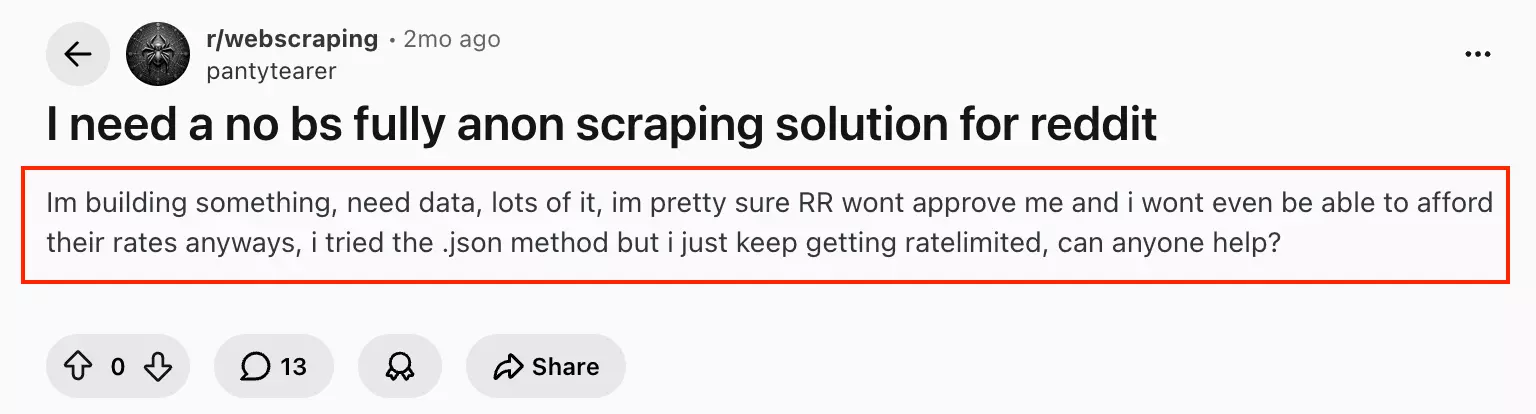
The official API is harder to rely on for scraping, and the old .json route isn't the easy fallback it used to be.
If you want the full breakdown of the API, .json, and other ways to get Reddit data:
👉 How to Scrape Reddit: Posts, Comments & Subreddits (No Login)
So now you're probably looking at Reddit scrapers.
The question is which ones actually work.
I tested seven Reddit scrapers across four jobs: full threads, Reddit-wide search, subreddit search, and subreddit posts.
Four were good enough to rank.
Here's what happened.
| What matters | lobstr.io | SociaVault | Bright Data | Apify |
|---|---|---|---|---|
| User rating | 5.0/5 (33 Capterra) | 5.0/5 (1 G2) | 4.7/5 (68 Capterra) | 4.6/5 (39 Apify Store) |
| Full thread (comments collected) | 784 live | 784 live + 6 deleted | 397 | 200 |
| Full thread (reply depth) | 5 levels | 5 levels | 2 levels | 2 levels |
| Reddit-wide search (posts found) | 221 | 232 | 232 | 325 |
| Full-thread cost (entry, per 1,000) | $2.00 | $1.80 | $1.50 | $3.80 + run fee |
| Full-thread cost (at scale, per 1,000) | $0.50 | $0.75 | $1.30 | $3.40 + run fee |
| Access | No-code + API + MCP | API + MCP | No-code + API + MCP | No-code + API + MCP |
| Exports | CSV, Excel, JSON, JSONL | JSON only | JSON, NDJSON, CSV, XLSX, Parquet | CSV, Excel, JSON, JSONL, XML |
| Built-in scheduling | ✅ | ❌ | ❌ | ✅ |
| Full thread (1,183-comment post, comments/min) | 308 | 93 | 11 | 389* |
| Reddit-wide search ("Elon Musk", posts/min) | 308 | 50 | 22 | 15 |
| r/politics keyword search ("Elon Musk", posts/min) | 369 | 219 | 33 | 11 |
| Latest r/politics posts (up to 1,000 posts, posts/min) | 638 | 431 | 13 | 14 |
| Projected subreddit volume/month | 27.6M results | 18.6M posts | 578K posts | 577K posts |
| Support | Live chat + email | Email + ticket | Apify Issues | |
| Overall score | 8.98/10 | 7.60/10 | 6.51/10 | 6.00/10 |
Note: Apify returned 200 comments where lobstr.io returned 784 and SociaVault 790, so its thread rate isn't comparable to theirs.
Just tell me which one
| If you want... | Go with | Why |
|---|---|---|
| Best overall | lobstr.io | Deepest threads, fastest collection, cheapest at scale |
| Fastest collection | lobstr.io | Led all 3 post tests at 308–638 posts/min |
| Largest subreddit collection | lobstr.io | Returned 943 organic posts, vs 834 for SociaVault and ~50 for the others |
| Cheapest full threads at scale | lobstr.io | $0.50 per 1,000 results, vs $0.75 SociaVault, $1.30 Bright Data, $3.40+ Apify |
| Best thread structure | SociaVault | 5 levels deep, with deleted branches preserved |
| Cheapest bulk posts | SociaVault | As low as $0.10/1,000 posts in testing |
| Best post context | Bright Data | Subreddit size + related posts were consistently populated |
| Broadest Reddit discovery | Apify | Found 325 posts across 175 subreddits |
| Strongest support | lobstr.io | Live chat + email, 5.0/5 Capterra support rating |
⚠️ Disclaimer
Not legal advice. Laws vary by country and change over time. For your situation, check with a qualified lawyer.
Is Reddit scraping legal?
Yes, under the right conditions.
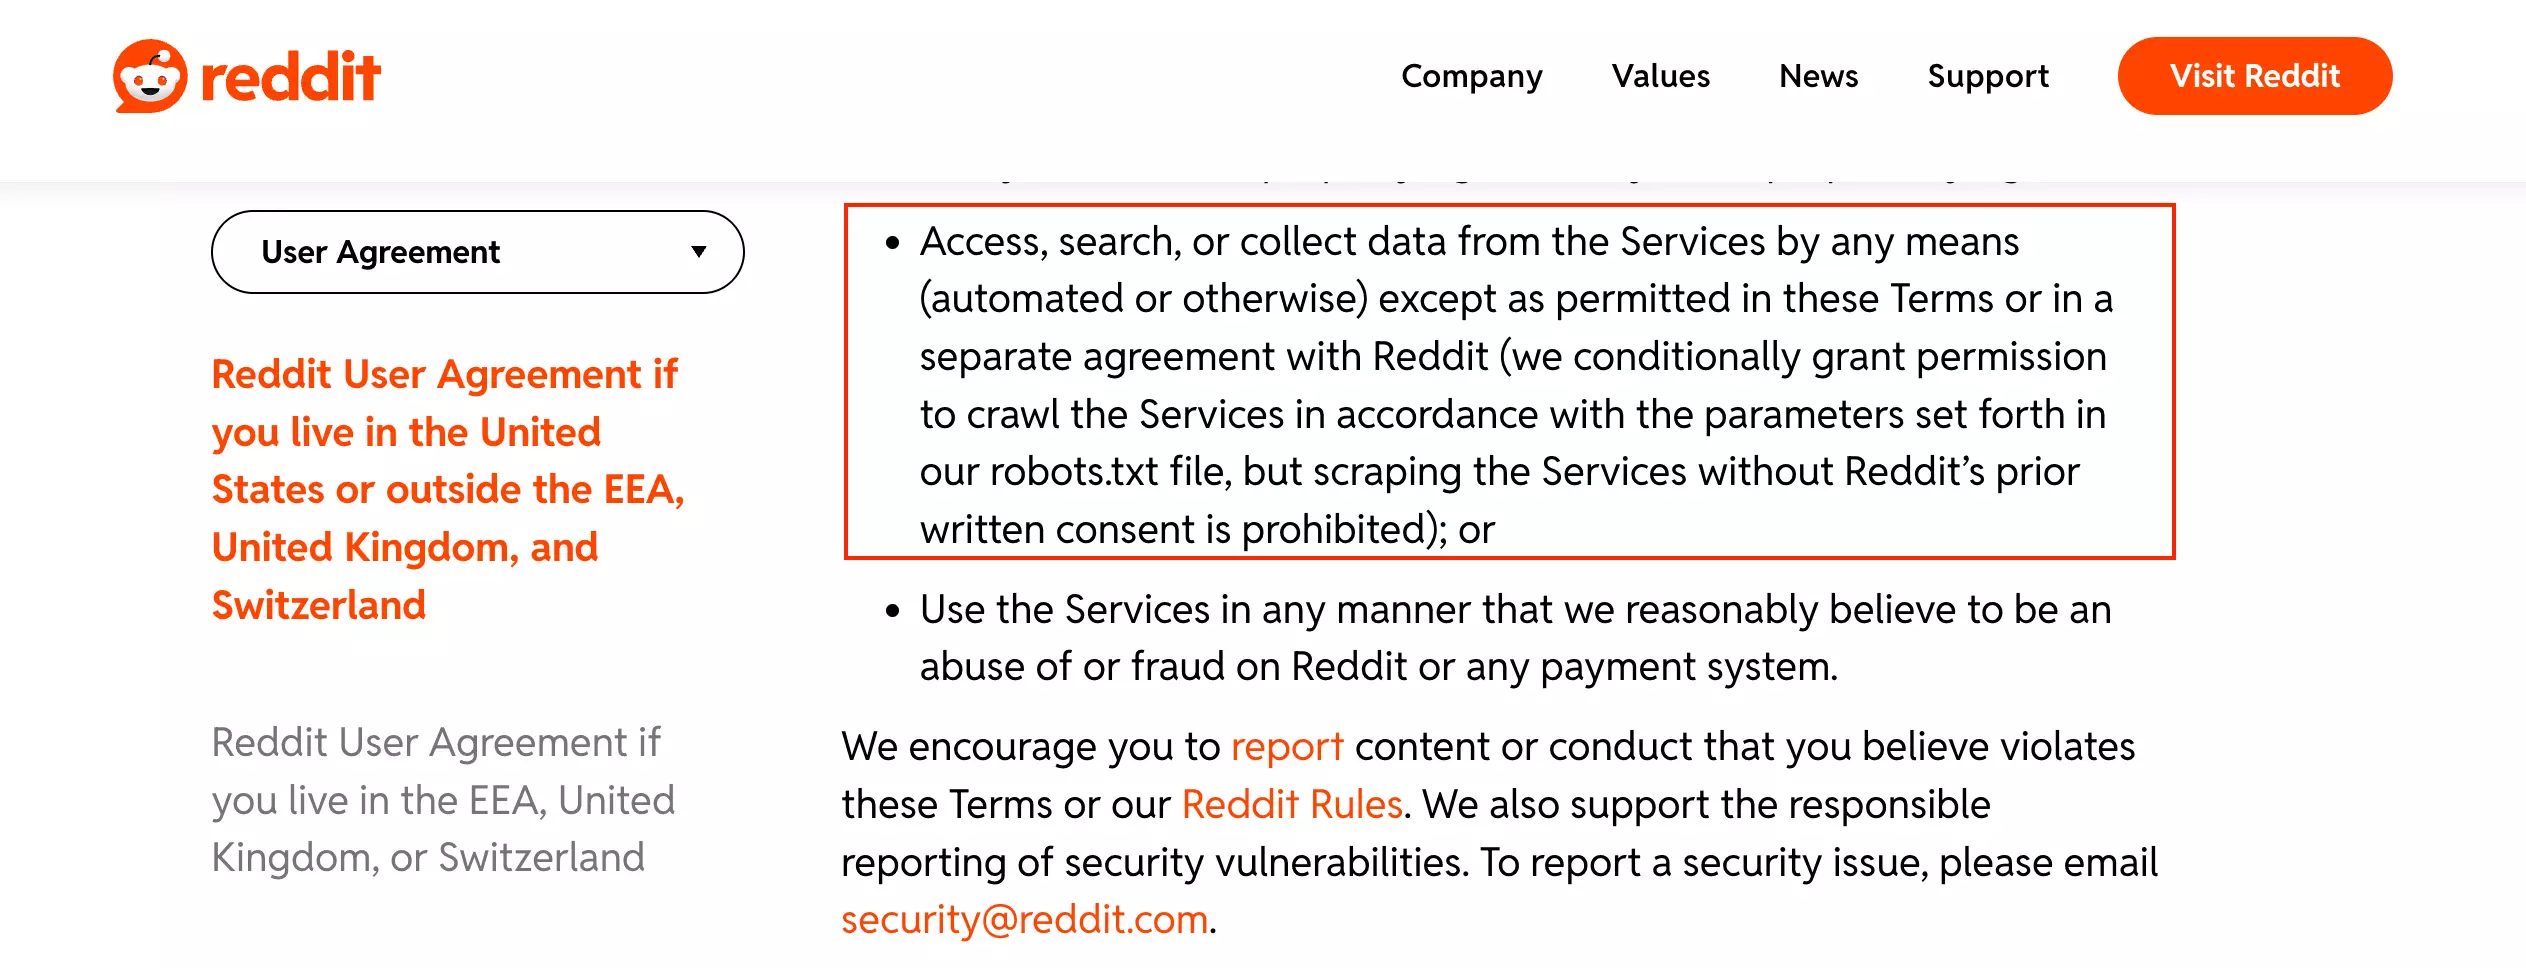
Reddit's User Agreement says you can't scrape the platform without permission.
But Reddit's rules and the law aren't the same thing. In the U.S., the Ninth Circuit has held that scraping publicly accessible data does not necessarily violate the CFAA.
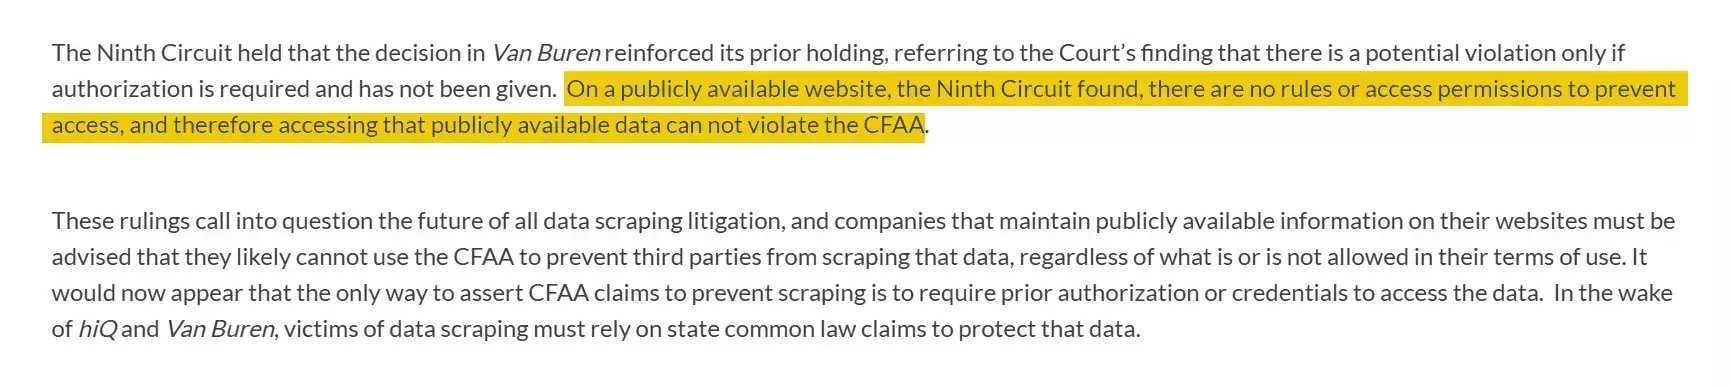
That doesn't make every scraping use case legal.
Republishing copyrighted posts at scale or profiling identifiable users can still create copyright and privacy risks.
How to stay on the right side:
- Collect data internally, for research, analysis, or model training
- Don't republish Reddit content on a public-facing surface
- Don't combine it with PII for profiling without a legal basis
- Respect rate limits and don't hammer the platform
For a deeper breakdown, see the legal series.
How I tested the Reddit scrapers
I tested each scraper across four Reddit workloads:
- Reddit-wide search:
Elon Musk, requesting up to 1,000 results withsort=newwhere supported, comparing relevance, freshness, and ordering. - Scoped search: the same
Elon Musksearch within r/politics, focused on scoped retrieval and newest-first ordering. - Subreddit collection: up to 1,000 new r/politics posts, testing duplicates, errors, and larger-job handling.
- Full conversation: the same r/politics post with 1,183 Reddit-reported comments, comparing comment retrieval, reply structure, and data quality.
This comparison covers posts, search, subreddits, and threads. For Reddit topics:
What I compared
I scored the tools across six criteria:
- Data: retrieval, reply structure, useful fields, search quality, and data-quality issues.
- Cost: published entry and scale pricing, normalized where possible to cost per 1,000 results.
- Usability: setup, controls, output, and workflow options.
- Speed: measured benchmark runtimes, with like-for-like results compared where possible.
- Scalability: projected monthly throughput, parallel concurrency.
- Support: available support channels plus evidence of response or issue resolution.
How I chose the tools
I built the longlist from Google, Reddit, developer discussions, review sites, and AI recommendations.
I then kept tools with a dedicated Reddit workflow capable of handling the benchmark jobs.
I excluded abandoned or poorly maintained products, general-purpose scrapers where a dedicated Reddit tool was available, and search-only tools that couldn't handle full thread collection.
How the scores landed
| Criterion (weight) | lobstr.io | SociaVault | Bright Data | Apify |
|---|---|---|---|---|
| Data (2.2) | 9.0 | 8.8 | 7.5 | 6.5 |
| Cost (2.2) | 8.5 | 9.0 | 7.0 | 4.5 |
| Usability (1.8) | 9.0 | 5.5 | 8.0 | 9.5 |
| Speed (1.8) | 9.5 | 8.0 | 3.5 | 4.0 |
| Scalability (1.0) | 9.0 | 7.5 | 6.0 | 6.0 |
| Support (1.0) | 9.0 | 5.0 | 6.5 | 5.5 |
| Weighted overall /10 | 8.98 | 7.60 | 6.51 | 6.00 |
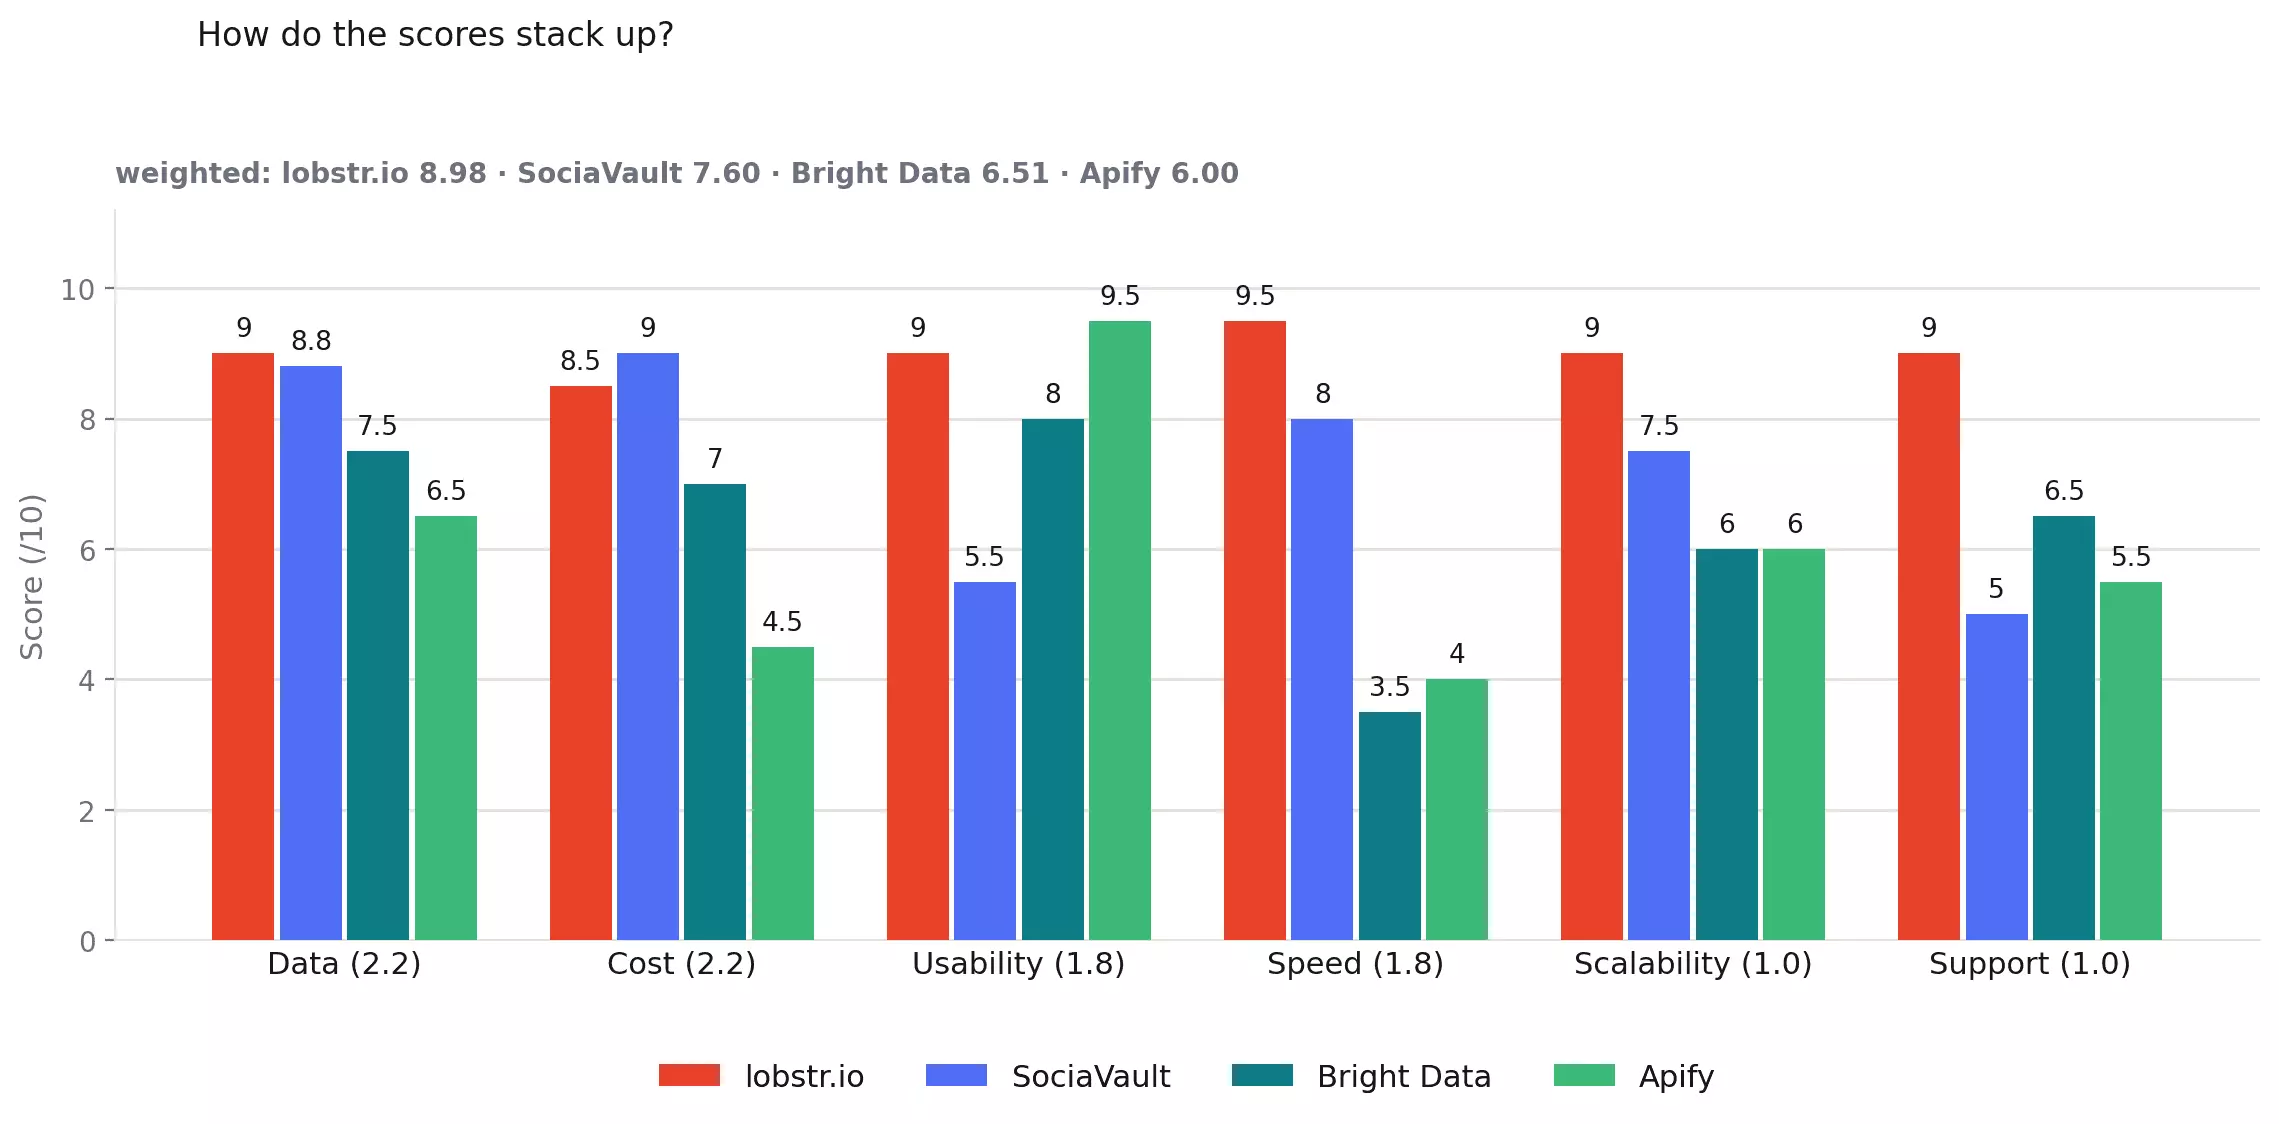
Each criterion is scored from 0 to 10 and weighted by its importance to the buying decision:
Data 2.2 · Cost 2.2 · Usability 1.8 · Speed 1.8 · Scalability 1.0 · Support 1.0
Overall = Σ(criterion score × weight) ÷ 10
The overall score doesn't mean one tool wins every category. SociaVault scored highest on cost, while Apify scored highest on usability.
The best Reddit scrapers
| What matters | lobstr.io | SociaVault | Bright Data | Apify |
|---|---|---|---|---|
| User rating | 5.0/5 (33 Capterra) | 5.0/5 (1 G2) | 4.7/5 (68 Capterra) | 4.6/5 (39 Apify Store) |
| Full thread (comments collected) | 784 live | 784 live + 6 deleted | 397 | 200 |
| Full thread (reply depth) | 5 levels | 5 levels | 2 levels | 2 levels |
| Reddit-wide search (posts found) | 221 | 232 | 232 | 325 |
| Full-thread cost (entry, per 1,000) | $2.00 | $1.80 | $1.50 | $3.80 + run fee |
| Full-thread cost (at scale, per 1,000) | $0.50 | $0.75 | $1.30 | $3.40 + run fee |
| Access | No-code + API + MCP | API + MCP | No-code + API + MCP | No-code + API + MCP |
| Exports | CSV, Excel, JSON, JSONL | JSON only | JSON, NDJSON, CSV, XLSX, Parquet | CSV, Excel, JSON, JSONL, XML |
| Built-in scheduling | ✅ | ❌ | ❌ | ✅ |
| Full thread (1,183-comment post, comments/min) | 308 | 93 | 11 | 389* |
| Reddit-wide search ("Elon Musk", posts/min) | 308 | 50 | 22 | 15 |
| r/politics keyword search ("Elon Musk", posts/min) | 369 | 219 | 33 | 11 |
| Latest r/politics posts (up to 1,000 posts, posts/min) | 638 | 431 | 13 | 14 |
| Projected subreddit volume/month | 27.6M results | 18.6M posts | 578K posts | 577K posts |
| Support | Live chat + email | Email + ticket | Apify Issues | |
| Overall score | 8.98/10 | 7.60/10 | 6.51/10 | 6.00/10 |
Note: Apify returned 200 comments where lobstr.io returned 784 and SociaVault 790, so its thread rate isn't comparable to theirs.
1. lobstr.io — Reddit Scraper
- User rating: 5.0/5 from 33 reviews on Capterra, as of September 19, 2026
- My rating: 8.98/10
- Type: No-code + API + MCP
- Pricing: Starts at $2.00, scales to $0.50 per 1,000 results
- Strongest at: deep Reddit conversations, the lowest full-thread cost at scale, and consistently fast runs.
| Pillar | Score /10 |
|---|---|
| Data | 9.0 |
| Cost | 8.5 |
| Usability | 9.0 |
| Speed | 9.5 |
| Scalability | 9.0 |
| Support | 9.0 |
| Overall | 8.98 |
lobstr.io is a French web scraping platform with 70+ ready-made scrapers. Its Reddit scraper is the only one here you can drive from a no-code app, a REST API, a CLI, and an MCP server.
| Pros | Cons |
|---|---|
| 784 live comments across 5 levels | Missed some deleted comments |
| Cheapest full threads at scale, $0.50/1,000 results | No post body in either search |
| Fastest on all three post-collection tests | Includes ads |
| Collected 943 subreddit posts in one run, the most here |
Data
lobstr.io returned 38 populated post fields and 12 comment fields in the thread test.
| Data | What you get |
|---|---|
| Post | ID, URL, shortlink, title, body, post type |
| Author | Name, ID, premium flag |
| Comments | ID, body, score, author, timestamp |
| Reply structure | Parent ID, depth, post ID |
| Engagement | Score, comment count, upvote ratio, awards, crossposts |
| Subreddit | Name, ID, subscriber count, flair |
| Media | Media URL, thumbnail, video and gallery flags |
| Status | Promoted, locked, archived, stickied, NSFW, spoiler, edited |
| Time | Created at |
| Derived | Score/hour, age, comment-to-score ratio, high-engagement flag |
Full thread
On the 1,183-comment thread it returned 784 live comments through five reply levels, with a parent ID on every one. You can see who replied to whom, so a long argument stays readable instead of arriving as a flat list.
Honestly, it isn't complete. Five deleted comments that had replies were dropped, leaving 7 replies pointing at a parent that isn't in the file.
Reddit-wide search
Every one of the 221 posts came from the last 24 hours, the newest 6 minutes old. There's no older tail to filter out, which is what you want for monitoring.
The gap is body text. No post body came back on any of the 221. You get titles and metrics, not what the post actually said.
Keyword search within r/politics
252 posts, 100% in newest-first order, zero duplicates. Reliable ordering means you can stop at the first post you've already seen instead of re-reading the set.
Latest posts from r/politics
943 organic posts in one run, alongside 56 promoted posts and a metadata row. Ads are labelled IS PROMOTED so they filter out in one step.
Overall, lobstr.io is strongest on deep thread collection and recent, correctly ordered search. Its main data gap is missing post body text in search results.
Cost
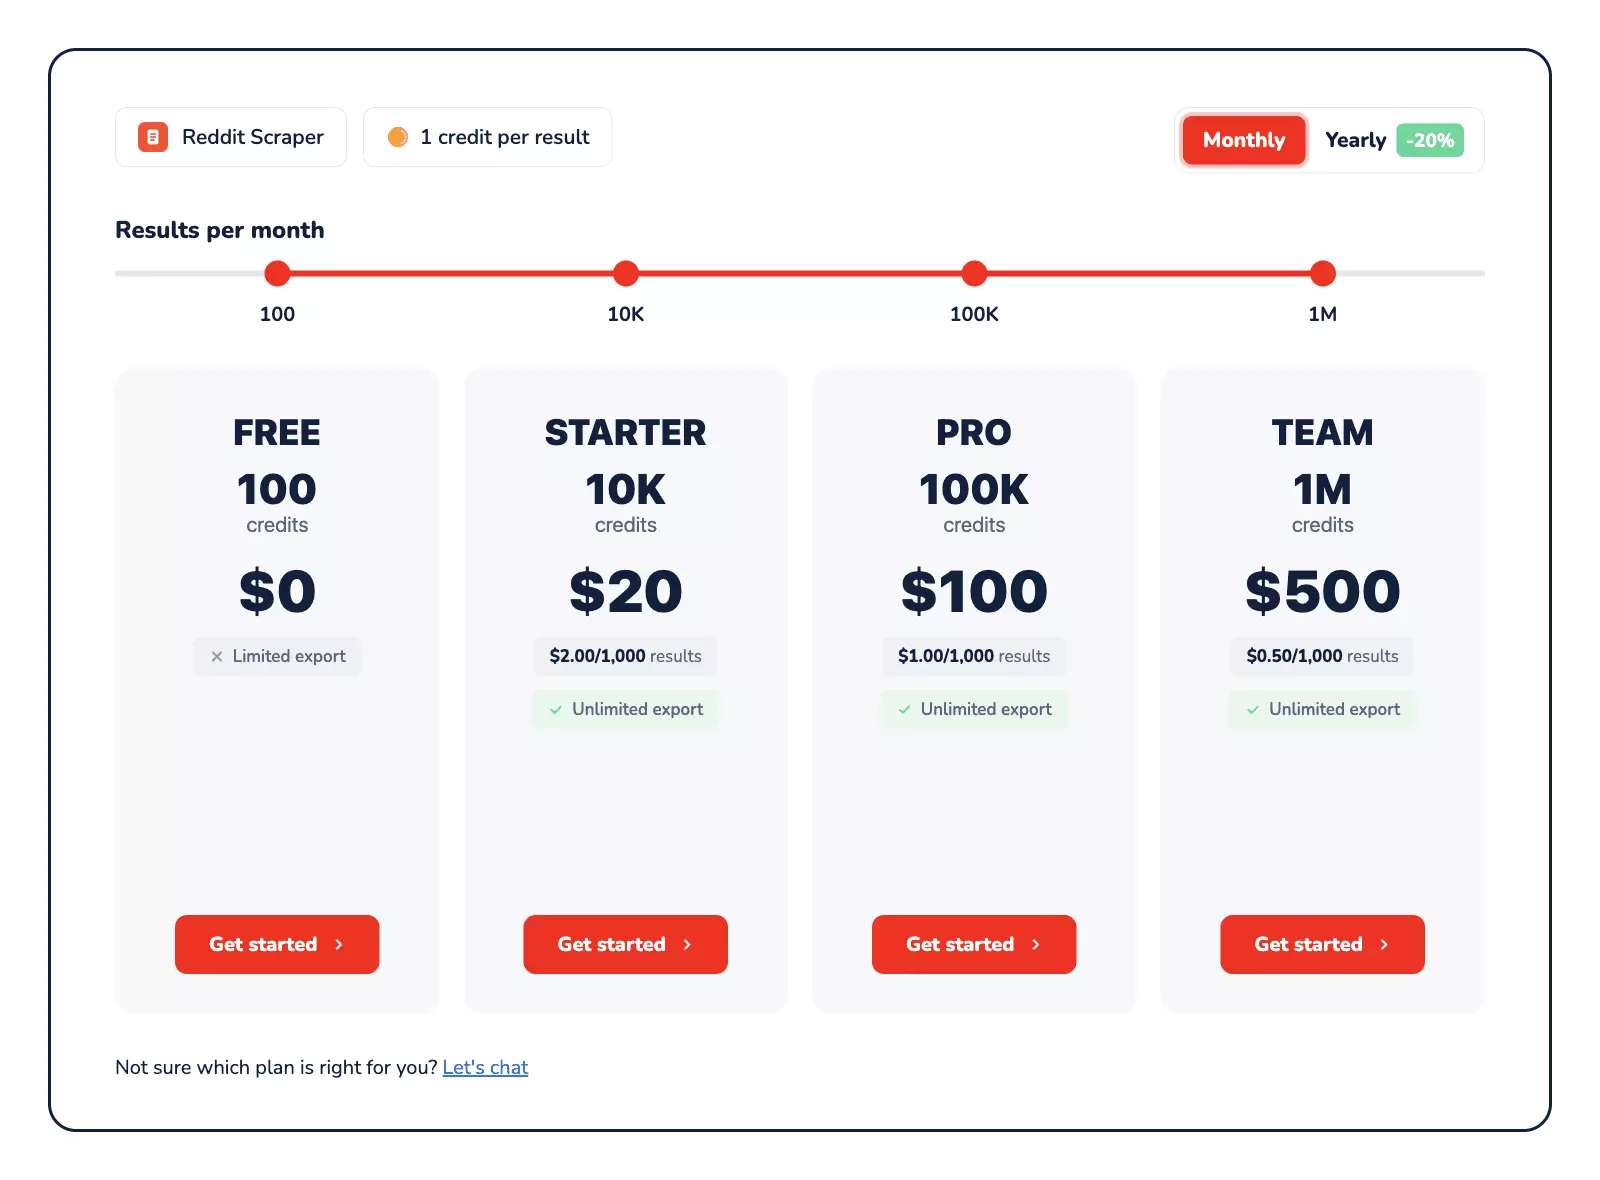
lobstr.io bills 1 credit per returned result, and a result is one row: one post, or one comment. Posts and comments cost exactly the same, so the price is just your credit rate:
- Free: 100 results/month
- Starting: $2.00 per 1,000 results
- At scale: $0.50 per 1,000 results
Usability
The interface is simple. It accepts post, subreddit, and search URLs individually or in bulk.
If you need the whole thing from start to finish, here's the full guide:
👉 How to Scrape Reddit: Posts, Comments & Subreddits (No Login)
Controls include sorting, time range, content filters, result limits, comment depth, and concurrency Slots.
Results export as CSV, Excel, JSON, or JSONL. Delivery supports Google Sheets, Amazon S3, SFTP, email, and webhooks.
Runs can also be scheduled with completion alerts.
It also supports integrations with tools like Make and n8n.
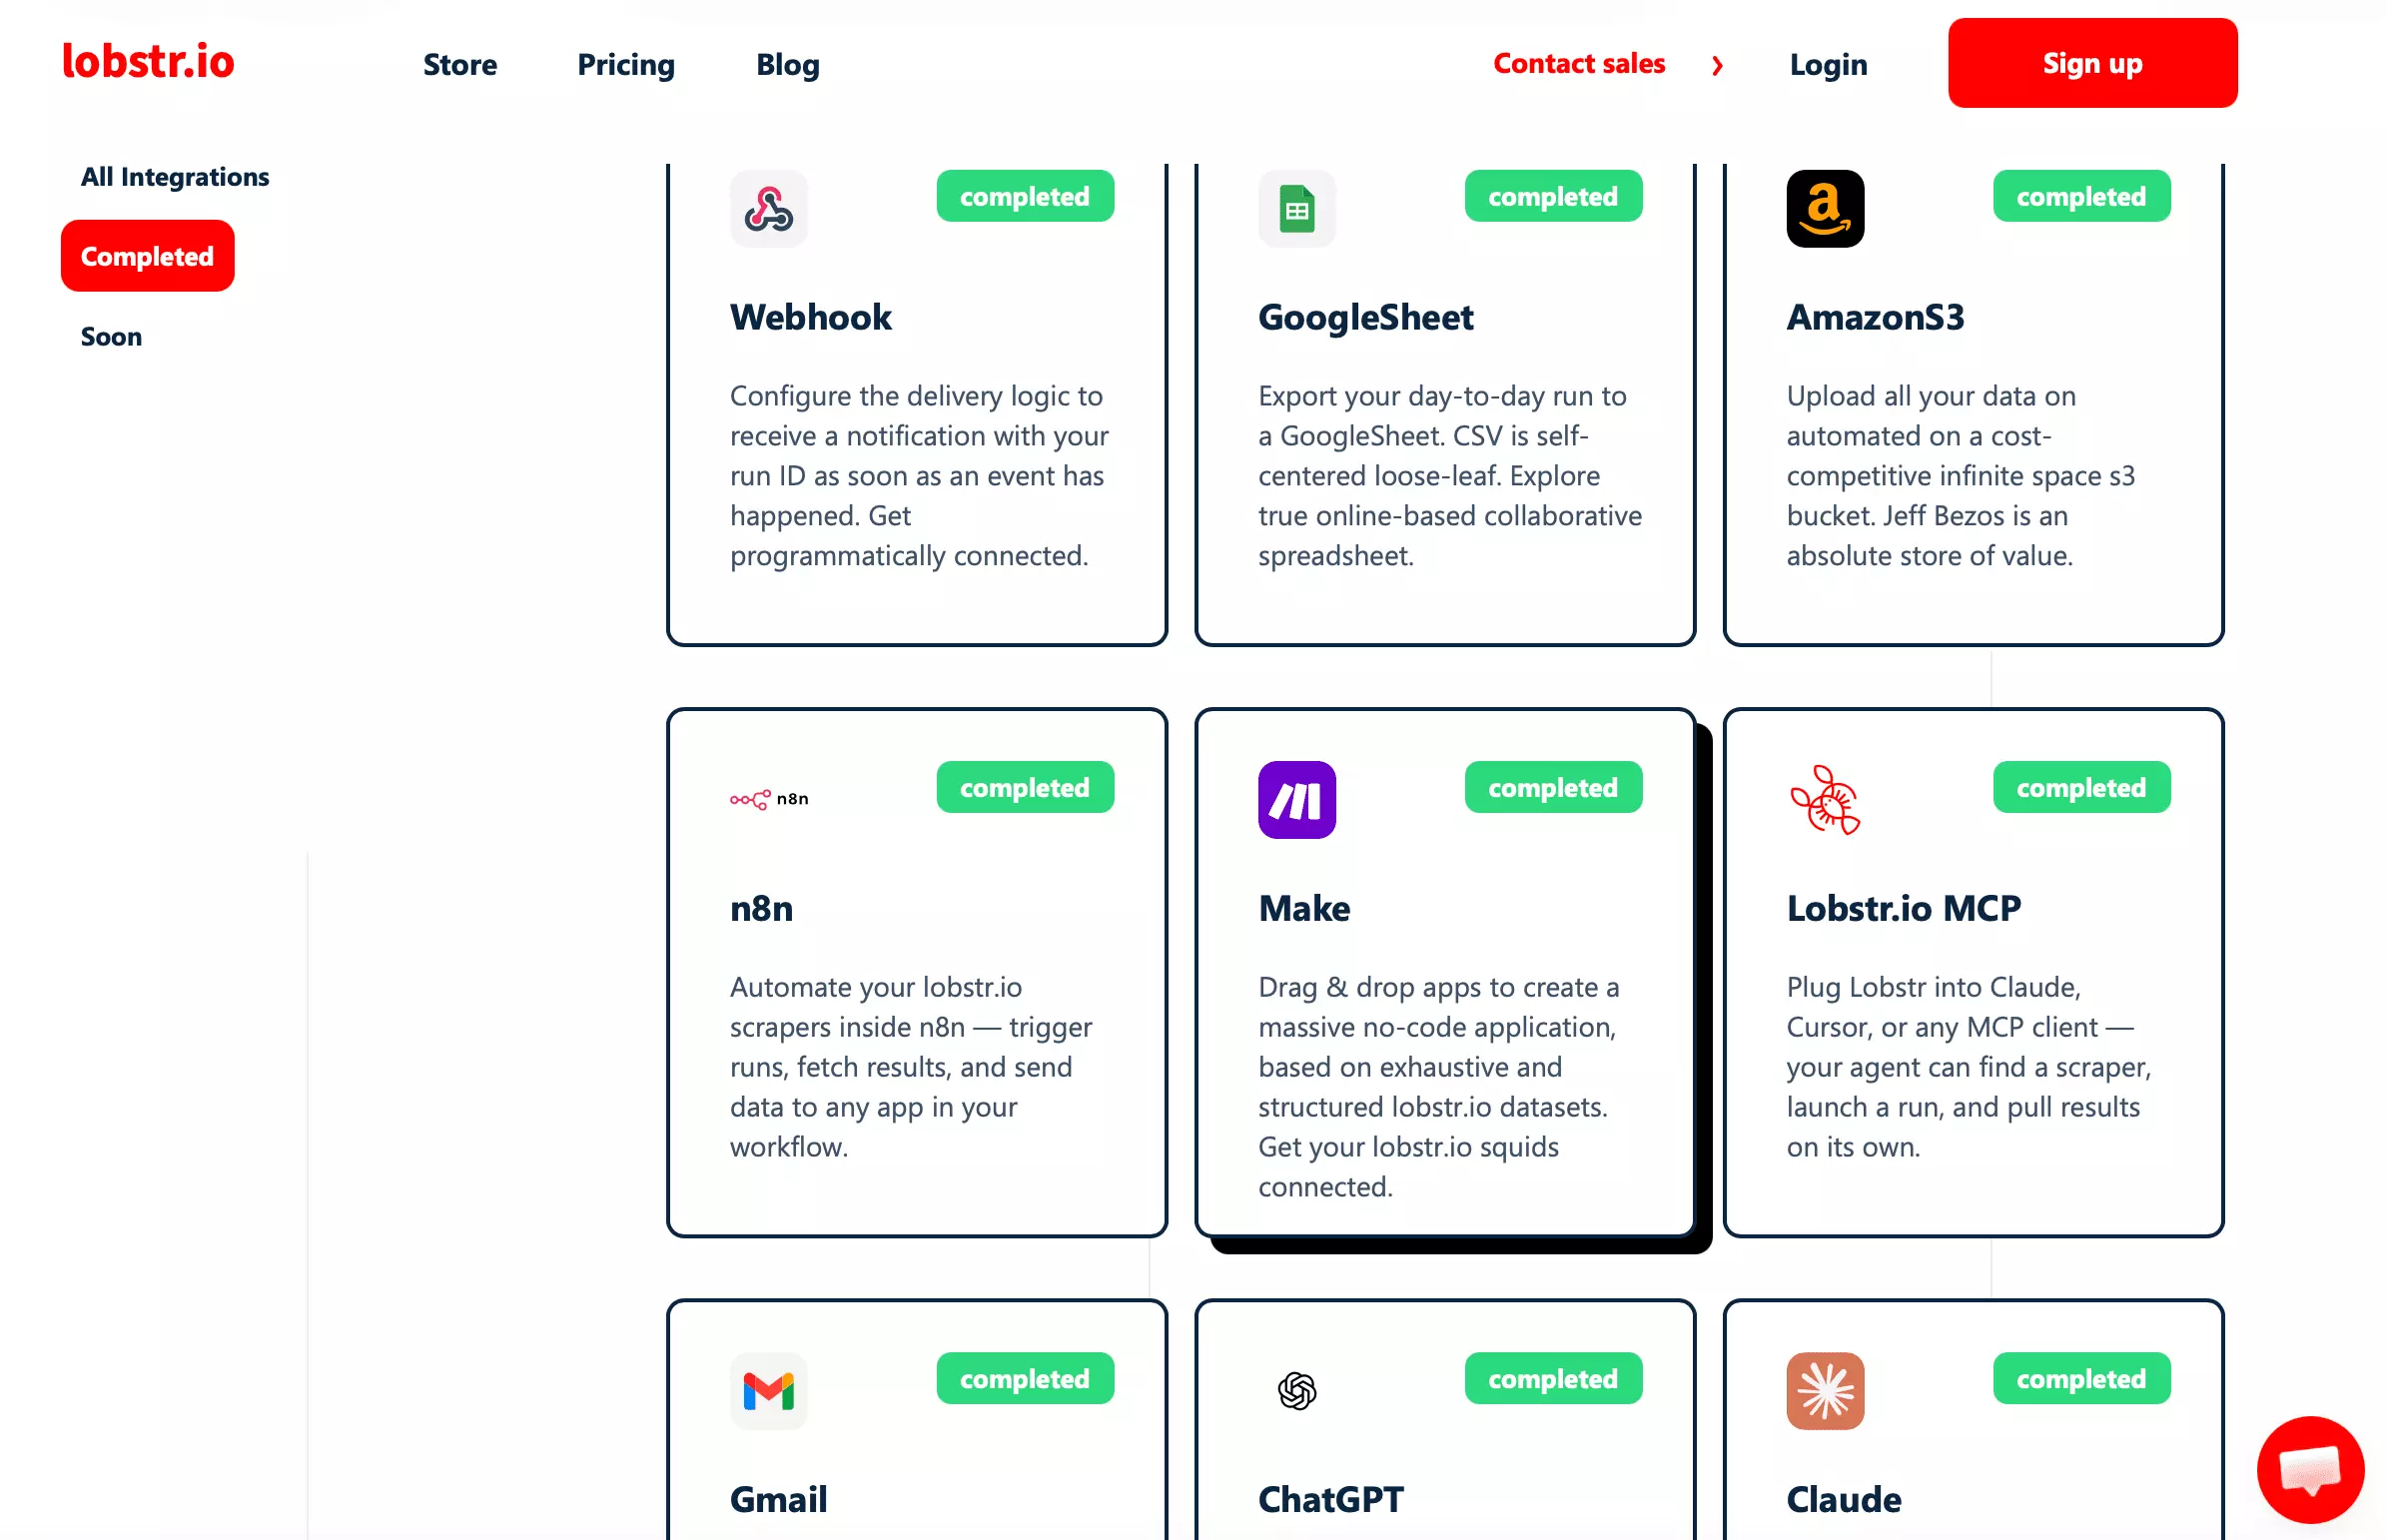
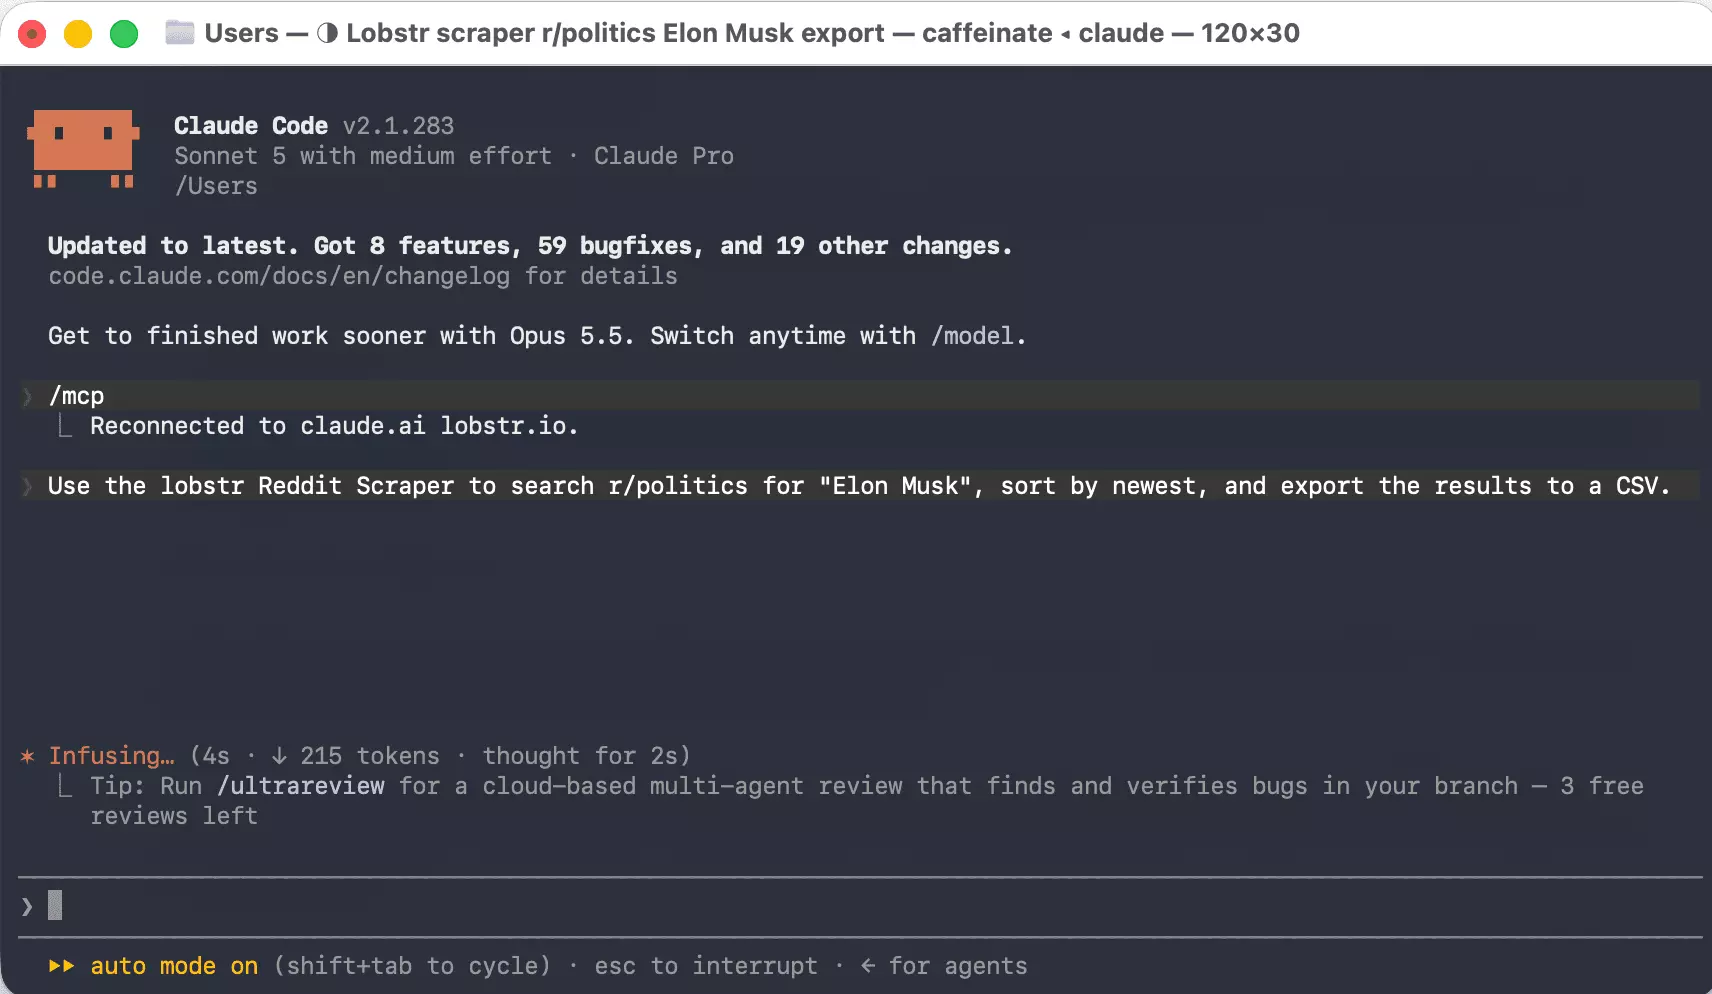
lobstr.io ships an MCP server, so you can run the Reddit scraper straight from an AI client. Ask Claude or ChatGPT to pull a thread or a subreddit, and it launches the scraper and hands the data back.
Add it to Claude in one line:
claude mcp add --transport http lobstr https://mcp.lobstr.io/mcp
Prefer the terminal? There's a CLI too:
pip install lobstrio
lobstr go reddit-scraper "<your Reddit URL>" -o reddit.csv
And a well-documented REST API for building it into your own stack.
So you can start in the dashboard and move to an AI tool, the CLI, or the API later without switching platforms.
Speed
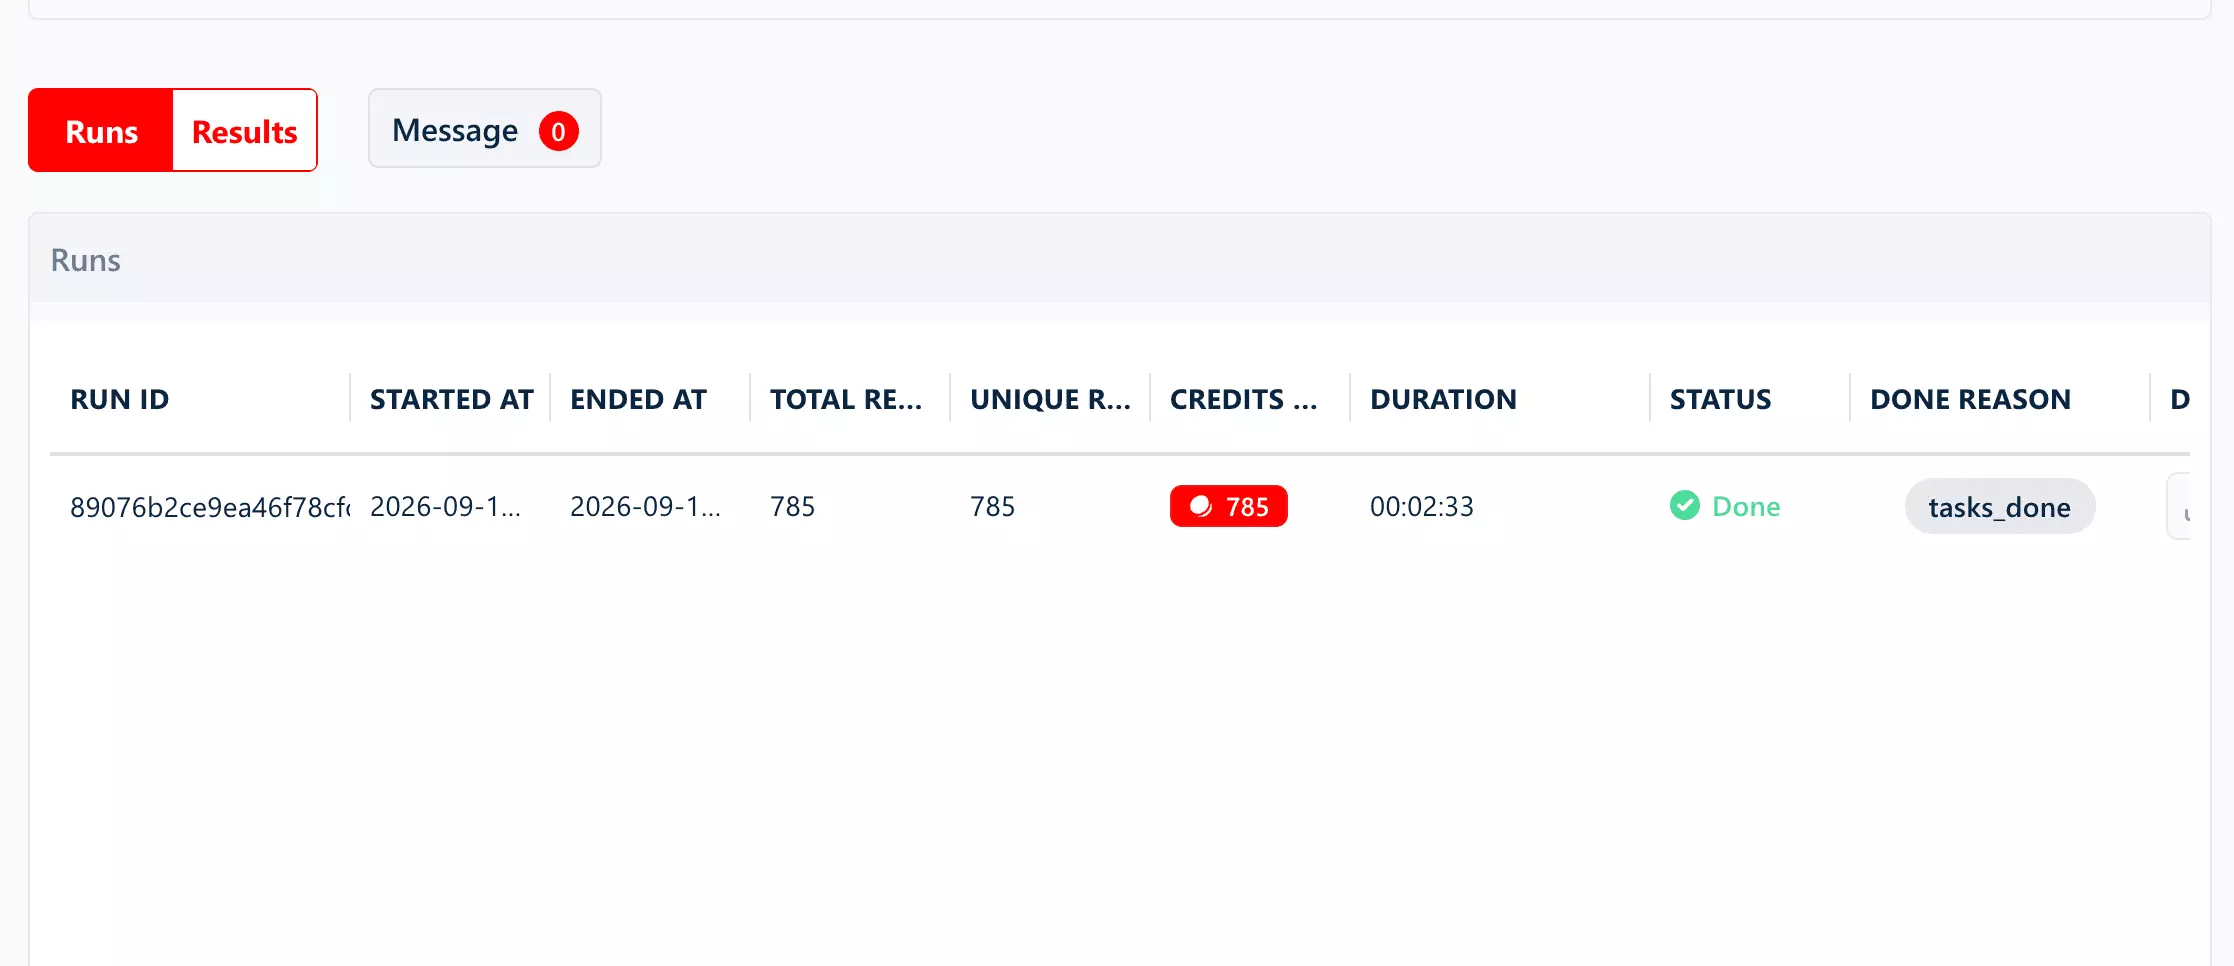
lobstr.io returned 785 rows from the full-thread test in 2:33, or 308 rows/min.
It was faster on the other three workloads:
- Reddit-wide search: 221 posts in 0:43, or 308 posts/min
- r/politics keyword search: 252 posts in 0:41, or 369 posts/min
- Latest r/politics posts: 1,000 rows in 1:34, or 638 rows/min
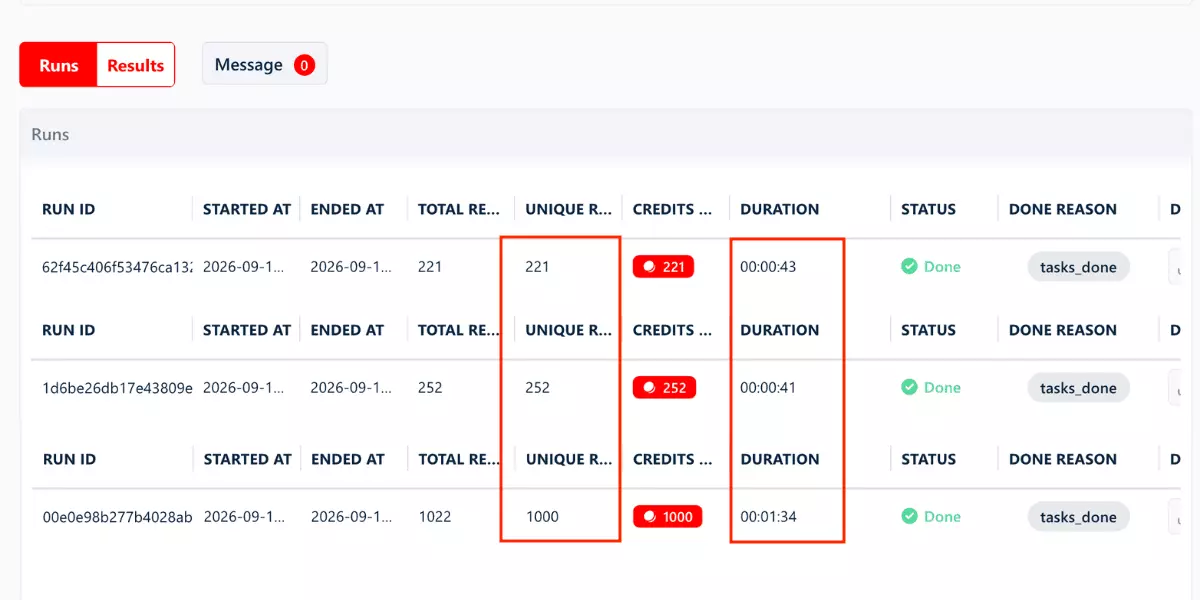
Across all four tests, lobstr.io processed 308–638 rows/min, without a major slowdown on the larger collection job.
Scalability
lobstr.io scales through concurrency Slots. You can add up to 20 Slots per scraper to run jobs in parallel, which raises real throughput.
At a single Slot, its measured rate projects to about 27.6M results a month. That's a projection at one Slot, not a tested monthly volume.
Customer support
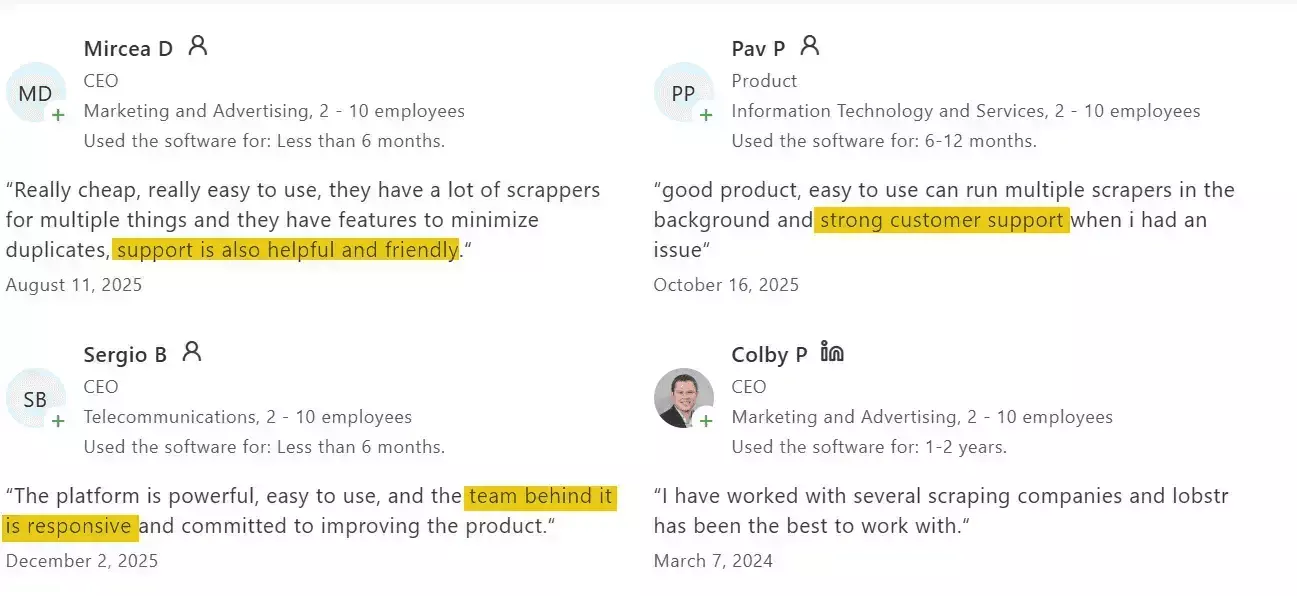
lobstr.io offers live chat and email support. Capterra rates its Customer Service 5.0/5 from 33 reviews.
Its published incident history showed 100% of recent incidents resolved, with a 295-minute median resolution time.
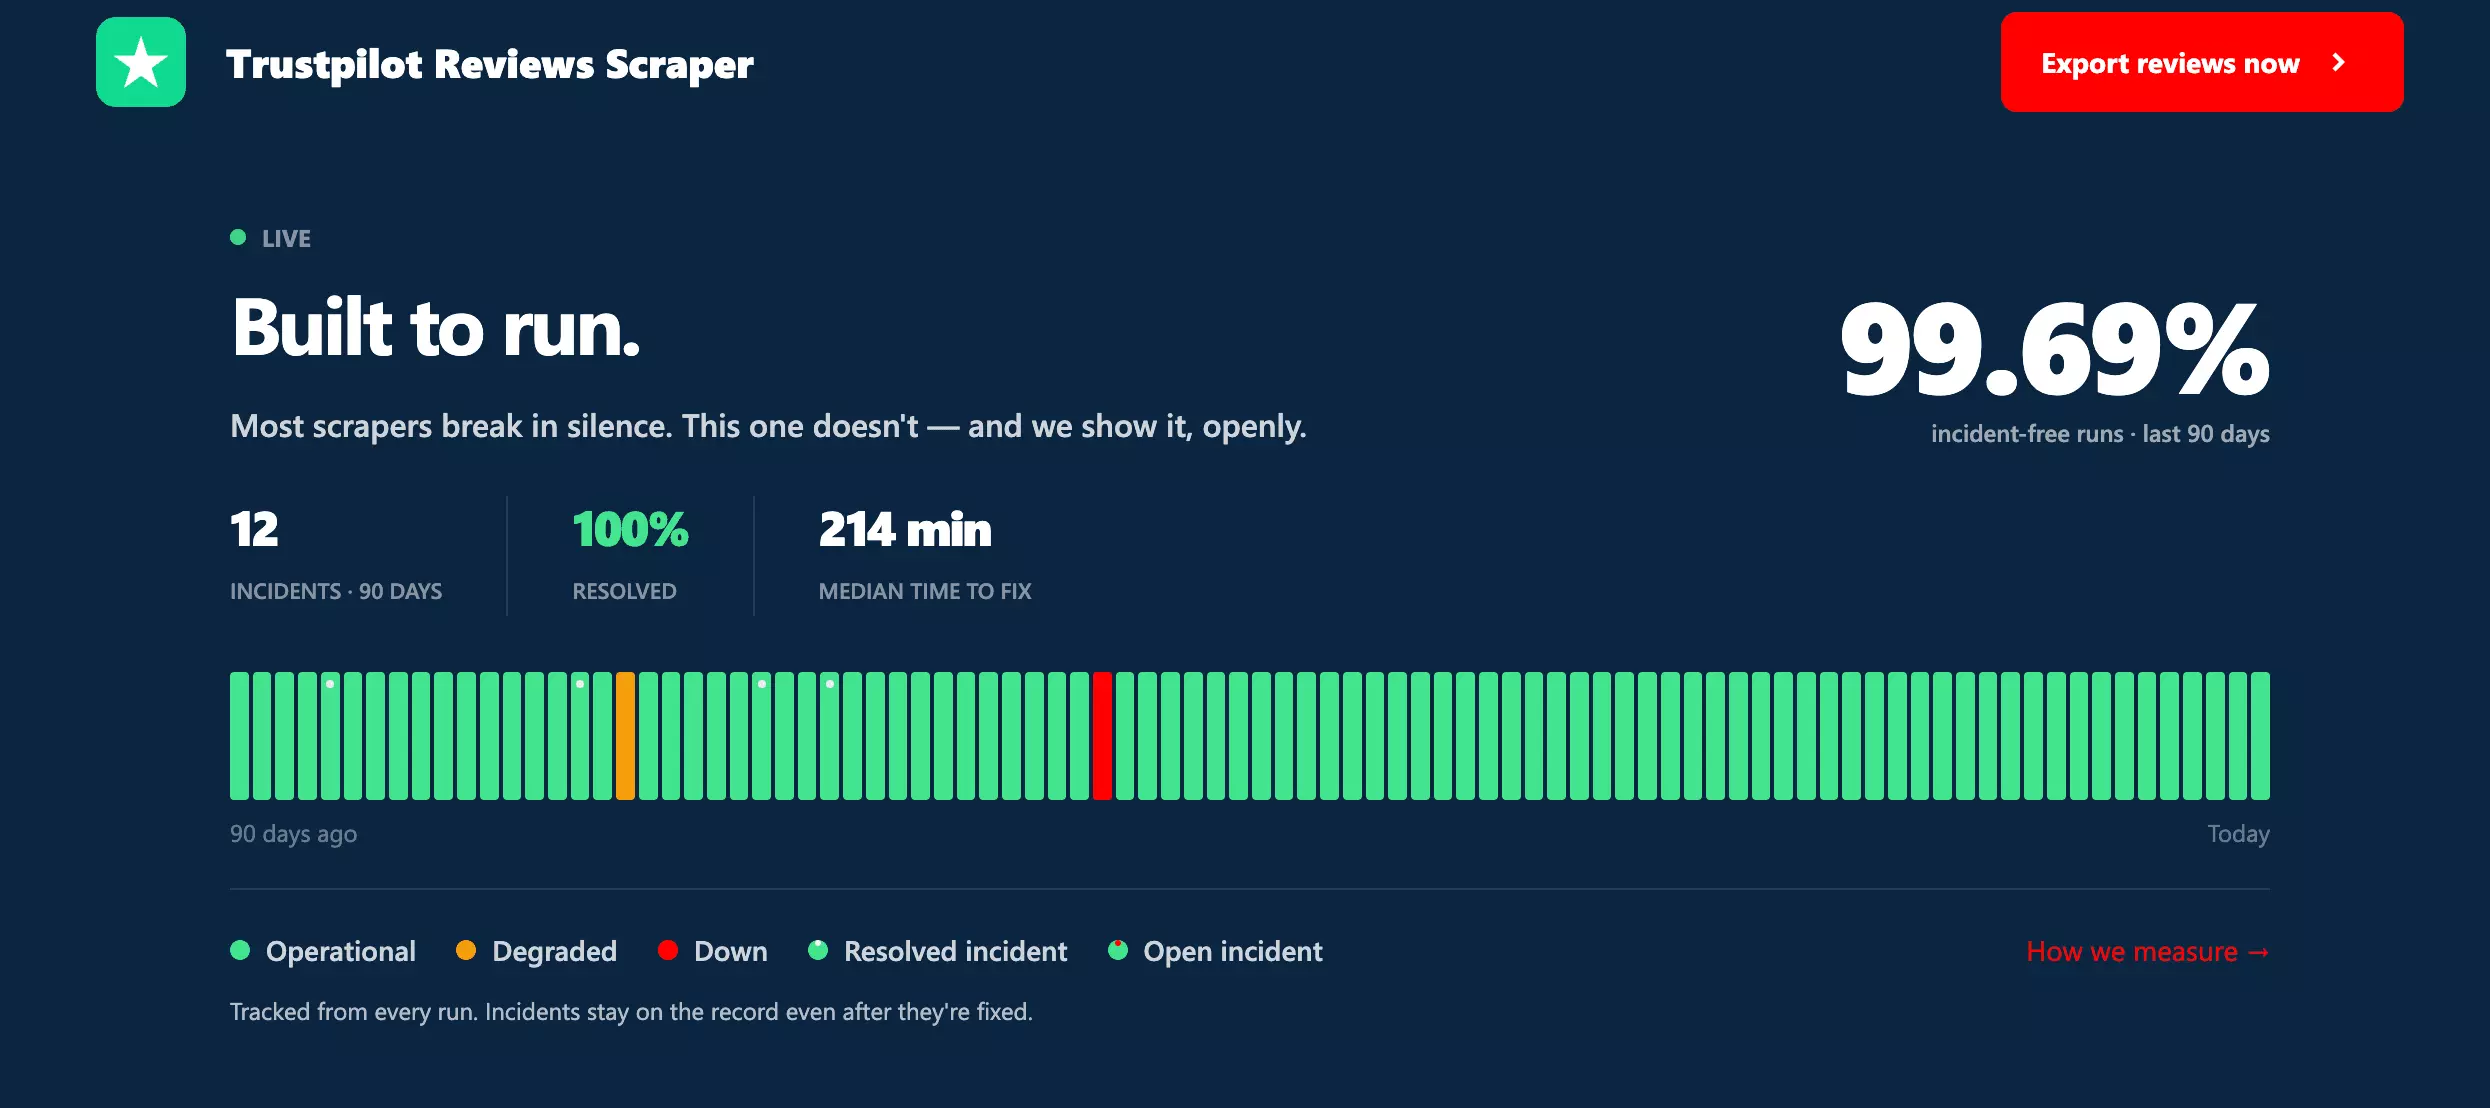
That's resolution time, not first-response time.
This was the strongest support evidence among the tools tested.
Best for: scraping deep Reddit threads and lots of posts quickly, especially if you don't want to write code. Just know that search results don't include the post body.
2. SociaVault
- User rating: 5.0/5 from 1 review on G2, as of September 10, 2026
- My rating: 7.60/10
- Type: API + MCP
- Pricing: Starts at $0.23–$1.80, scales to $0.10–$0.75 per 1,000 results (posts cheapest, full threads priciest)
- Strongest at: preserving complete Reddit conversations and low-cost bulk post collection.
| Pillar | Score /10 |
|---|---|
| Data | 8.8 |
| Cost | 9.0 |
| Usability | 5.5 |
| Speed | 8.0 |
| Scalability | 7.5 |
| Support | 5.0 |
| Overall | 7.60 |
SociaVault is a dedicated social media data API that returns structured Reddit data in real time via simple REST endpoints.
| Pros | Cons |
|---|---|
| 784 live comments across 5 levels, with deleted branches preserved | No no-code interface, so you need the API or MCP |
| Very cheap for bulk posts, down to $0.10/1,000 in testing | JSON only, with no built-in scheduling or delivery |
| 100% newest-first in r/politics keyword search | Reddit-wide search returned duplicates and inconsistent body text |
| Collected 834 clean subreddit posts in 1:56 |
Data
SociaVault returned 22 populated post fields and 16 comment fields in the thread test.
| Data | What you get |
|---|---|
| Post | ID, URL, permalink, title, body |
| Author | Name, author ID |
| Comments | ID, body, HTML body, author, score, vote fields, collapsed flag |
| Reply structure | Parent ID, nested replies |
| Engagement | Score, comment count, upvote ratio, awards |
| Subreddit | Name, ID, flair |
| Status | Archived, locked, NSFW, spoiler, video |
| Time | Timestamp |
Full thread
On the 1,183-comment thread, SociaVault returned 784 live comments plus 6 deleted comments across five reply levels. Every reply still connected to its parent, so you can follow the conversation even when someone deleted a comment.
Reddit-wide search
SociaVault returned 232 recent posts, 94% from the last day, and it brought back the post body too.
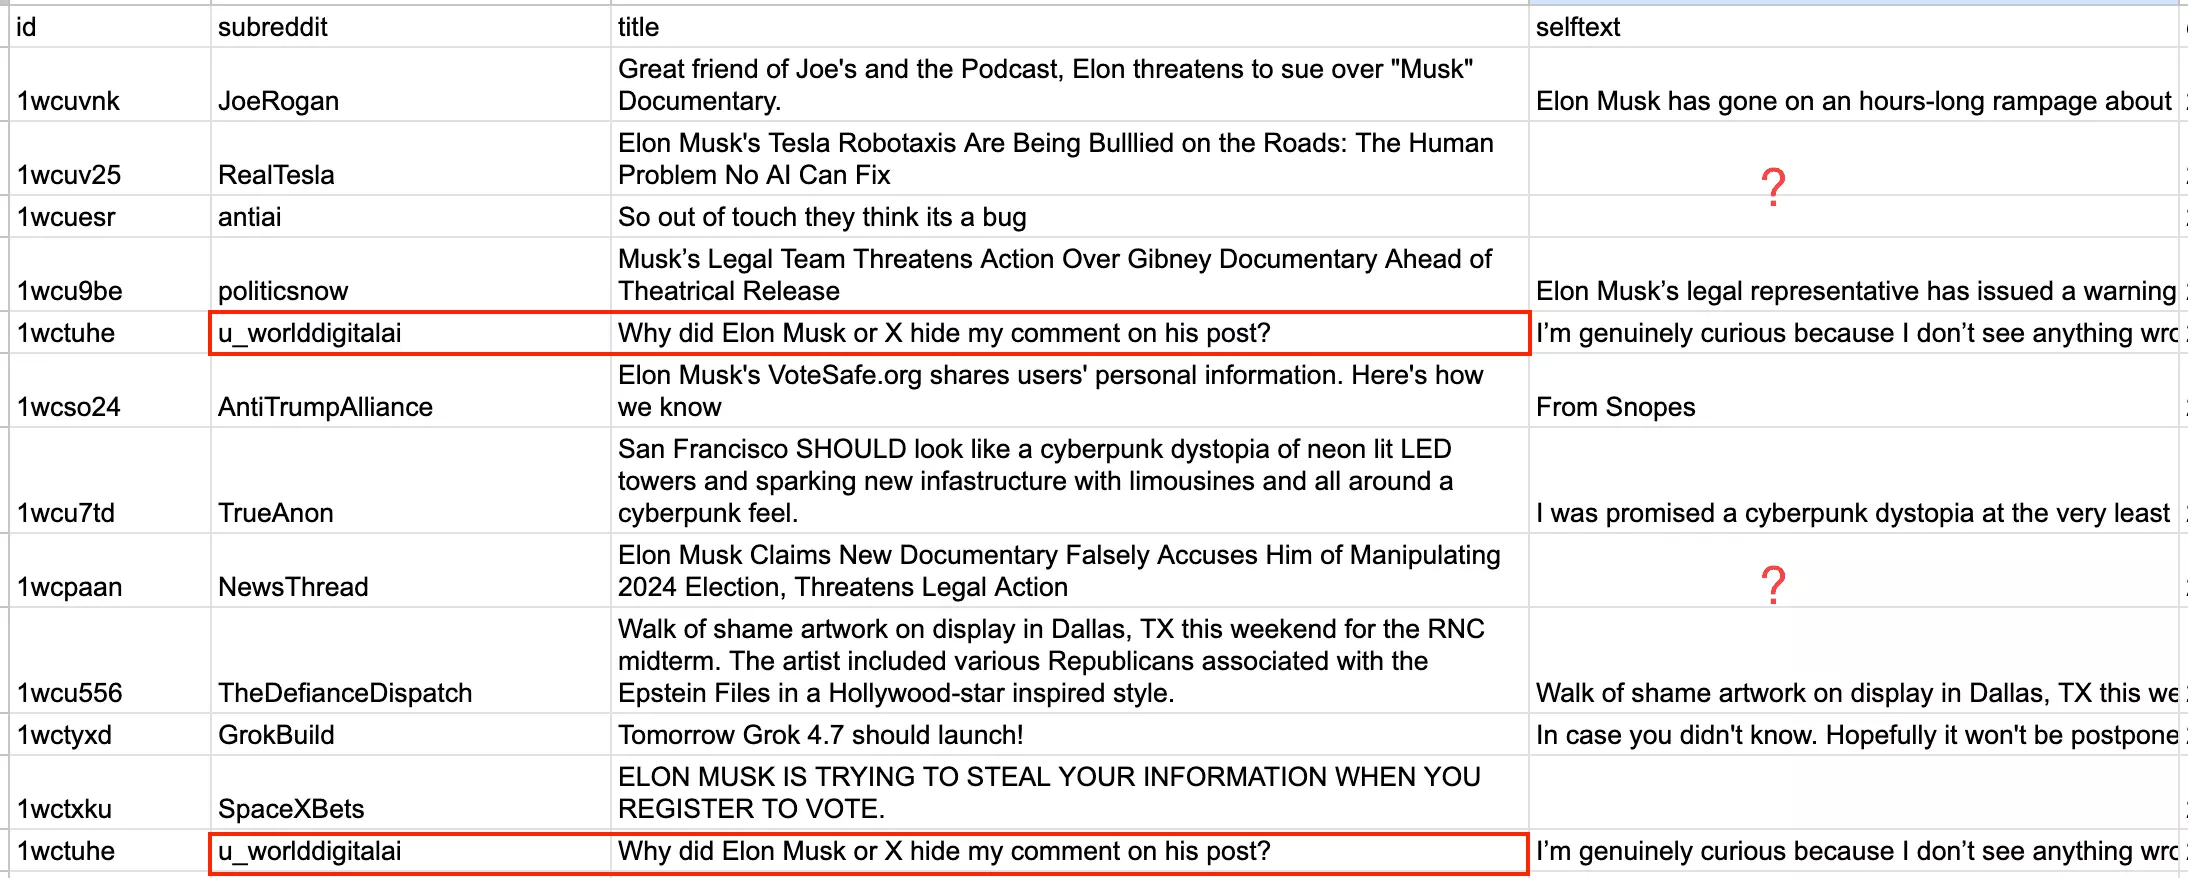
The trade-off is cleanup: in my test, more than half (129 posts) arrived with no body, and 17 rows were duplicates.
Keyword search within r/politics
SociaVault returned 252 posts in 100% newest-first order. That's useful if you're tracking new posts and want to work through them in order.
The main gap was author data. 16 posts had no author, so searches based on who posted something won't always be complete.
Latest posts from r/politics
SociaVault returned 834 posts with no duplicates. The results were clean, but it stopped at 834 even though I asked for 1,000, so you may not always get as many posts as you request.
Overall, SociaVault is strongest at keeping long Reddit conversations intact and returning clean, correctly ordered search results. The main drawbacks are duplicates in Reddit-wide search and not always returning as many subreddit posts as you ask for.
Cost
SociaVault uses a one-time credit model, with no monthly subscription. Credits don't expire.
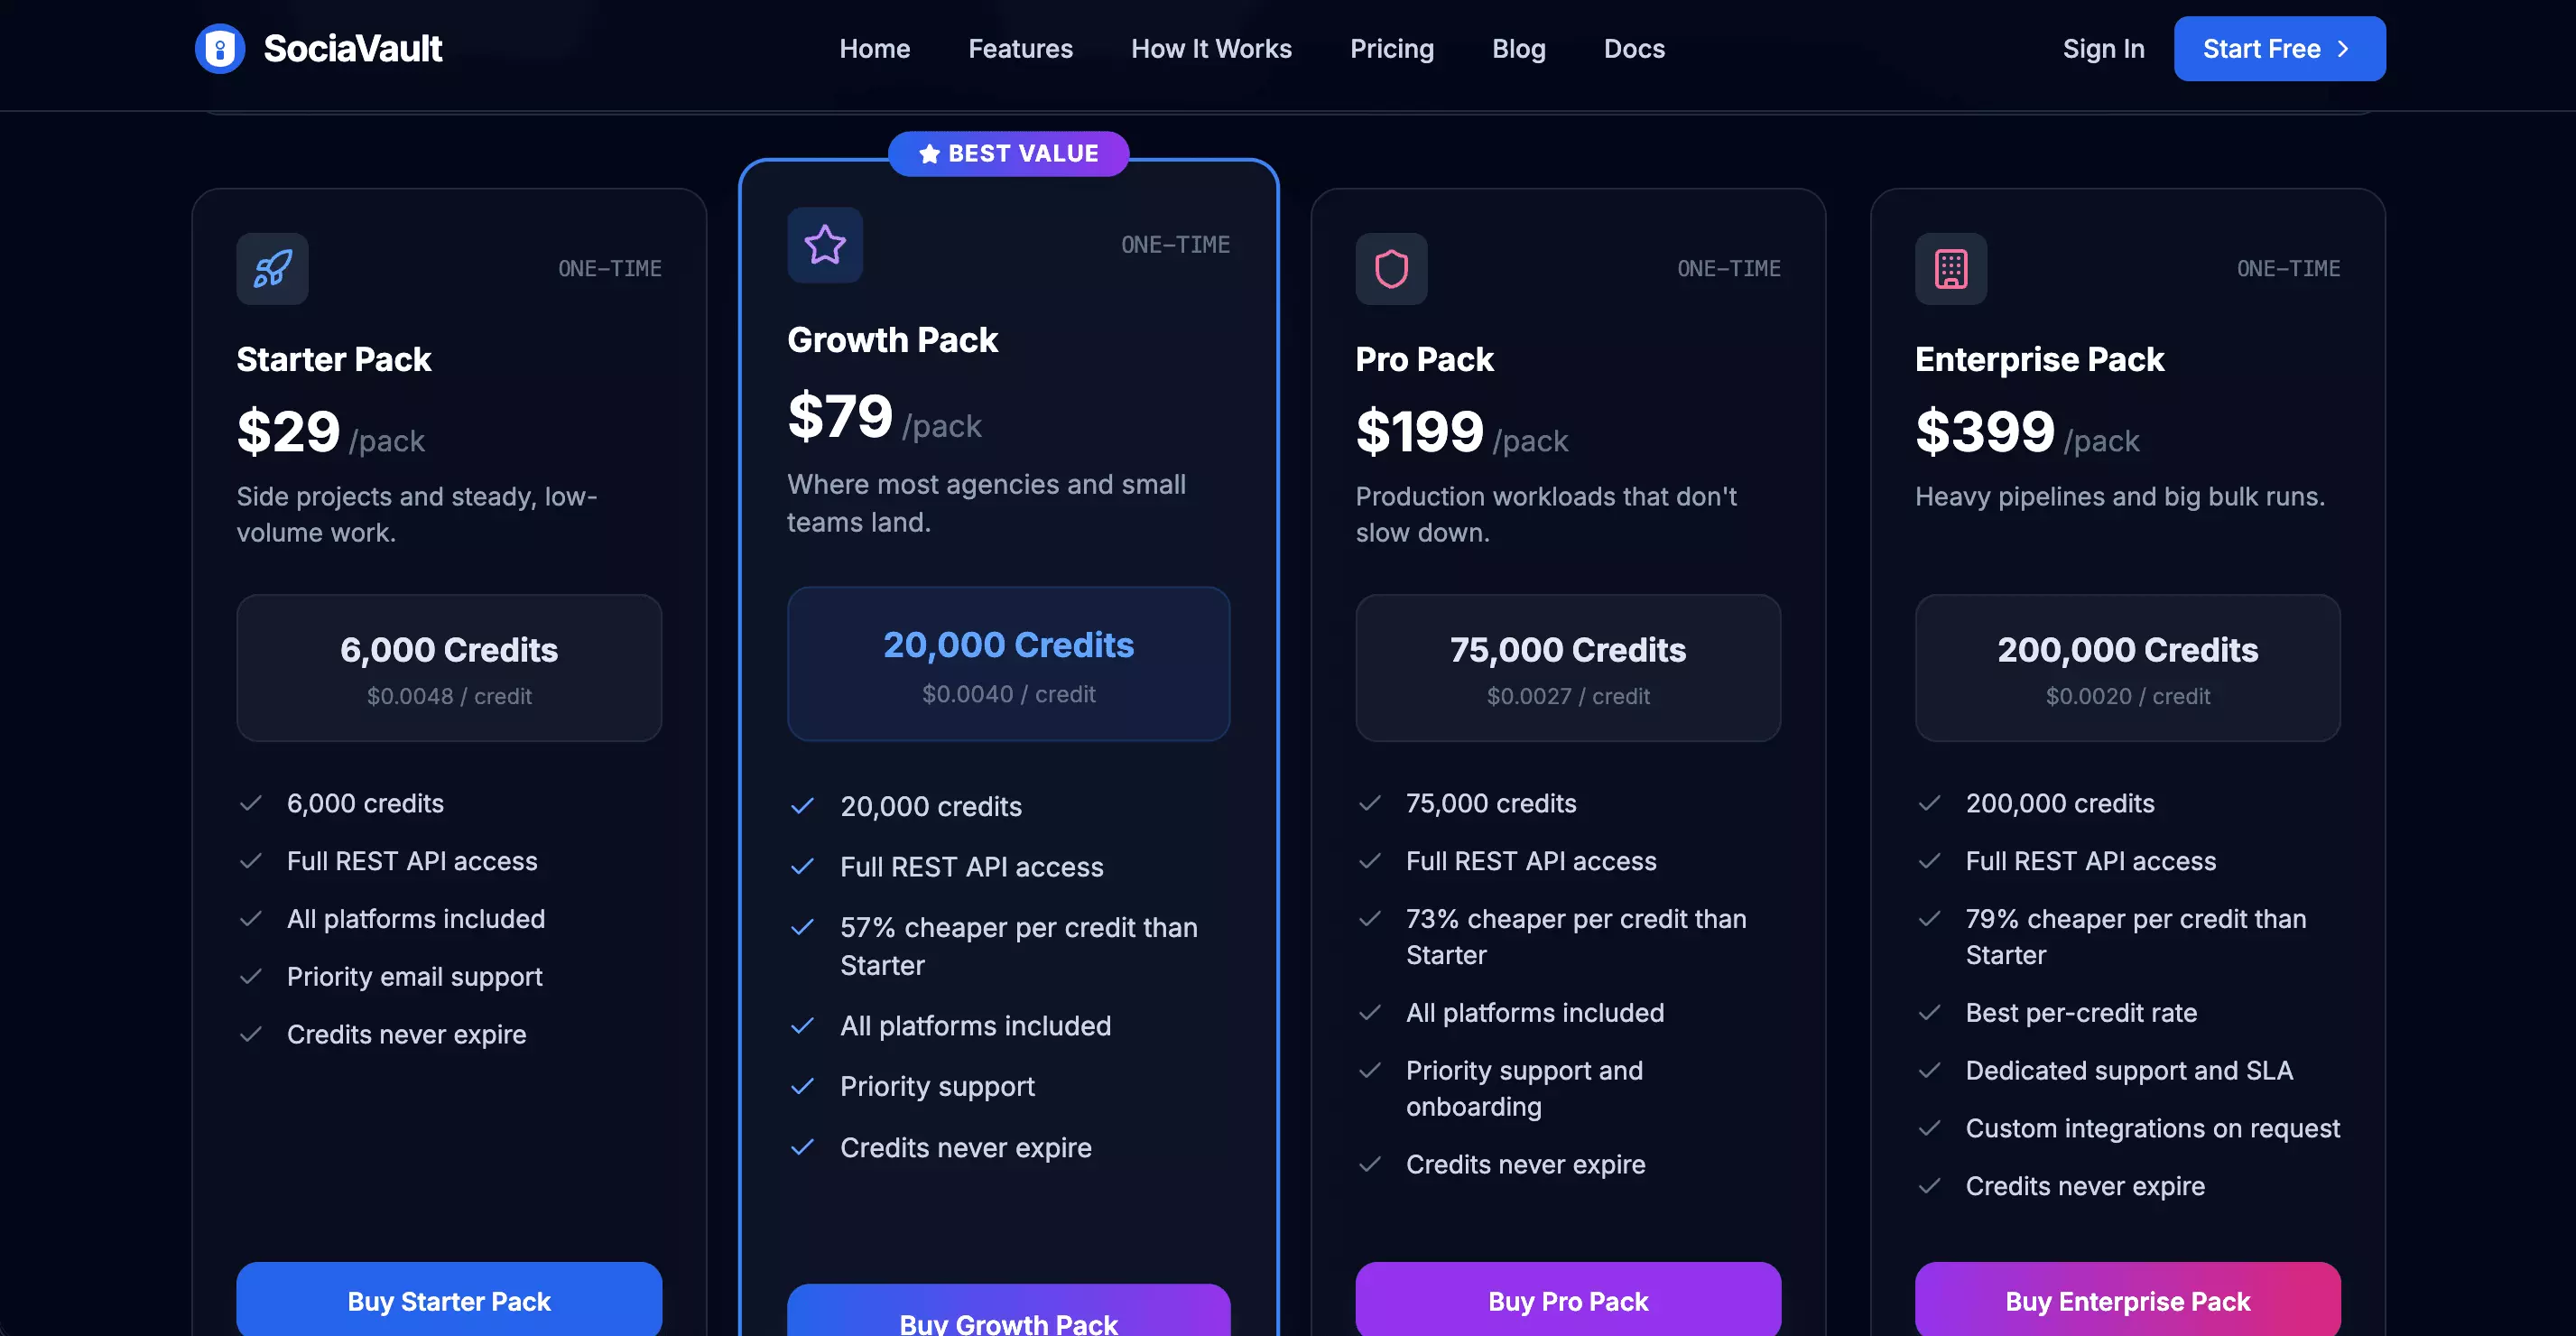
- Starts at: $29 / 6,000 credits ($0.0048/credit)
- Scales at: $399 / 200,000 credits ($0.0020/credit)
SociaVault charges 1 credit per request, not per post or comment returned.
That means the real cost depends on how many posts or comments you get back from each request.
In my tests:
| Test | Requests | Records returned | Starting / 1,000 | At scale / 1,000 |
|---|---|---|---|---|
| Full thread | 297 | 790 | $1.80 | $0.75 |
| Reddit-wide search | 36 | 232 | $0.74 | $0.31 |
| Keyword search within r/politics | 36 | 252 | $0.69 | $0.29 |
| Latest posts from r/politics | 40 | 834 | $0.23 | $0.10 |
SociaVault was cheapest for collecting subreddit posts, at $0.10 per 1,000 posts at scale in my test. Full threads cost more, at $0.75 per 1,000 comments.
So there isn't one fixed cost per 1,000 results. SociaVault gets cheaper when each request gives you more data, which is why it worked out much cheaper for bulk posts than for full threads.
Usability
SociaVault is easy to get started with if you're comfortable with APIs.
There's no no-code interface.
You work through the API or its MCP server, and the output is JSON only.
If you want CSV or Excel exports, scheduling, or automatic delivery, you'll need to handle those separately.
Speed
SociaVault returned 790 comments from the full-thread test in 8:32, or 93 comments/min.
It was faster on the other three workloads:
- Reddit-wide search: 232 unique posts in 4:37, or 50 posts/min
- Keyword search within r/politics: 252 posts in 1:09, or 219 posts/min
- Latest posts from r/politics: 834 posts in 1:56, or 431 posts/min
SociaVault was much faster at collecting posts than full threads. The thread took more than eight minutes, while its two subreddit tests finished in under two minutes.
Scalability
SociaVault returned 834 posts in 1:56, or 431 posts/min.
At that rate, continuous collection projects to roughly 18.6M posts a month. That's a projection, not a tested monthly volume.
SociaVault has no concurrency control.
Customer support
SociaVault provides email support, with no live chat or ticket dashboard.
There is no public response-time or resolution data.
Best for: getting deep Reddit threads or lots of posts cheaply if you're comfortable using an API. There's no no-code interface, and you only get JSON.
3. Bright Data — Reddit Scraper API
- User rating: 4.7/5 from 68 reviews on Capterra, as of September 10, 2026
- My rating: 6.51/10
- Type: No-code + API + MCP
- Pricing: Starts at $1.50, scales to $1.30 per 1,000 results
- Strongest at: post records with subreddit size and related posts already included
| Pillar | Score /10 |
|---|---|
| Data | 7.5 |
| Cost | 7.0 |
| Usability | 8.0 |
| Speed | 3.5 |
| Scalability | 6.0 |
| Support | 6.5 |
| Overall | 6.51 |
Bright Data is an enterprise data collection platform with a dedicated Reddit Dataset API that delivers structured post and comment data at scale.
| Pros | Cons |
|---|---|
| Subreddit size on every post; related posts on 94–97% | Threads reached only 2 levels |
| Full 252-post search, no duplicates | Slowest on the full-thread test |
| Weak recency and newest-first ordering | |
| Only 50 of 1,000 requested posts returned |
Data
Bright Data returned 26 populated fields in Reddit-wide search and 24 in the r/politics search.
| Data | What you get |
|---|---|
| Post | ID, URL, title, body, embedded links |
| Author | Username and profile details |
| Comments | ID, text, author, upvotes, reply count |
| Reply structure | Nested replies and relationship fields |
| Engagement | Upvotes, comment count |
| Community | Name, member count, description |
| Related posts | Related-post suggestions |
| Media | Photos, videos, links |
| Status | Pinned, locked, moderator and other status flags |
| Time | Post and comment timestamps |
Bright Data's strength is the extra context around each post. In Reddit-wide search, it returned subreddit size on all 233 posts, related posts on 219, photos on 106, and videos on 25.
That extra data isn't consistent across every search, though.
Full thread
Bright Data returned 397 comments across two reply levels. You get top-level comments and direct replies, but deeper conversations are missing.
Posts and comments also come separately, so you'll need to combine them yourself if you want the full thread with its post.
Reddit-wide search
Bright Data returned 233 unique posts, but only 3 were from the last 24 hours. There's no newest-first option here, so it's much better at giving you richer posts than recent posts.
Keyword search within r/politics
It returned 252 posts, but the newest post appeared 6th, and only just over half (51%) were correctly ordered newest-first.
The richer data also dropped off here: only 2 posts had body text, with no photos or videos returned.
Latest posts from r/politics
Bright Data returned just 50 posts when I asked for up to 1,000, with no option to increase that limit in this test.
Overall, Bright Data is strongest when you want more context around individual posts. The trade-off is shallower threads, weaker recency, and smaller subreddit collections.
Cost
Bright Data charges per returned record (one result), so the cost is easier to predict than request-based pricing.
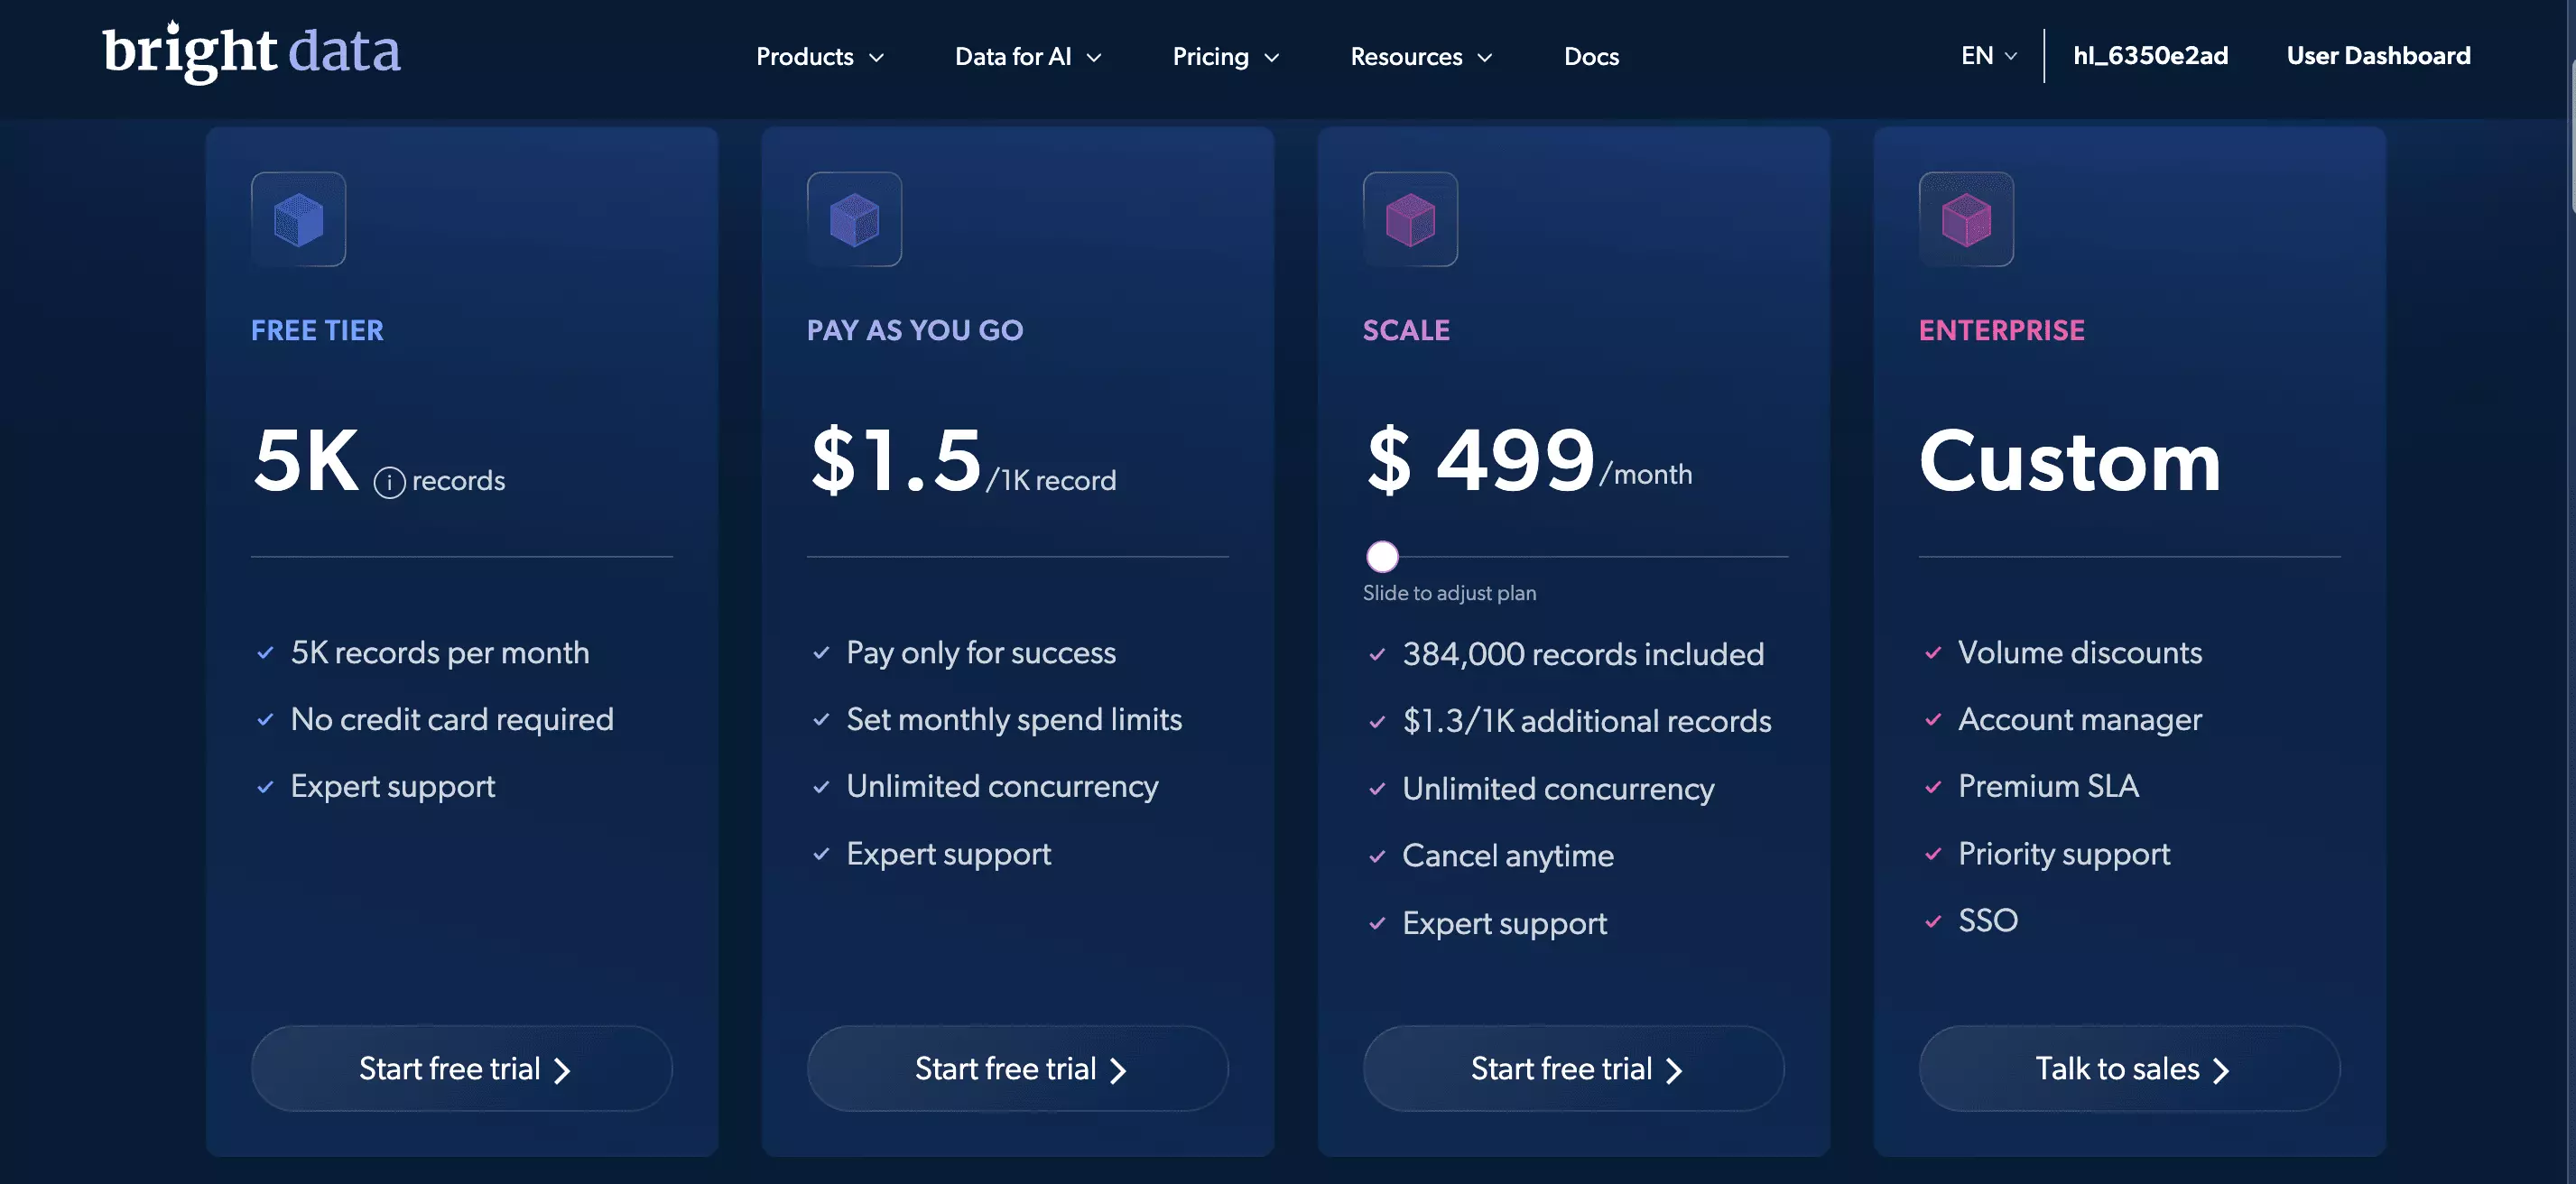
- Starting (pay as you go): $1.50 per 1,000 results
- At scale: $1.30 per 1,000 results
- Free tier: None
Bright Data doesn't bill every comment as a separate record. In the full-thread test it returned 397 comment objects but billed 291 records. You pay for billed output, not every backend request.
Usability
Bright Data uses separate scrapers for posts, comments, profiles, search, and subreddit discovery.
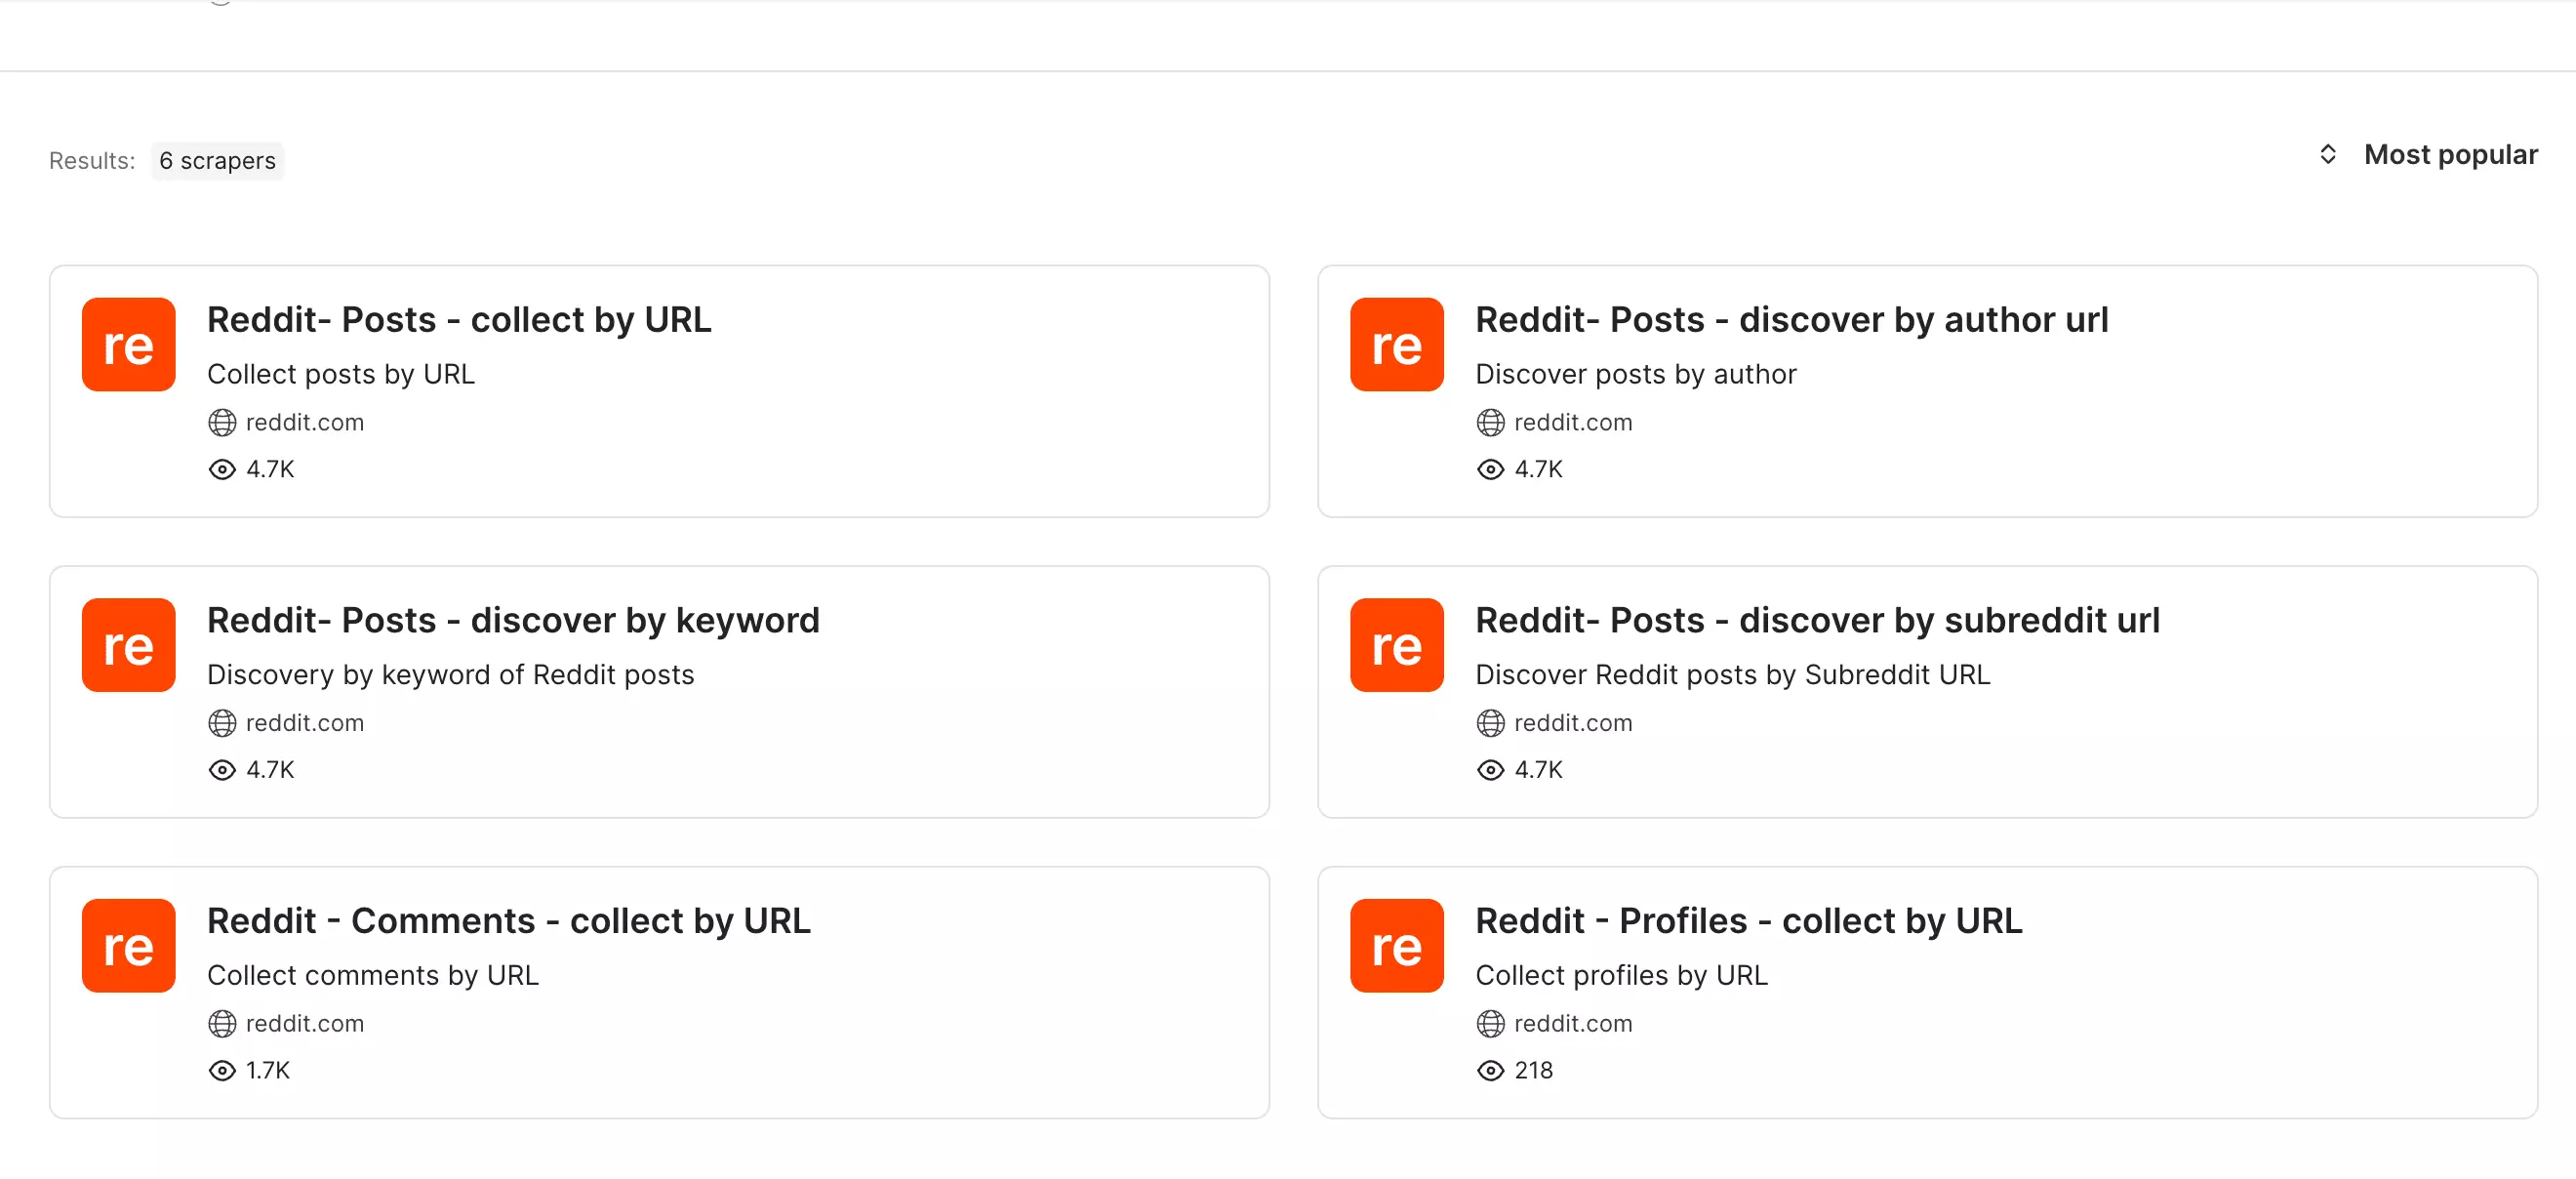
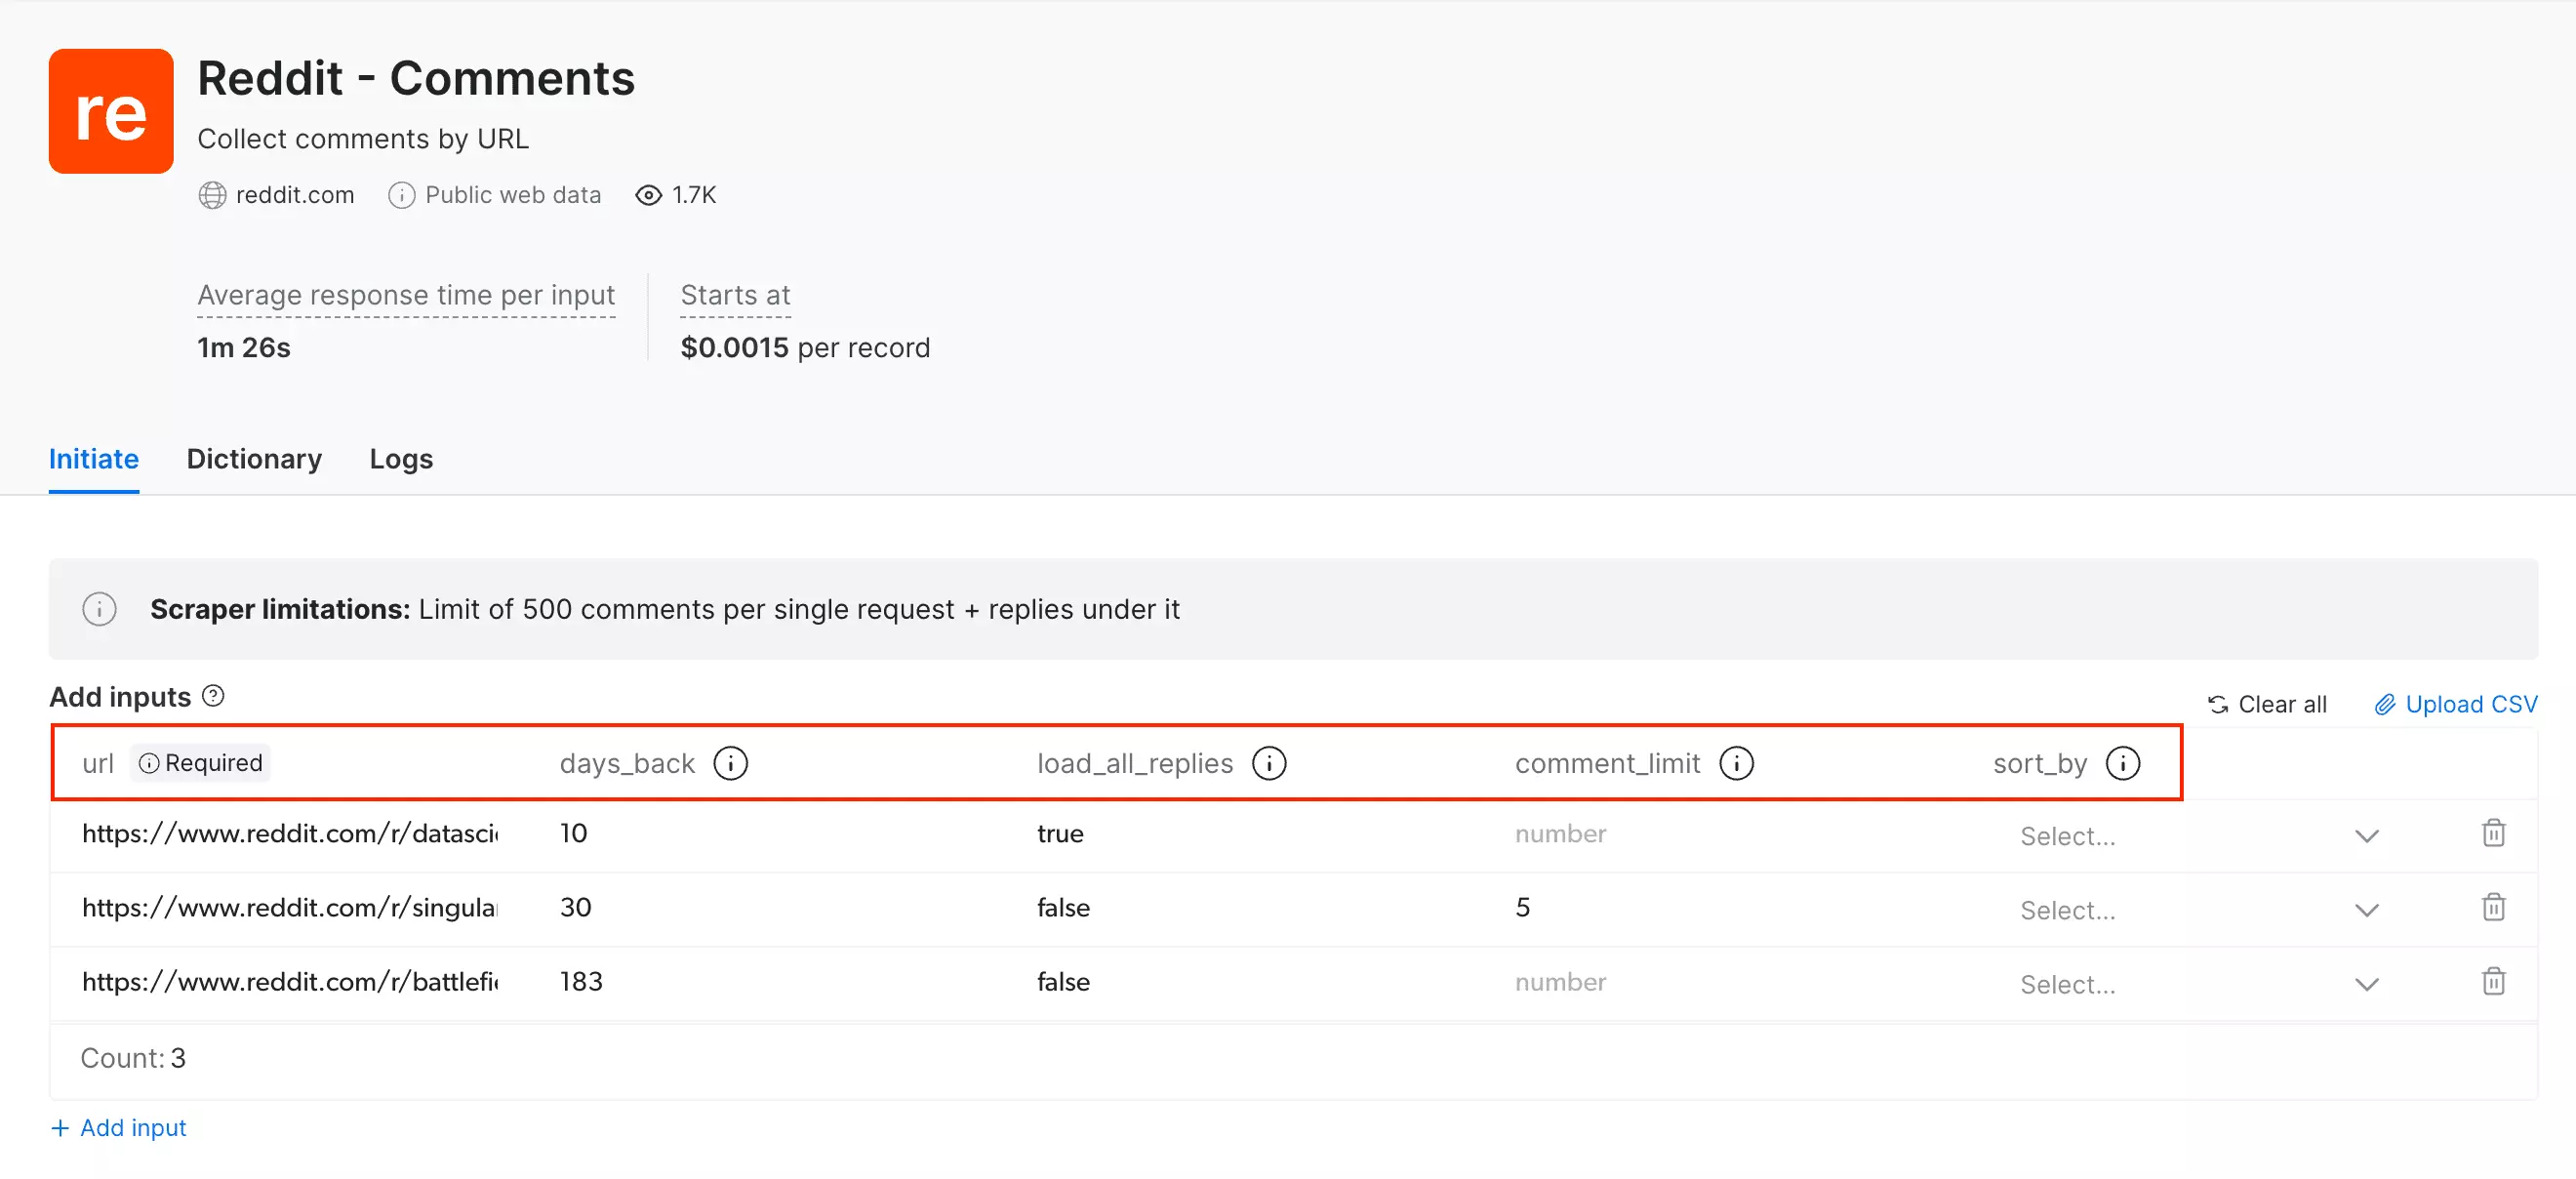
Inputs include URLs, keywords, subreddits, authors, profiles, and bulk CSV uploads.
Comment controls include time range, replies, limits, and sort order.
Results export as JSON, NDJSON, CSV, XLSX, or Parquet. Delivery includes S3, Google Cloud, Azure, Snowflake, SFTP, email, webhooks, and Pub/Sub.
The main friction is that posts and comments require separate collections and downstream joins.
Speed
Bright Data returned 397 comments from the full-thread test in 34:40, or about 11 comments/min.
Its post workloads were faster:
- Reddit-wide search: 232 unique posts in 10:23, or 22 posts/min
- Keyword search within r/politics: 252 posts in 7:43, or 33 posts/min
- Latest posts from r/politics: 50 posts in 3:44, or 13 posts/min
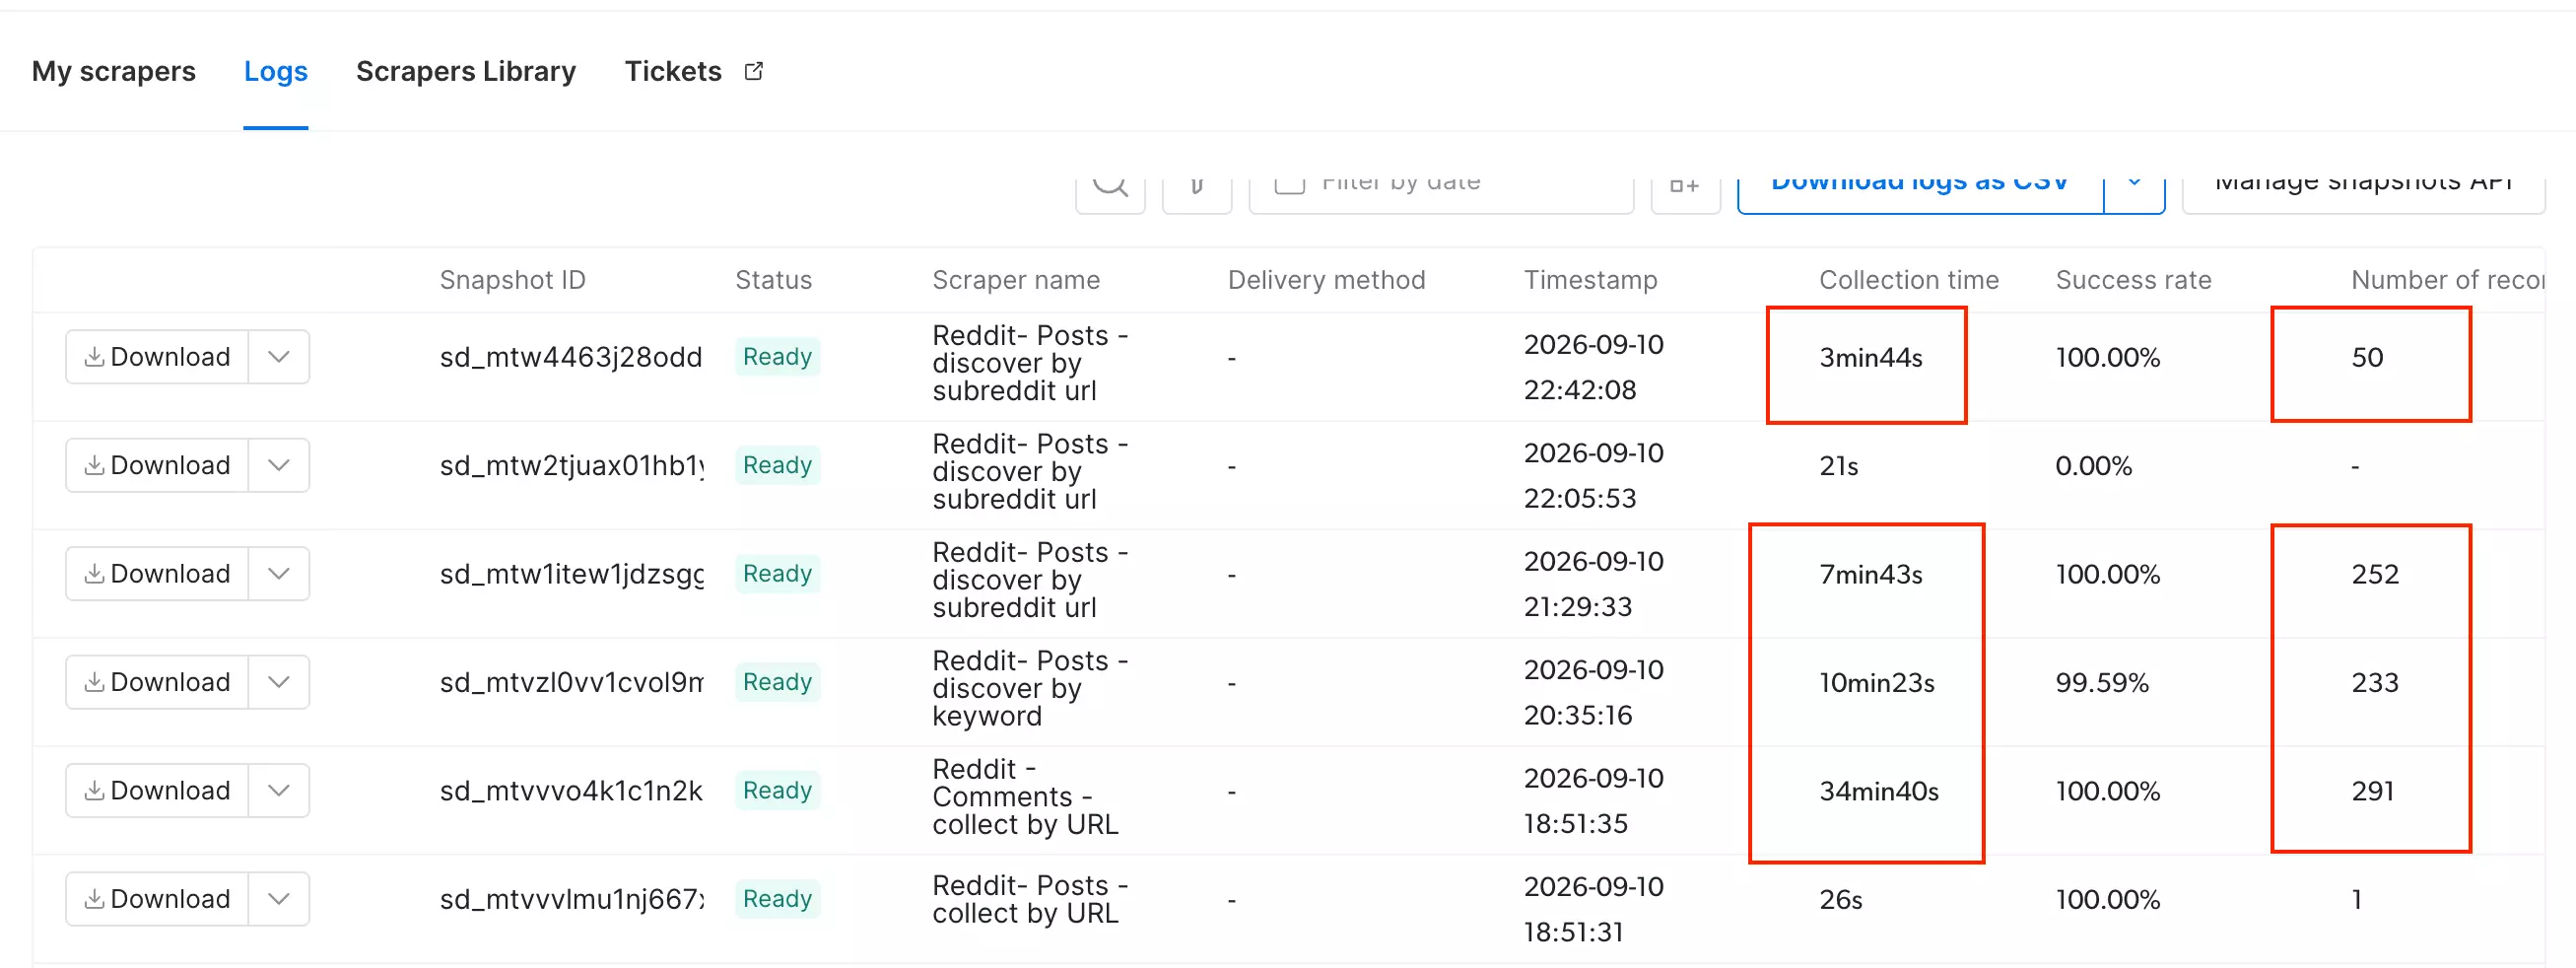
Bright Data was slowest on the full-thread test, taking more than half an hour.
Scalability
Bright Data returned 50 posts in 3:44, or about 13 posts/min.
At that rate, continuous collection projects to roughly 578,000 posts a month. That's a projection, not a tested monthly volume.
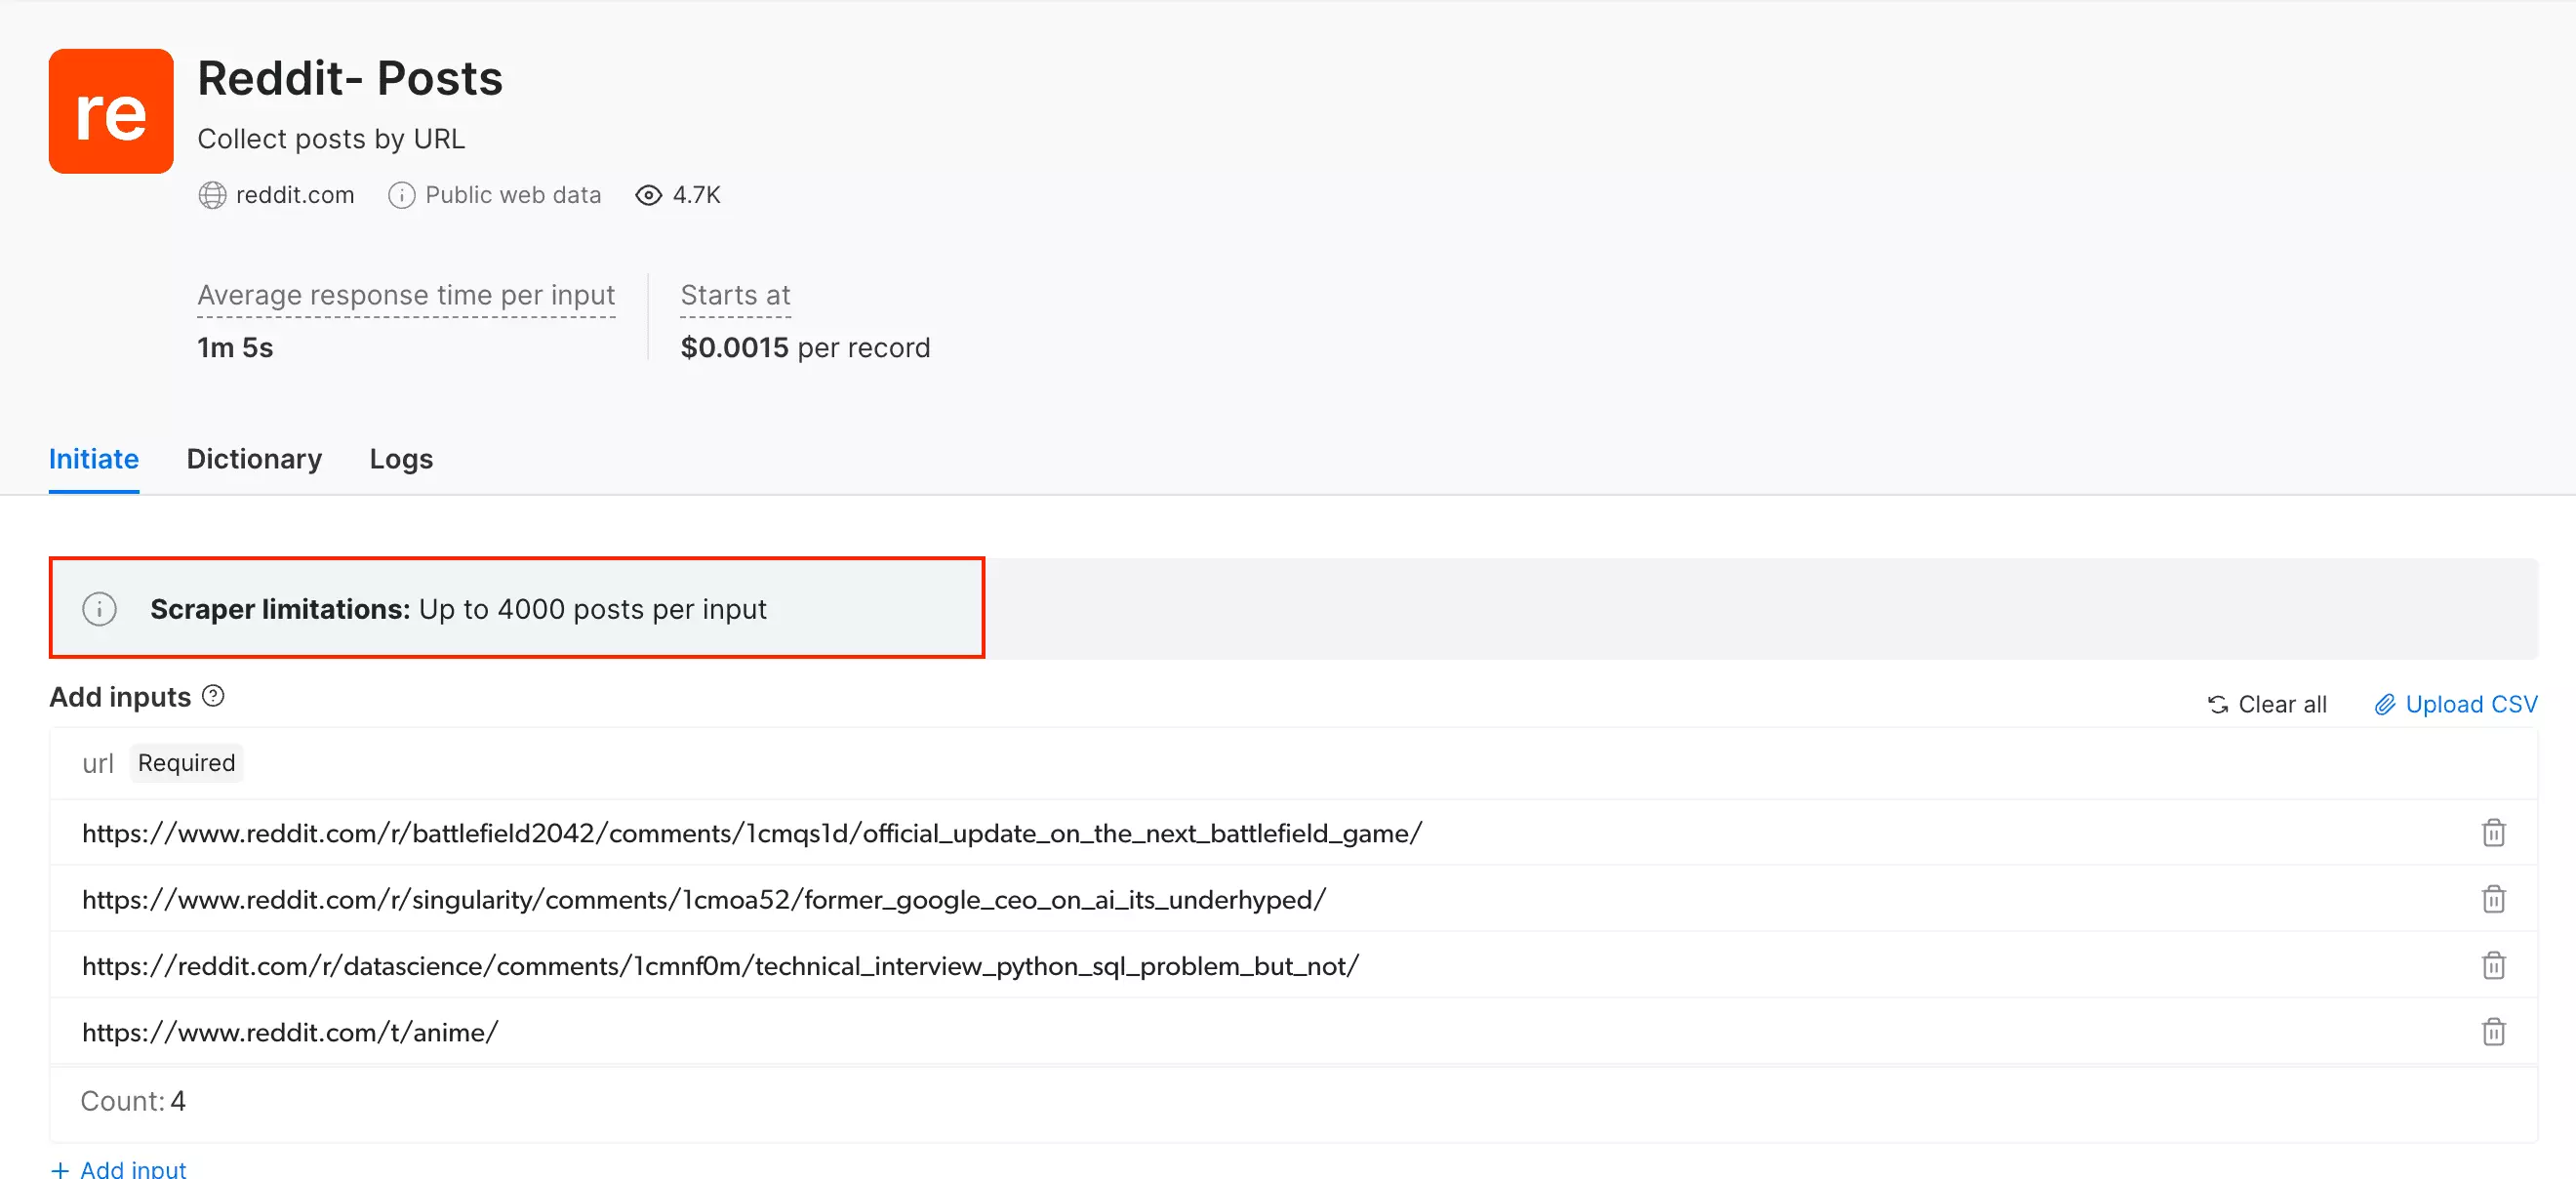
It has no concurrency control, and it caps each input at up to 4,000 posts or 500 comments, plus replies.
Customer support
Bright Data provides email and support tickets.
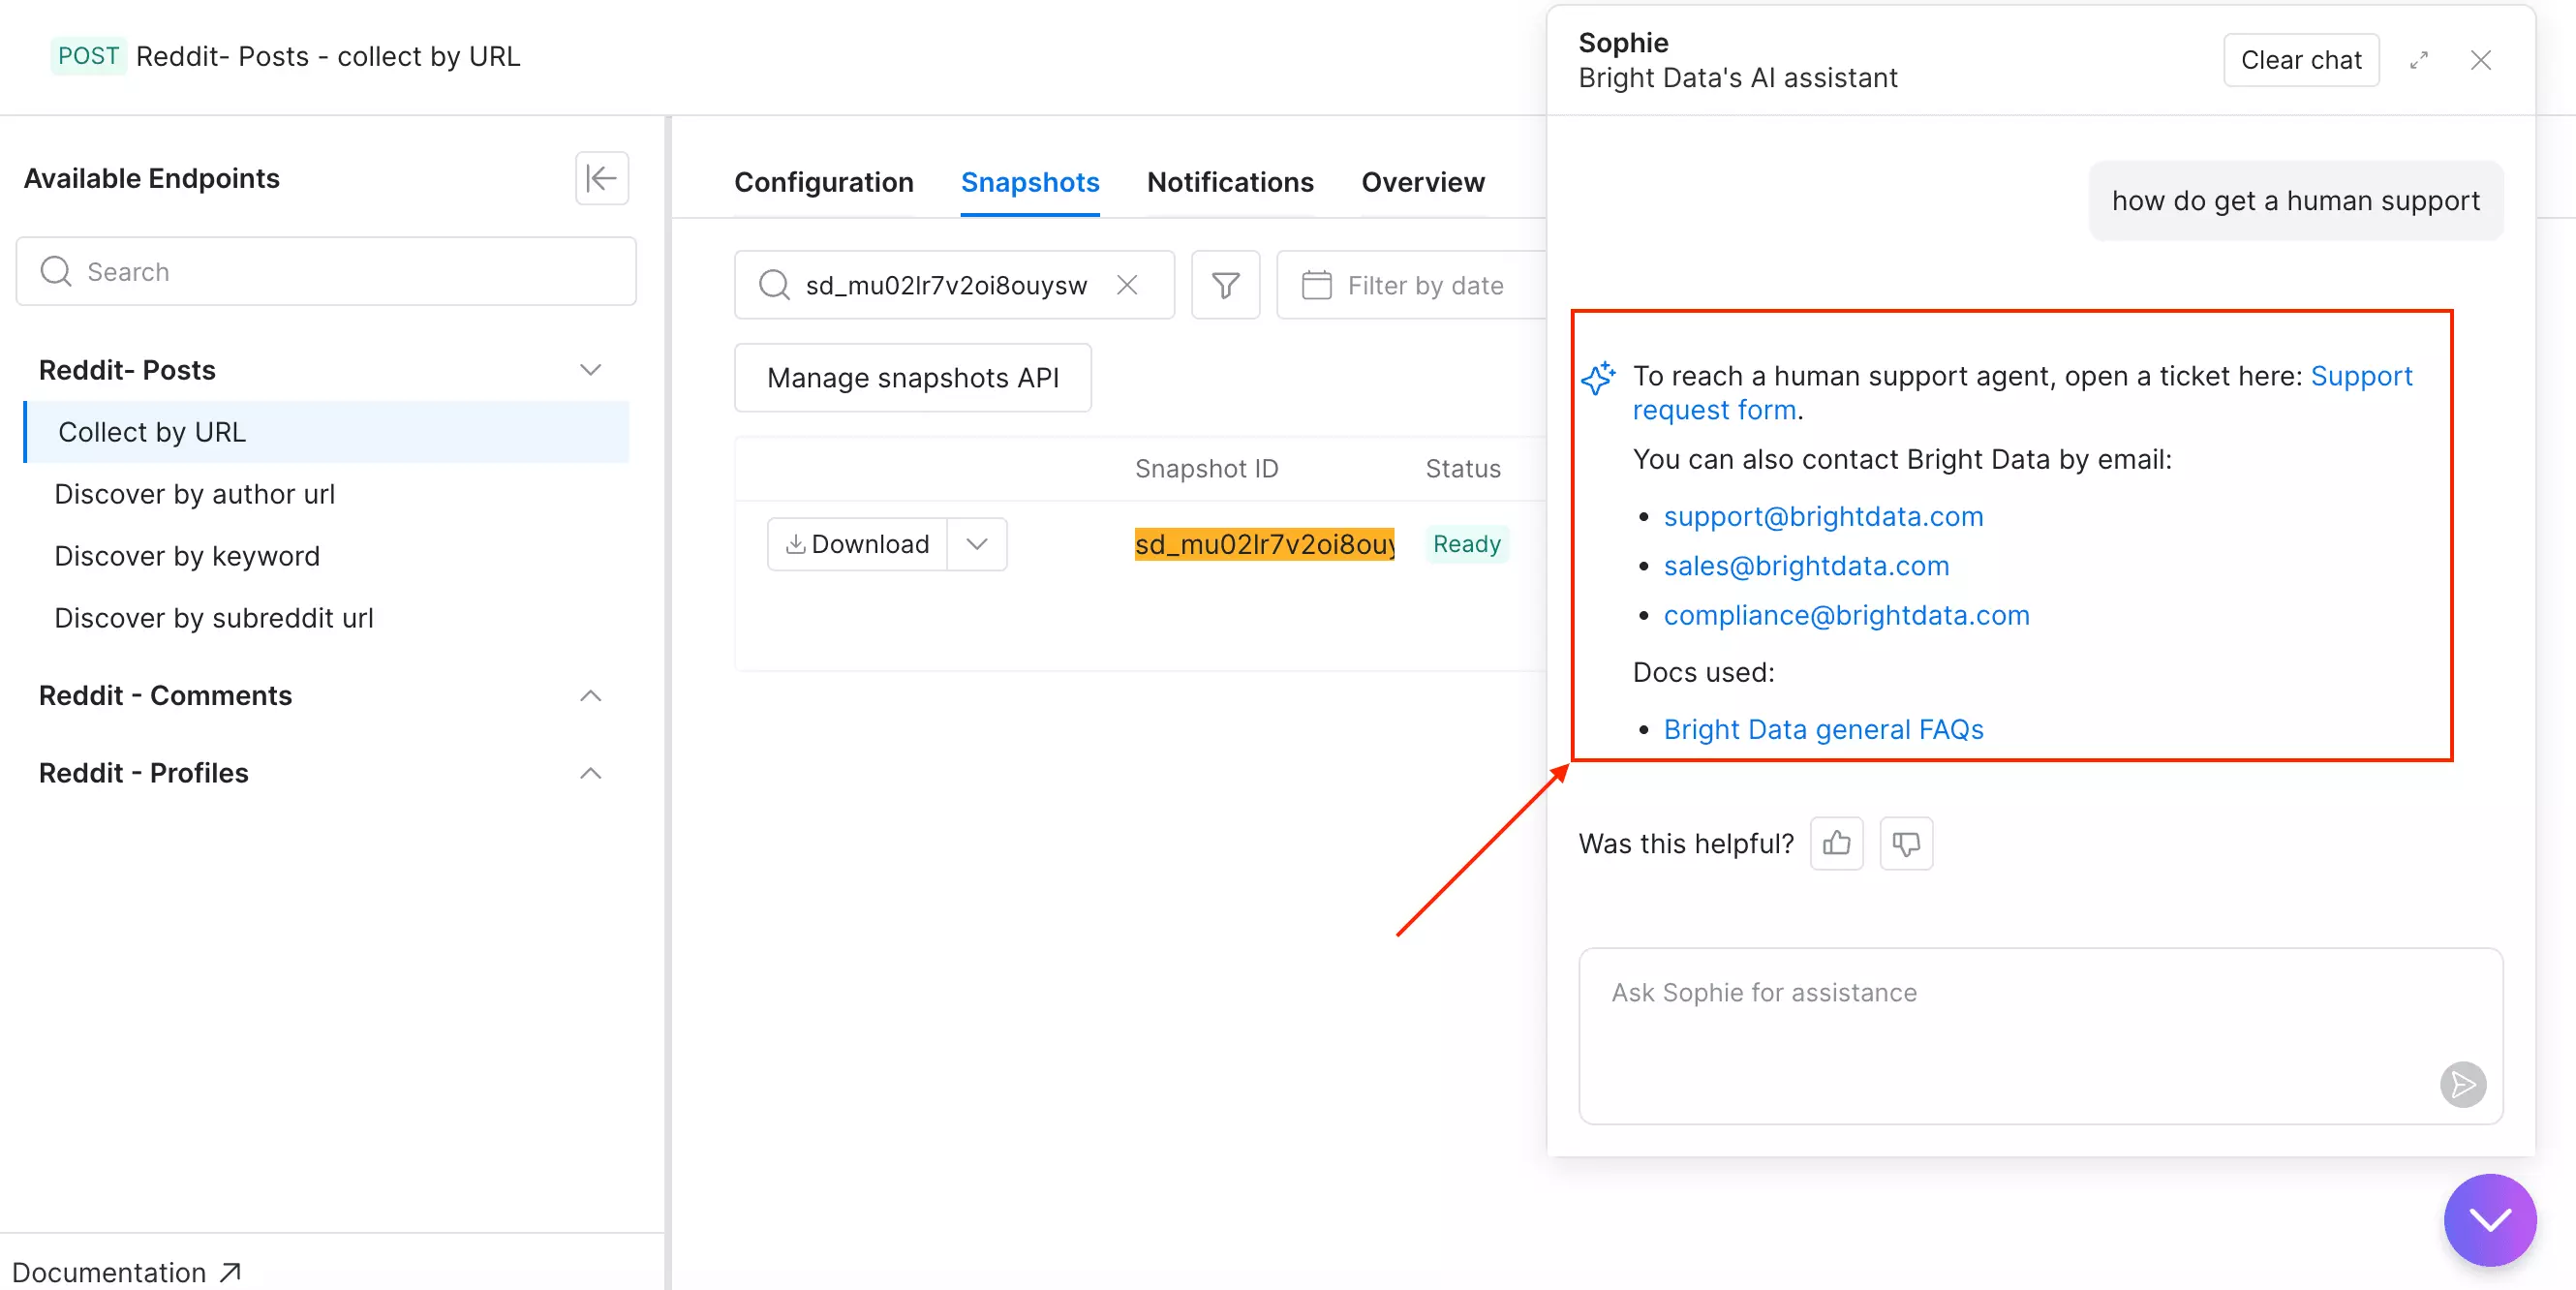
There was no comparable public response-time or resolution data in this test.
Best for: getting posts with subreddit size and related posts already included. It's less useful for deep threads or tracking the newest posts.
4. Apify — trudax/reddit-scraper-lite
- User rating: 4.6/5 from 39 reviews on the Apify Store, as of September 10, 2026.
- My rating: 6.00/10
- Type: No-code + API + MCP
- Pricing: Starts at $3.80, scales to $3.40 per 1,000 results, plus a fee on each run start
- Strongest at: finding posts across a broad range of subreddits
| Pillar | Score /10 |
|---|---|
| Data | 6.5 |
| Cost | 4.5 |
| Usability | 9.5 |
| Speed | 4.0 |
| Scalability | 6.0 |
| Support | 5.5 |
| Overall | 6.00 |
Apify is a cloud-based scraping platform with a large marketplace of community-built actors, including several Reddit scrapers.
| Pros | Cons |
|---|---|
| Broad Reddit-wide discovery | Threads limited to 2 levels deep |
| Lots of controls and automation options | Slow search performance |
| Most expensive ranked scraper | |
| Slow support |
Data
Apify returned 10 populated post fields consistently across the four tests.
| Data | What you get |
|---|---|
| Post | ID, URL, title, body |
| Author | Username, comment author flair |
| Comments | ID, body, HTML body, author, timestamp |
| Reply structure | Parent ID, depth, reply count |
| Engagement | Upvotes, upvote ratio, comment count |
| Community | Name, description, member and activity data |
| Media | Image URLs, outbound link, content type |
| Time | Created at |
Full thread
Apify returned 200 comments across two reply levels from the 1,183-comment thread.
So you get the main comments and some replies, but not the deeper conversation underneath them.
Reddit-wide search
This is where it did best: 325 posts across 175 subreddits, more than anything else I tested.
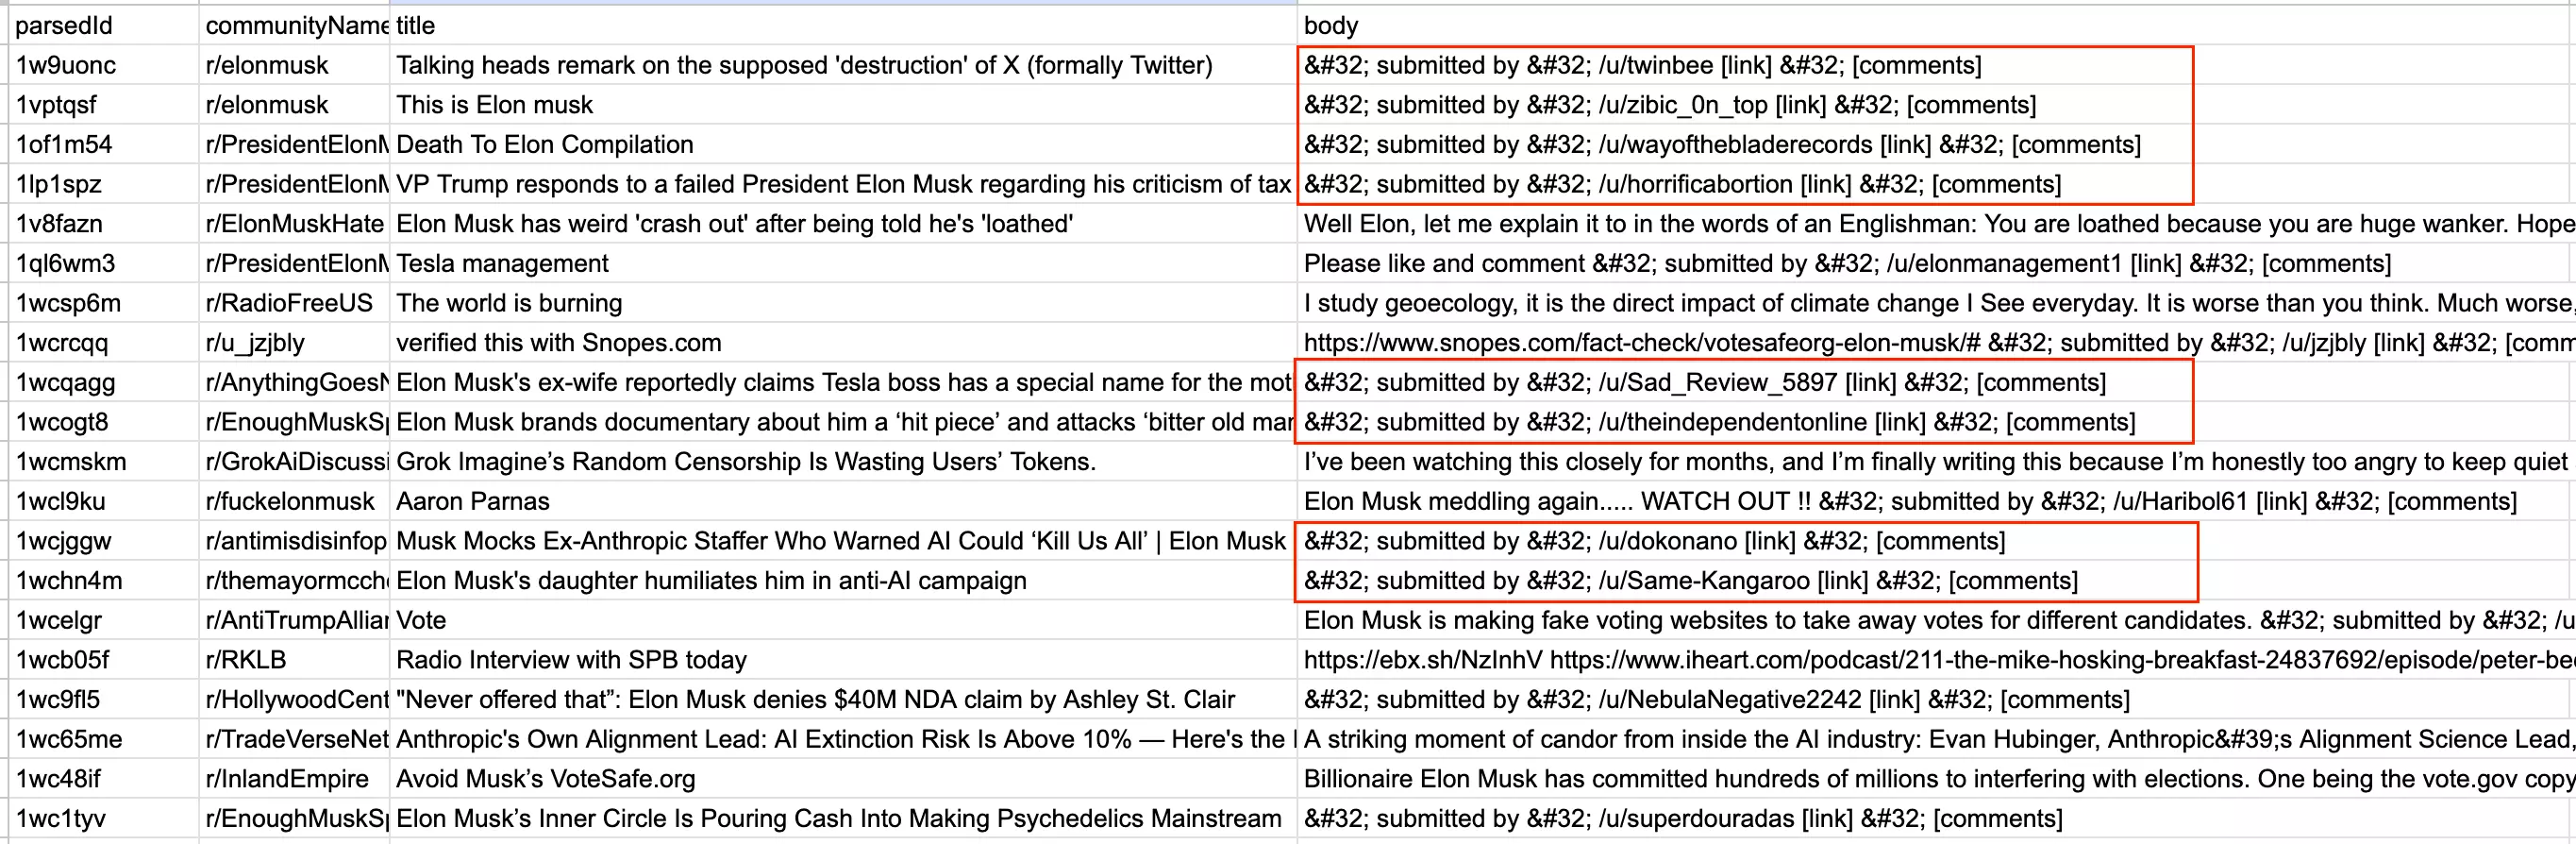
The catch is cleanup: only 77% were from the last day, and 197 of 325 bodies held feed boilerplate, not text.
Keyword search within r/politics
Apify returned 239 posts, just short of the 252 found by lobstr.io and SociaVault.
Ordering was strong: 96% were correctly sorted newest-first.
Latest posts from r/politics
This was much more limited. Apify returned only 53 posts.
Overall, Apify makes the most sense when you want to find posts across lots of subreddits. It's less useful when you need deep conversations, complete post text, or large collections from one subreddit.
Cost
Apify runs on a monthly subscription.
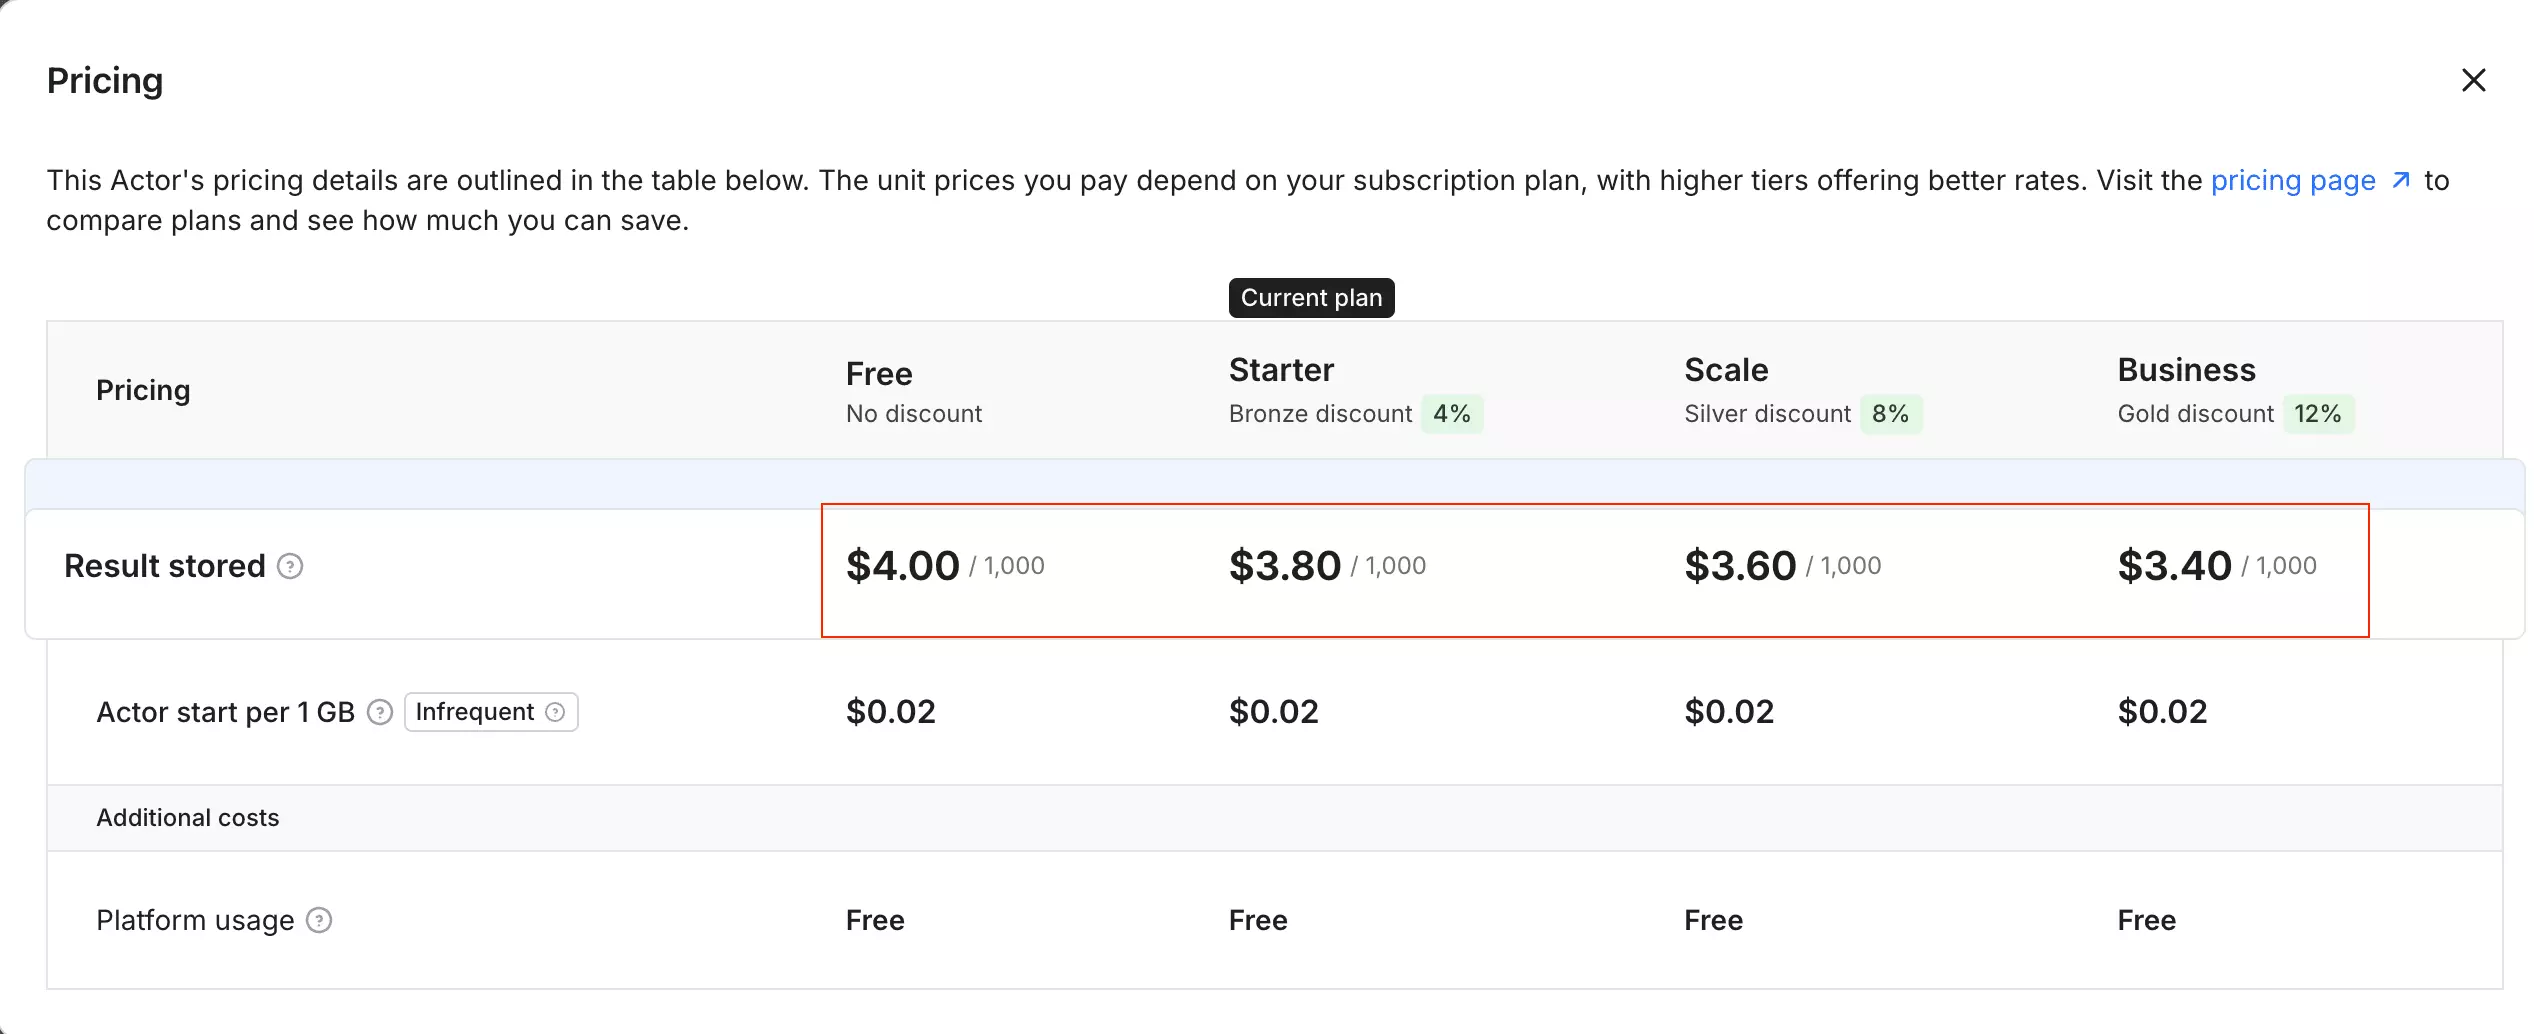
- Free plan: $5 of monthly platform usage
- Starts at: $3.80 per 1,000 results
- Scale: $3.40 per 1,000 results
There's also a run-start fee based on memory, so the final cost can be higher than the per-result price alone.
This was the most expensive scraper in the ranked group.
Usability
Apify supports Reddit URLs, bulk URLs, keyword search, and subreddit-scoped search.
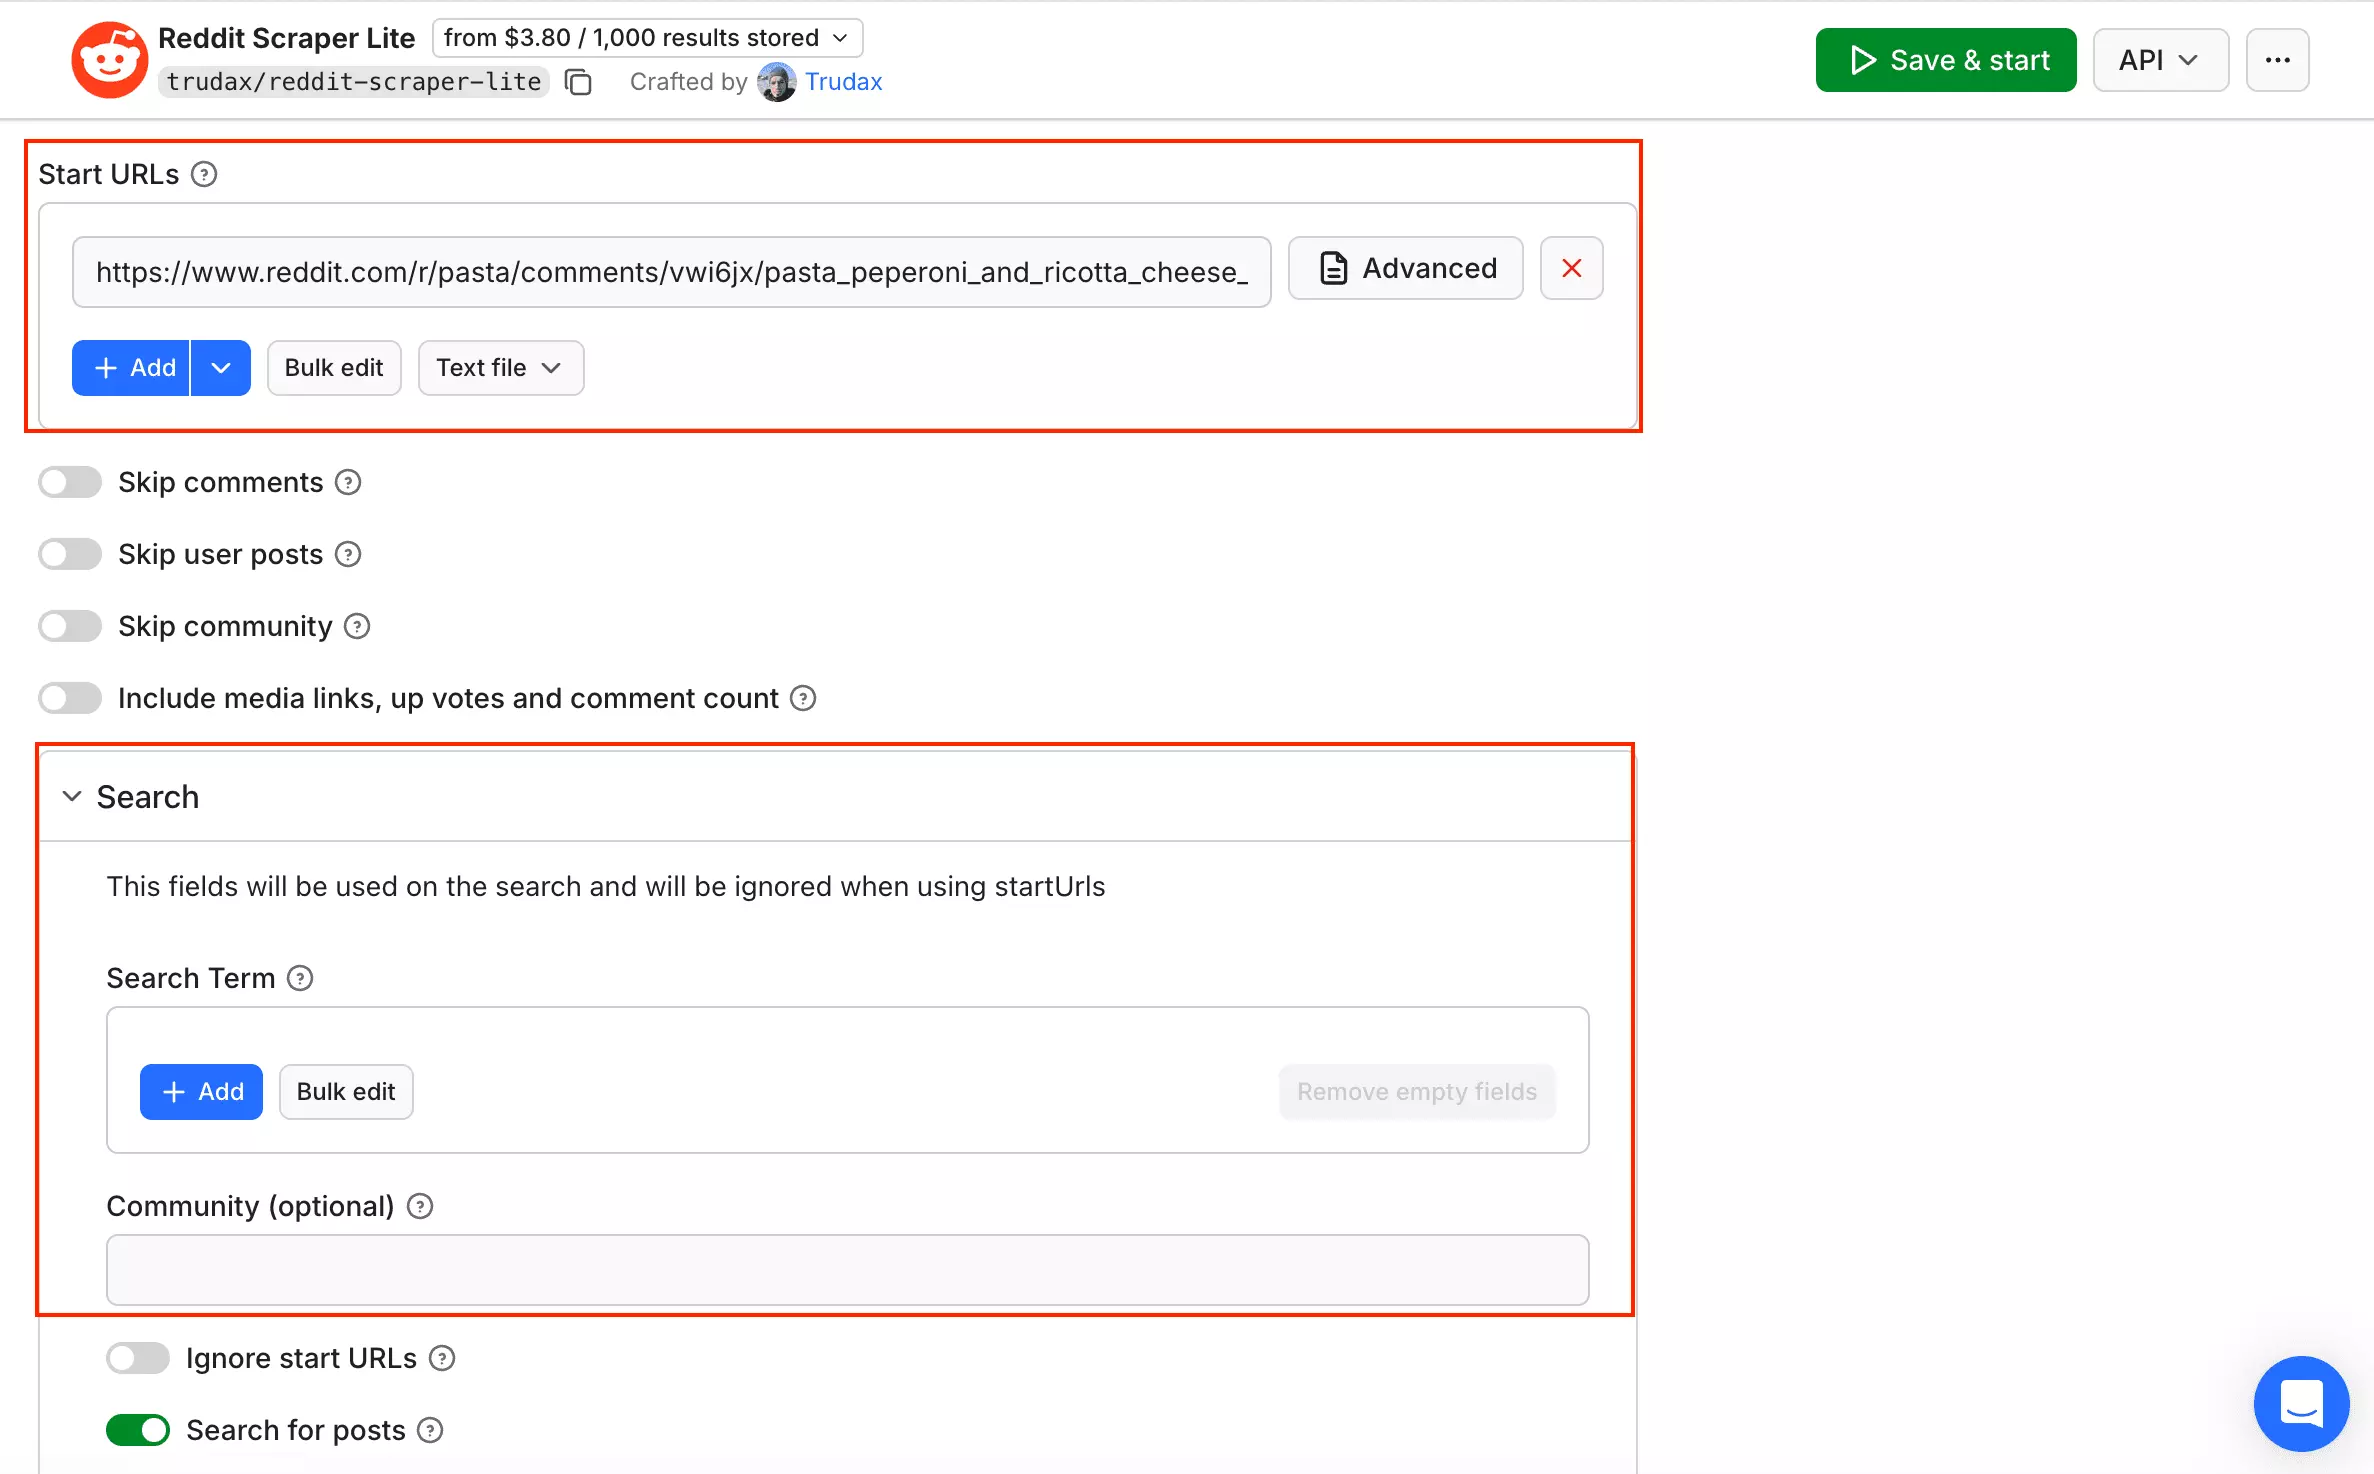
Its controls are the most extensive here. They cover extraction mode, scope, sorting, dates, NSFW content, and result limits.
Results export as CSV, Excel, JSON, JSONL, and other dataset formats.
Apify also supports APIs, webhooks, Make, Zapier, n8n, scheduling, and run monitoring.
Nothing else here gives you this much control, and nothing else asks for this much setup first.
Speed
Apify returned 200 comments from the full-thread test in 31 seconds, or about 389 comments/min.
Its post workloads were much slower:
- Reddit-wide search: 325 posts in 21:23, or 15 posts/min
- Keyword search within r/politics: 239 posts in 20:56, or 11 posts/min
- Latest posts from r/politics: 53 posts in 3:57, or 14 posts/min
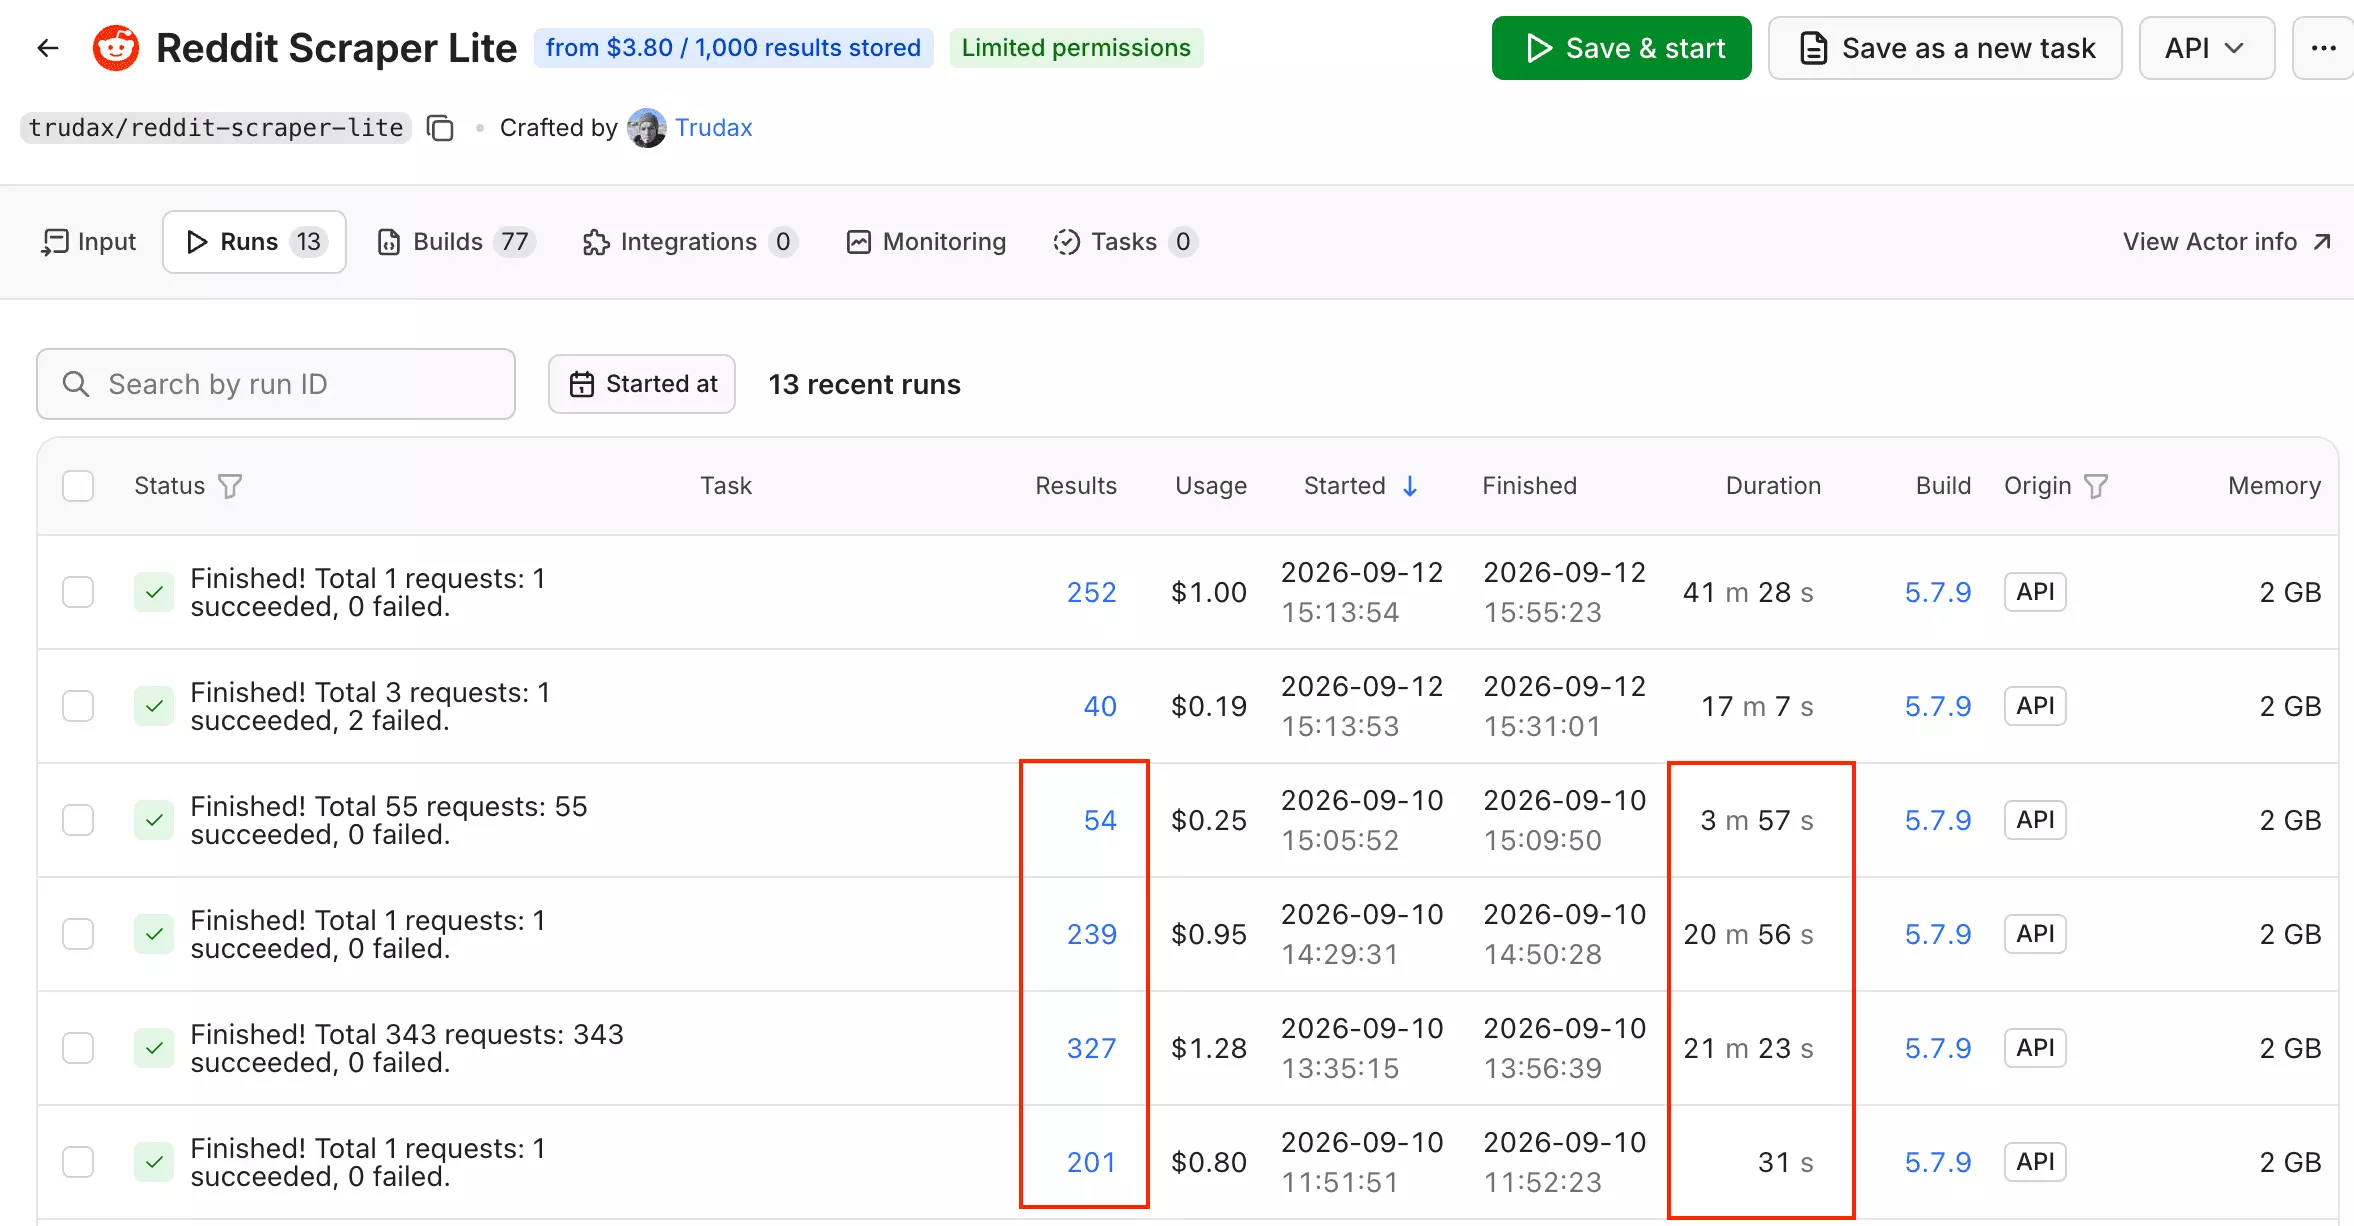
Apify's 31-second thread run was fast, but shallow: it stopped at 200 comments across two levels. For finding posts, it was much slower, with both search tests taking around 21 minutes.
Scalability
Apify returned 53 posts in 3:57, or about 14 posts/min.
At that rate, continuous collection projects to roughly 577,000 posts a month. That's a projection, not a tested monthly volume.
Apify has no concurrency control. Instead you scale with memory. I tested at 2 GB; the Actor allows up to 4 GB, which could raise throughput.
Customer support
Support for this actor primarily runs through Apify Issues.
At the time of checking, 92 of 94 issues were closed. The listed response time was 3.5 days.
One open issue had waited four days without a reply.
Issues do get closed. Just not quickly, which matters when a scraper breaks mid-project.
Best for: finding posts across lots of subreddits and having plenty of control over the scrape. Search is slow and expensive, and threads only go two levels deep.
The scrapers that didn't make the list
These tools can still handle parts of a Reddit scraping workflow. I left them out because each missed something important.
Outscraper
Outscraper is a cloud-based data extraction platform that allows users to scrape public web data, including Reddit.
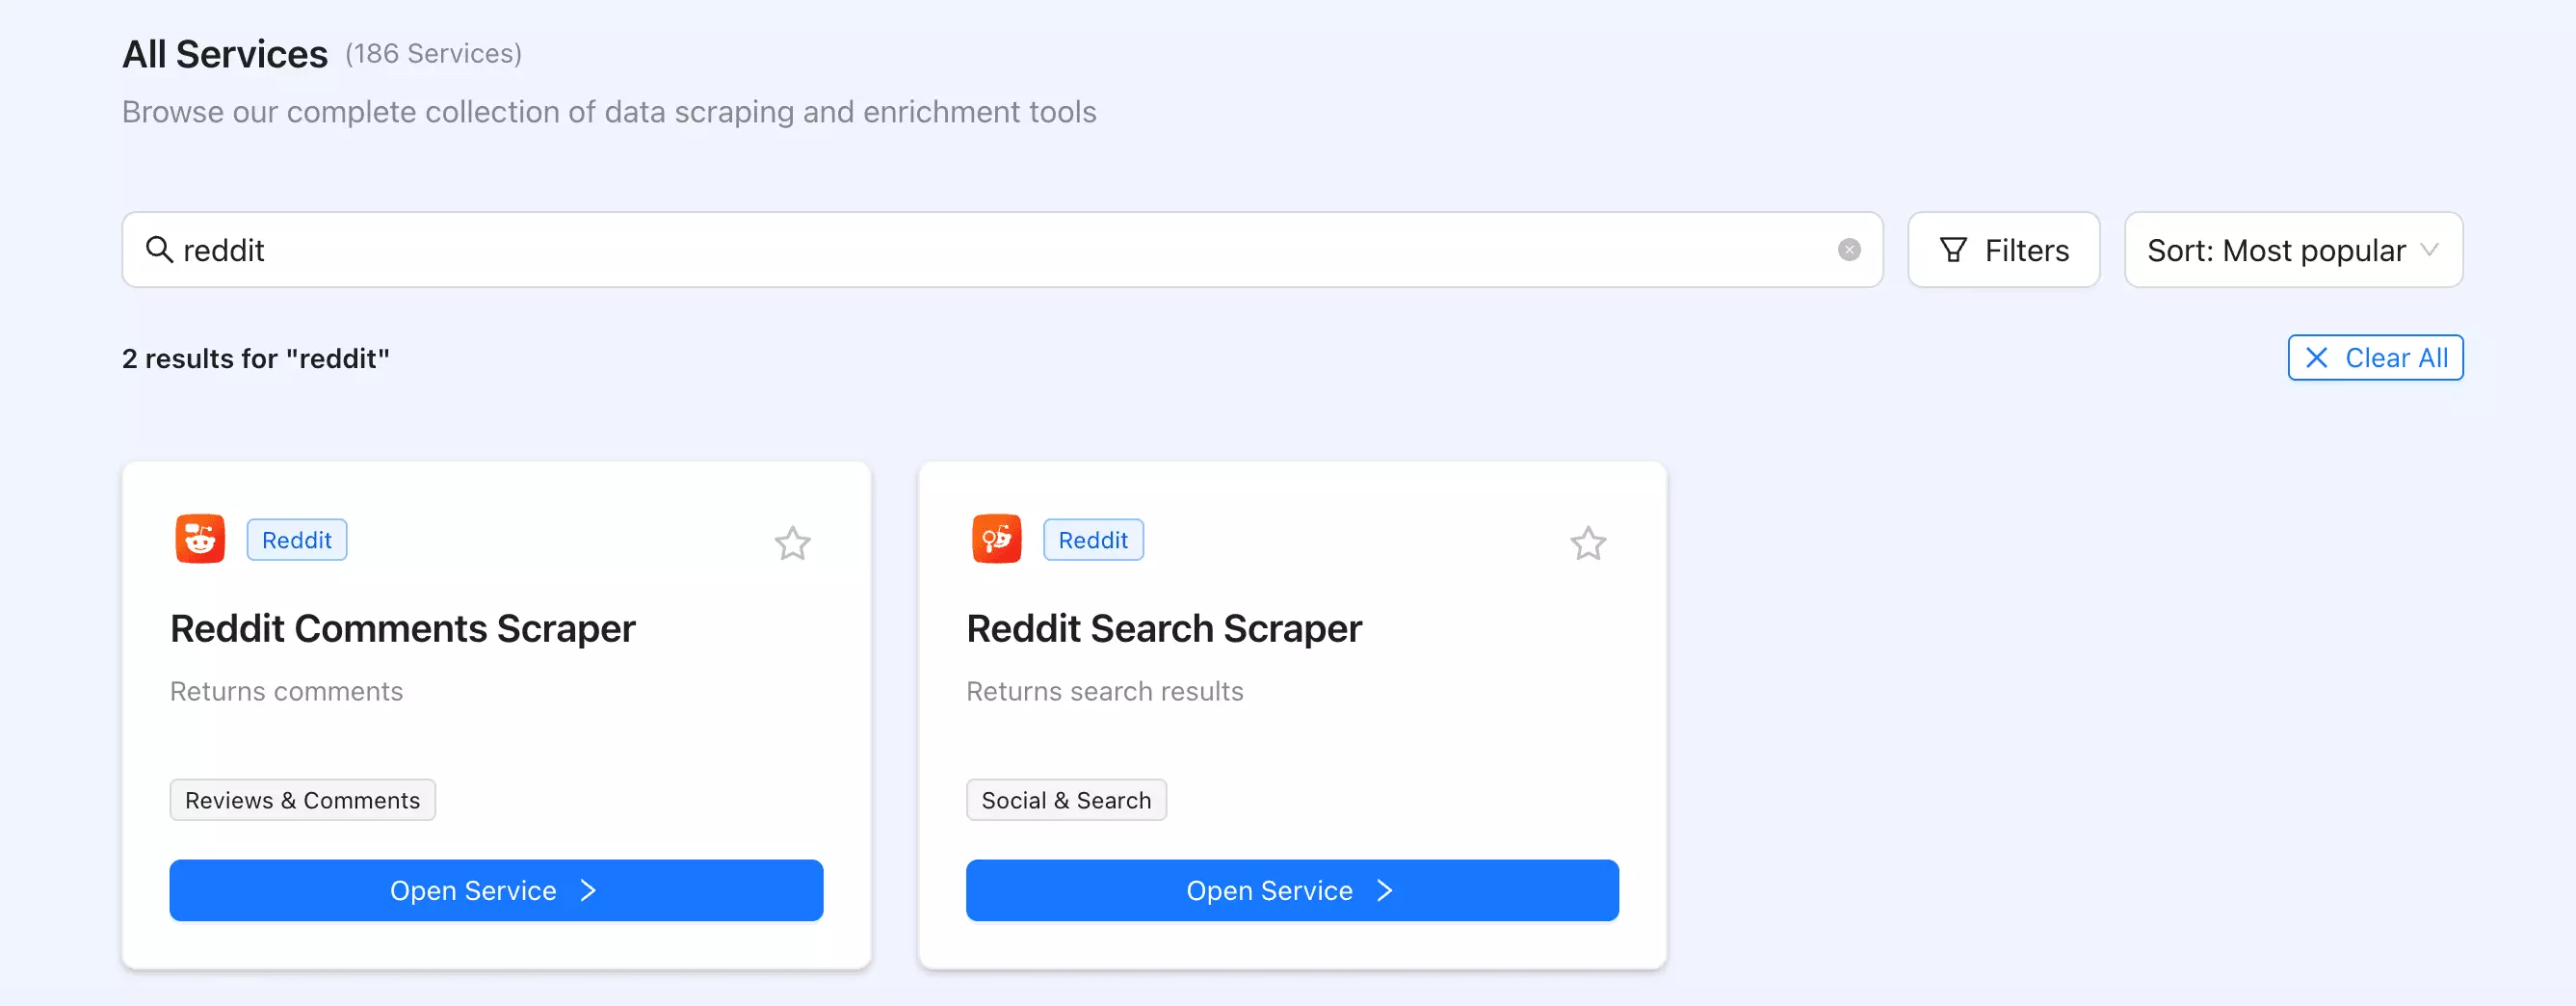
It offers two separate Reddit tools: a Reddit Comments Scraper and a Reddit Search Scraper.
Why it didn't make the list
The comment output is flat. There is no parent ID or depth, so you cannot reconstruct who replied to whom.
It also returned zero posts in my search and listing tests.
Worth knowing
Its successful test returned 470 unique comments with all nine fields populated. If you only need comment text, author link, and score, and flat output is fine, it can do that job.
ScraperAPI
ScraperAPI is a general-purpose proxy tool, not a Reddit scraper. I don't recommend it for Reddit at any scale.
Why it didn't make the list
The main problem is comments. It does not return parent IDs or comment depth, so the original conversation tree cannot be reconstructed.
That is too large a limitation for a Reddit scraper recommendation where comment threads matter.
Worth knowing
For simpler post scraping or flat comment collection, it is still useful. It has a straightforward API and can return basic Reddit fields without much setup.
SerpApi
SerpApi is a search engine results API that surfaces Reddit posts via Google's index. It searches Google, not Reddit directly.
Why it didn't make the list
SerpApi is mainly a Reddit discovery tool.
It can find Reddit posts by keyword, but it does not scrape full comment threads, subreddit feeds, user profiles, or post body text.
That scope is too limited for this comparison.
Worth knowing
For finding Reddit posts, SerpApi is still useful. It supports Google-based discovery as well as a dedicated engine=reddit endpoint.
So if you only need to find relevant Reddit posts, rather than scrape complete Reddit data, it is worth considering.
FAQ
Which Reddit scraper is best for comments and replies?
lobstr.io for speed, SociaVault for thread structure.
Both returned 784 live comments across five levels. SociaVault also preserved six deleted placeholders, while lobstr.io finished much faster at 2 min 33 sec vs 8 min 32 sec.
Which Reddit scraper handles larger subreddit collections best?
lobstr.io went furthest in our test.
It returned 943 organic posts in one run, against 834 for SociaVault and roughly 50 for Bright Data and Apify.
Which Reddit scraper has the most predictable pricing?
lobstr.io.
It charges 1 credit per result (one post or comment), a flat $2.00 per 1,000 results starting and $0.50 at scale.
SociaVault charges per request, so its effective cost varies by workload. Bright Data charges per record, while the tested Apify actor charges per result plus a run fee.
Which Reddit scraper is cheapest?
It depends on the workload.
SociaVault was cheapest for post collection in our tests, at $0.10–$0.31 per 1,000 posts at scale.
For full threads, lobstr.io is $0.50 per 1,000 results at scale, compared with $0.75 per 1,000 comments for SociaVault at scale in our test.
Conclusion
The best Reddit scraper depends on what you're collecting.
- lobstr.io owns deep, fast Reddit collection. It handled long threads and large subreddit runs without giving up much speed.
- SociaVault owns cost. It was the cheapest for bulk posts and still preserved deep thread structure, but there's no no-code interface.
- Bright Data owns post context. Subreddit size and related posts were its real advantage, but threads and recency were weaker.
- Apify owns broad discovery. It found the most posts across the most subreddits, but search was slow and expensive.
Reddit and these tools will keep changing, so I'll keep this comparison updated.
Found something I should test? Ping me on LinkedIn.
Ready to scrape Reddit? Try the Reddit Scraper.
Scrapers in this article
Keep reading
 Shehriar Awan23 Sept 2026No CodeHow to Scrape Reddit: Posts, Comments & Subreddits (No Login)
- Shehriar Awan25 Sept 2026YouTubeHow to Scrape YouTube Channels with Emails at Scale: No-Code Guide
- Nathan Eshetu26 Aug 2026No CodeBest LinkedIn Leads Scrapers 2026 [No-Code + API Edition]
- Nathan Eshetu10 Aug 2026Social MediaBest Instagram Post Scrapers 2026 [No-Code + API Edition]
- Nathan Eshetu5 Aug 2026Web ScrapingBest Instagram Profile Scrapers 2026 [No-Code + API Edition]