image
Coin

1

free
new

Threads Scraper

Extract every post from any Threads profile, keyword or tag68 data points per post, no login.

Download sample

Trusted worldwide by the best

Export posts from Threads — right now

Extract

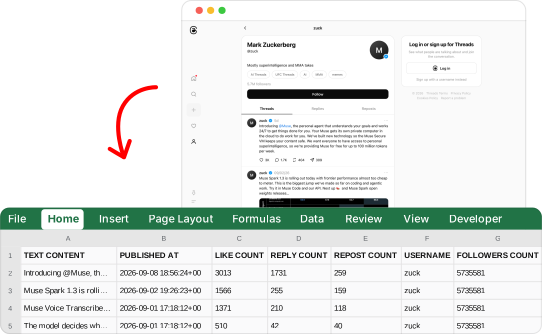
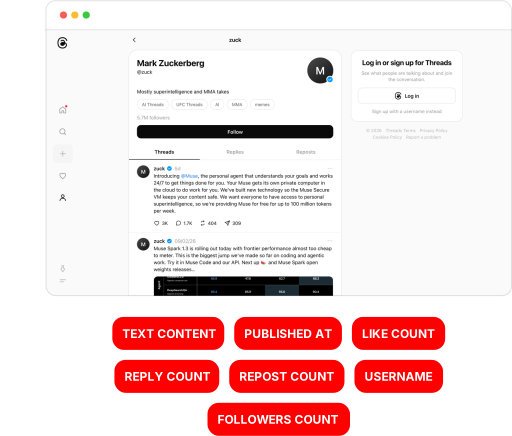
Give it a Threads profile, an @handle, a keyword, a #tag or a single post and get every public post as a row — text, date, likes, replies, reposts, views, media links and full author details: 68 data points per post.
image

Schedule

Automate Threads data collection on daily, weekly, or monthly schedules.

image

Export

Export all post data to Google Sheets, email, or S3 — fully automated.

image

Built for Agents

Run it from your stack.
Or hand it to your agent.

Threads Scraper ships with a Python SDK, a one-line CLI and a native MCP server your agents can plug into directly — no rate limits to dodge, no bot mitigation to bypass, no parsing errors to chase down.

# install once (Python 3.10+)
pip install lobstrio

# check your token
lobstr whoami

# find the scraper
lobstr crawlers search "Threads"

# one call — launch, wait, download
lobstr go threads-scraper \
  "<any Threads URL>" \
  --param max_results=200 \
  -o results.csv

68 data attributes per post

Every scrape returns structured data you can export as CSV, JSON, or via API.

Post Url

Direct URL of the post, built from the author handle and the post code.

Export Posts
Post Id

Numeric identifier of the post (`post/pk`).

3981852126213720917
Export Posts
Post Code

Short code of the post used in its URL (`post/code`).

DZpPDXbCeTt
Export Posts
Record Type

Row discriminator: `post` for a root post, `reply` for a reply collected from a post permalink or a search thread.

post
Export Posts
Source Tab

Where the row came from: `posts` (profile crawl), `search` (keyword/tag search) or `permalink` (single post URL).

posts
Export Posts
Search Keyword

Keyword or tag searched for. Populated on search rows only.

openai
Export Posts
Scraped At

UTC timestamp at which the row was collected.

Sep 13, 2026
Export Posts
Text Content

Full text of the post, reassembled from the caption and the text fragments.

Muse Code is out of beta and now built to handle bigger engineering tasks.
Export Posts
Published At

Publication date of the post in UTC (`post/taken_at`).

Jun 16, 2026
Export Posts
language

Language detected by Threads for the post (`post/detected_language`). Null when Threads did not detect one.

en
Export Posts
image

Fast

180 posts per minute
Lightning-fast performance

image

Solid

99.95% task success rate
Dependable, reliable data every time

image

Cost-competitive

$0.5 per 1000 posts
Top affordability worldwide

Live

Built to run.

Most scrapers break in silence. This one doesn't — and we show it, openly.

100.00%

incident-free runs · last 90 days

0
incidents · 90 days
100%
resolved
median time to fix
90 days agoToday
Operational
Degraded
Down
Resolved incident
Open incident
How we measure →

Tracked from every run. Incidents stay on the record even after they're fixed.

Simulator plan

Trusted by the best

Used obsessively by the data-hungry around the world

★★★★★
★★★★★
★★★★★
★★★★★
★★★★★
★★★★★

Frequently Asked Questions

Is it legal to scrape Threads?

Yes — a public Threads post is public data. Posts, engagement counts and author details are there for anyone who opens the page logged out, and that is all the crawler reads. The finer points live in our guide to the legality of web scraping.

Do I need a Threads account or login to use this scraper?

No login required, and nothing to sync. No account, no cookie, no browser extension — your own profile never takes part, so it is never at risk either. Private profiles stay private: the crawler sees only what a logged-out visitor sees.

What data do I get?

68 data points per post. The full text and when it went up, likes, replies, reposts, quotes, shares and views, hashtags, mentions, media links and the music behind a clip — plus the author's handle, name, avatar, verified badge, follower count and bio on every single row.

How fast is it?

Around 180 posts a minute. A profile's whole back catalogue lands while you are still deciding what to do with it, and a long list of profiles, keywords and tags moves at the same pace as a single one.

What can I give it as input?

Four kinds — a profile, a keyword, a tag or a single post. A profile URL or a bare @handle walks that profile back to its first post, a phrase or a #tag runs a Threads search, a post address returns that post. Mix all four in one list if you like.

Can I collect the replies under a post?

Yes — turn on Include Replies and hand it a post address. You get the post plus the replies shown underneath it, usually 20 to 25, each as its own row with its own author and counts. It is off by default, so a post costs one credit until you ask for more.

Can I scrape only recent posts?

Yes — set Fetch Since. A window like 24h, 7d or 2w, or a date in the timezone you pick, and anything older is left alone. A profile crawl stops at the first post that misses the cut, so a daily run never re-reads the whole archive.

How many posts can I scrape from one profile?

All of them — left uncapped it goes down to the very first post. Set a maximum per input for a smaller export, or one for the whole run, which also weeds out the posts two keywords both turned up. One credit per post, either way.

Do I get the images and videos attached to a post?

Yes — links, type and size for every photo, video, GIF and sticker. The caption rides along, and so do the title and artist of any audio track. The files stay where Threads keeps them and you get direct links, so no saving them one by one.

Where can I send the posts once they are scraped?

Just about anywhere you already work. Google Sheets, Make, n8n, Amazon S3, email, webhooks — plus our MCP server, so Claude or ChatGPT can launch a run and read the posts back. CSV, Excel and JSON downloads too. See all integrations.

Ready to get started?

Export your first posts for free.

Contact sales