

1
Similarweb Scraper
Extract every traffic, audience & ranking metric from any website — 93 data points each.
 0 users
 0 runs
Trusted worldwide by the best
Export websites from Similarweb — right now
Extract
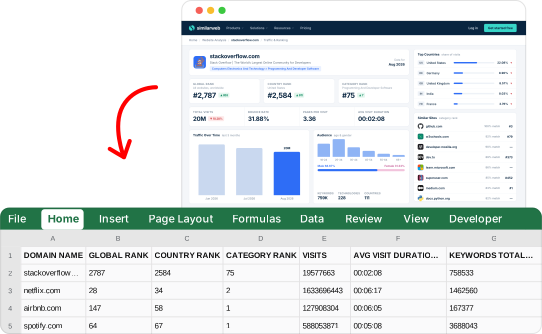
Paste any domain and get its whole Similarweb profile — traffic, rankings, audience, 93 data points.
Schedule
Automate Similarweb data collection on daily, weekly, or monthly schedules.

Export
Export all website data to Google Sheets, email, or S3 — fully automated.

Built for Agents
Run it from your stack.
Or hand it to your agent.
Similarweb Scraper ships with a Python SDK, a one-line CLI and a native MCP server your agents can plug into directly — no rate limits to dodge, no bot mitigation to bypass, no parsing errors to chase down.
# install once (Python 3.10+)
pip install lobstrio

# check your token
lobstr whoami

# find the scraper
lobstr crawlers search "similarweb"

# one call — launch, wait, download
lobstr go similarweb-scraper \
  "<any Similarweb URL>" \
  --param max_results=200 \
  -o results.csv
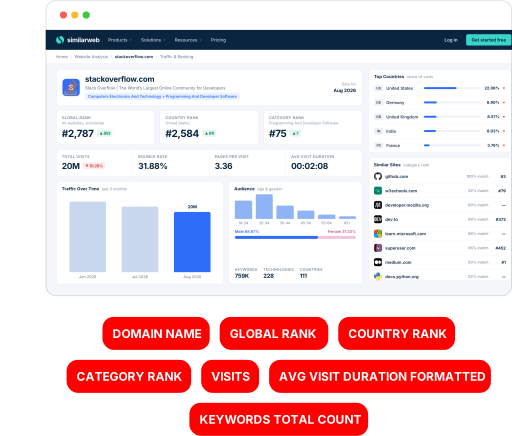
93 data attributes per website
Every scrape returns structured data you can export as CSV, JSON, or via API.
Domain the row describes, as Similarweb indexes it
Similarweb page this row was collected from
UTC timestamp of the collection
Month Similarweb's snapshot covers. Similarweb publishes one snapshot per month
False when Similarweb tracks no traffic for this domain: the row is kept but every metric is empty
Website description as published by Similarweb
Similarweb category the website is ranked in
Desktop screenshot of the website
Mobile screenshot of the website

Fast
30 websites per minute
Lightning-fast performance

Solid
99.95% task success rate
Dependable, reliable data every time

Cost-competitive
$0.5 per 1000 websites
Top affordability worldwide
Built to run.
Most scrapers break in silence. This one doesn't — and we show it, openly.
incident-free runs · last 90 days
Tracked from every run. Incidents stay on the record even after they're fixed.