image
Coin

1

free
new

Contact Details Scraper

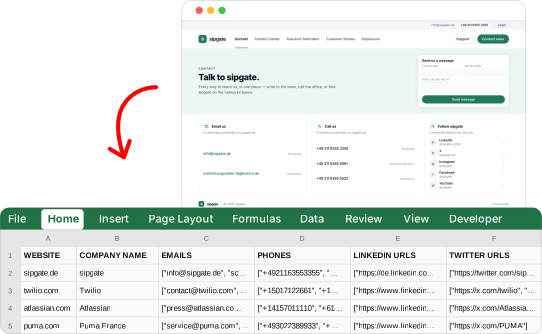
Extract every email, phone & social profile from any company website25 data points per site.

Download sample

Trusted worldwide by the best

Export contacts from Website — right now

Extract

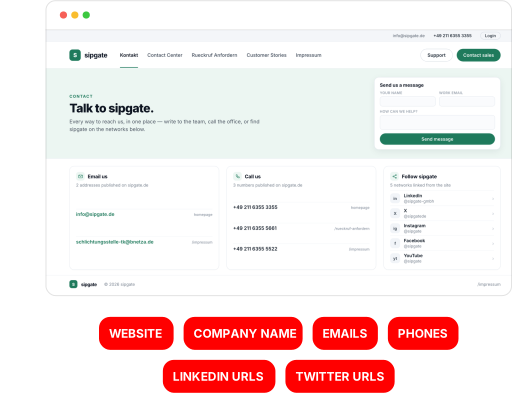
Give it a company website or a bare domain and get back every email address, phone number and social profile on it — 25 data points per site, no login.
image

Schedule

Automate website data collection on daily, weekly, or monthly schedules.

image

Export

Export all contact data to Google Sheets, email, or S3 — fully automated.

image

Built for Agents

Run it from your stack.
Or hand it to your agent.

Contact Details Scraper ships with a Python SDK, a one-line CLI and a native MCP server your agents can plug into directly — no rate limits to dodge, no bot mitigation to bypass, no parsing errors to chase down.

# install once (Python 3.10+)
pip install lobstrio

# check your token
lobstr whoami

# find the scraper
lobstr crawlers search "website"

# one call — launch, wait, download
lobstr go contact-details-scraper \
  "<any website URL>" \
  --param max_results=200 \
  -o results.csv

25 data attributes per contact

Every scrape returns structured data you can export as CSV, JSON, or via API.

website

Normalised website identity of the crawled site, lower-cased with www. stripped

sipgate.de
Export Contact Details
domain

Registrable domain of the crawled website

sipgate.de
Export Contact Details
Company Name

Company or site name, from og:site_name, JSON-LD Organization or the page title

sipgate
Export Contact Details
emails

Email addresses published on the crawled pages, Cloudflare-protected and (at)-obfuscated addresses decoded

[
  "info@sipgate.de",
  "presse@sipgate.de"
]
Export Contact Details
phones

High confidence phone numbers, from tel: links, JSON-LD telephone and validated page text

[
  "+4921117071000"
]
Export Contact Details
Phones Uncertain

Phone-shaped values that failed validation, kept apart so they never pollute the main phone list

[
  "035500000000002"
]
Export Contact Details
Linkedin Urls

Company LinkedIn pages (/company/, /school/, /showcase/)

Export Contact Details
Linkedin Personal Urls

Personal LinkedIn profiles (/in/) found on the site, usually staff members

Export Contact Details
Twitter Urls

Twitter / X profile URLs

Export Contact Details
Instagram Urls

Instagram profile URLs

Export Contact Details
image

Fast

9 contacts per minute
Lightning-fast performance

image

Solid

99.95% task success rate
Dependable, reliable data every time

image

Cost-competitive

$0.5 per 1000 contacts
Top affordability worldwide

Live

Built to run.

Most scrapers break in silence. This one doesn't — and we show it, openly.

100.00%

incident-free runs · last 90 days

0
incidents · 90 days
100%
resolved
median time to fix
90 days agoToday
Operational
Degraded
Down
Resolved incident
Open incident
How we measure →

Tracked from every run. Incidents stay on the record even after they're fixed.

Simulator plan

Trusted by the best

Used obsessively by the data-hungry around the world

★★★★★
★★★★★
★★★★★
★★★★★
★★★★★
★★★★★

Frequently Asked Questions

Is it legal to scrape contact details from a website?

Yes — an address printed on a public web page is public data. We only read what any visitor can open: no login, no paywall, no private area. What you do with it afterwards is on you — keep outreach relevant and honour opt-outs. More in our guide to the legality of web scraping.

Do I need a login or an account on the sites I scrape?

None. Zero. Nada. No account to sync, no cookie to paste, no Chrome extension to install. Paste your list of websites and the crawler is away — which is rarer than it sounds for a contact scraper.

What data do I get for each website?

25 data points per website. Company name, domain, every email address, every phone number, LinkedIn company and personal profiles, and links to twelve more social networks — plus a status telling you how the crawl went.

How fast is it?

About 9 websites a minute. And a website here is not one page — it is a whole site crawled up to ten pages deep, so a 1,000-company list is done long before you have finished writing the outreach email.

Which pages does it actually read?

The homepage first, then anything that smells like a contact page. About, imprint, legal notice — and the usual contact paths even when nothing links to them. Ten pages per site by default: raise it, lower it, or stick to the homepage alone.

What happens when a site publishes no email address?

You still get the row, plus a status that explains it. A company hiding behind a web form comes back with phone numbers and social profiles but no email; a site that blocks crawlers comes back unreachable. Nothing is ever invented.

Does it find social media profiles too?

Fourteen networks, each in its own column. LinkedIn company and personal profiles stay apart, and X, Instagram, Facebook, YouTube, TikTok, Pinterest, Threads, Telegram, WhatsApp, Discord, Snapchat and Reddit each get a column of their own.

How many websites can I scrape in one go?

As many as you like — one row comes back per website. Paste a list, upload a CSV or push them through the API. Cap a run with Max Unique Results when you only want a taste, and let sister domains through for groups that publish their imprint elsewhere.

Where can I send the data once it is scraped?

Just about anywhere you already work. Google Sheets, Make, n8n, Amazon S3, email, webhooks — plus our MCP server, so Claude or ChatGPT can launch a run and read the results for you. CSV, Excel and JSON downloads too. See all integrations.

Can I keep the same list fresh automatically?

Yes — daily, weekly or monthly, on the same list. Set the schedule once and your CRM refreshes itself while you sleep. Useful in a market that keeps hiring, rebranding and quietly changing its phone number.

Ready to get started?

Export your first contacts for free.

Contact sales